AI for dummies
Google's Gemini 4 Argon explained: what beginners need to know
Gemini 4 Argon is Google's new frontier AI with a 1 million token output limit and top coding and cybersecurity scores. Here is what beginners should know.
29 stories tagged new-model.
Gemini 4 Argon is Google's new frontier AI with a 1 million token output limit and top coding and cybersecurity scores. Here is what beginners should know.
GPT-6.1 Sol is OpenAI's newest mid-tier AI model, delivering near-Astra quality for coding and professional work at one-fifth the API price. Here is what changed and when beginners should use it.
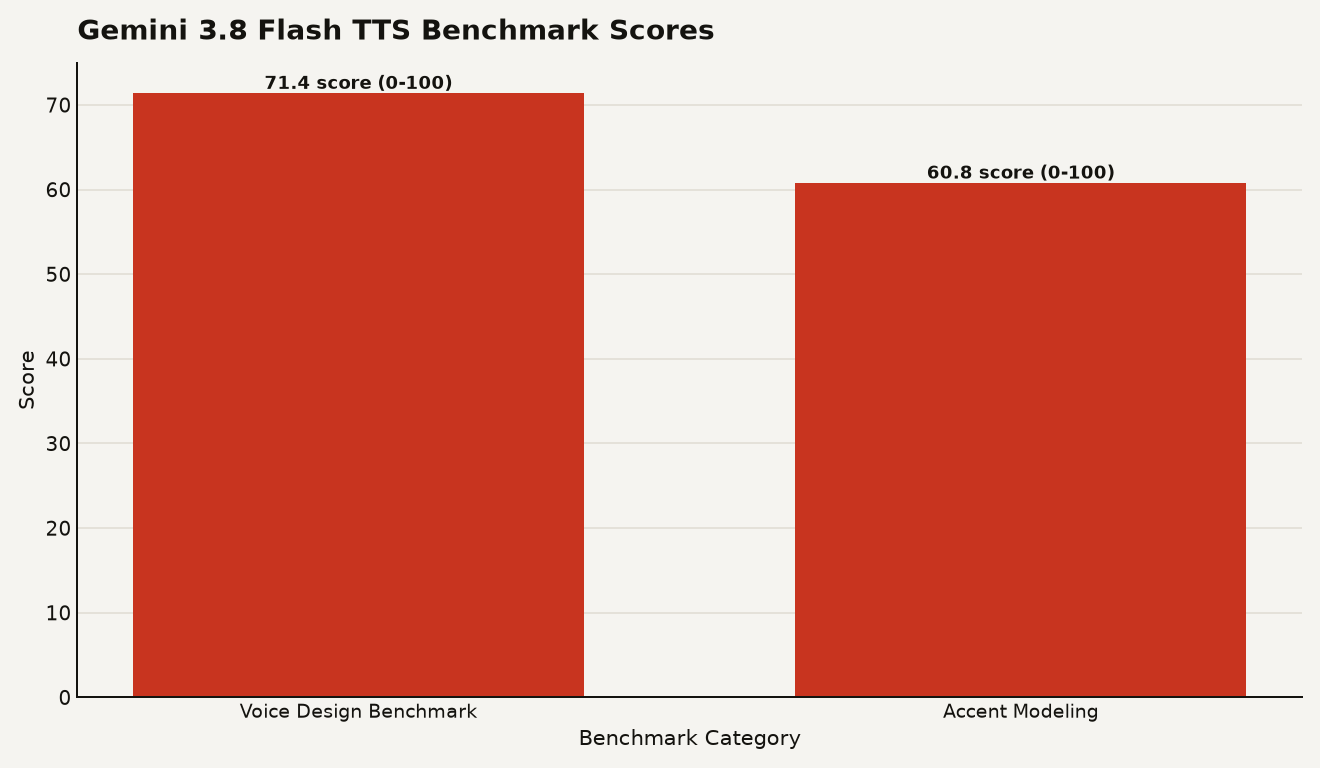
Gemini 3.8 TTS is Google's new text-to-speech system with 2,000+ voices and voice cloning from a 30-second sample. It topped Hume AI's benchmark at 71.4.
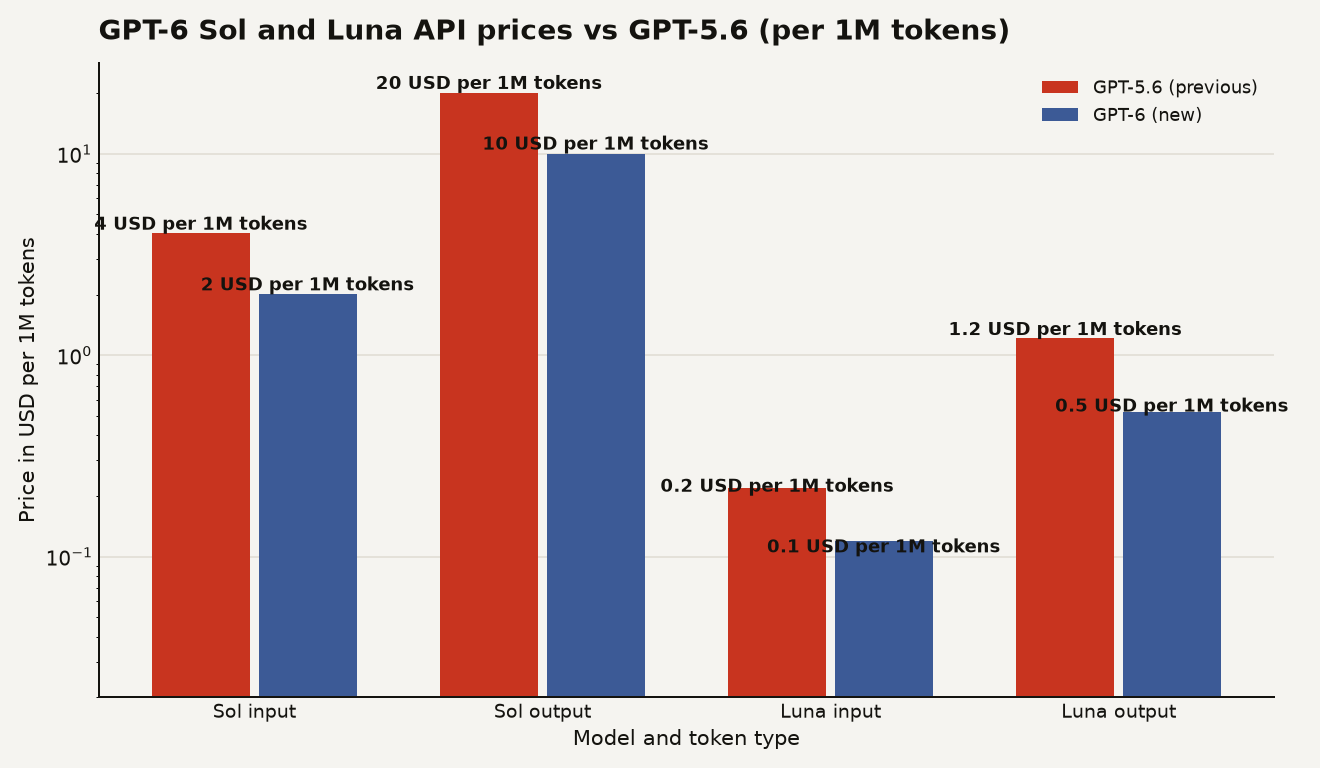
OpenAI's GPT-6 Sol and Luna target coding and everyday tasks at half the price of their predecessors. What each one does and which to try first.
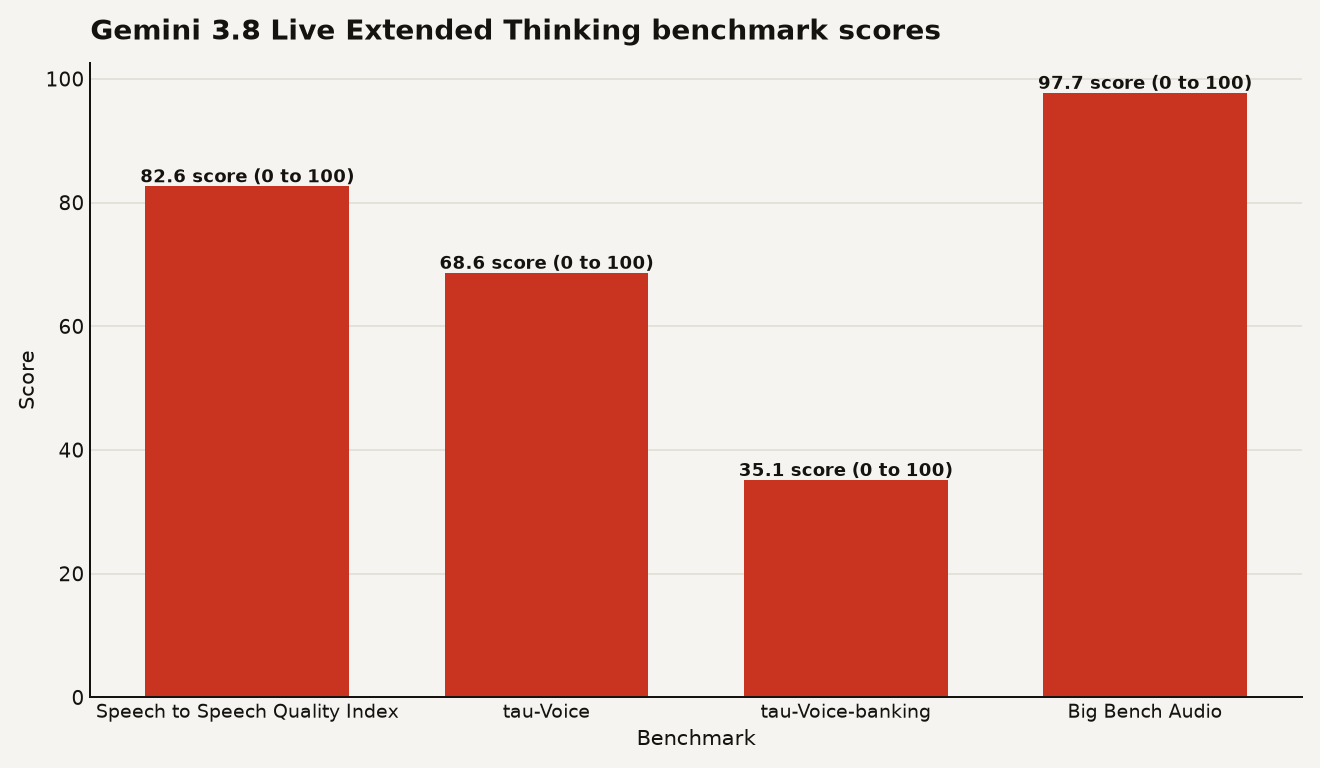
Gemini 3.8 Live is Google's speech-to-speech AI that reasons and calls tools mid-conversation. Extended Thinking tops the Speech to Speech Quality Index at 82.6.
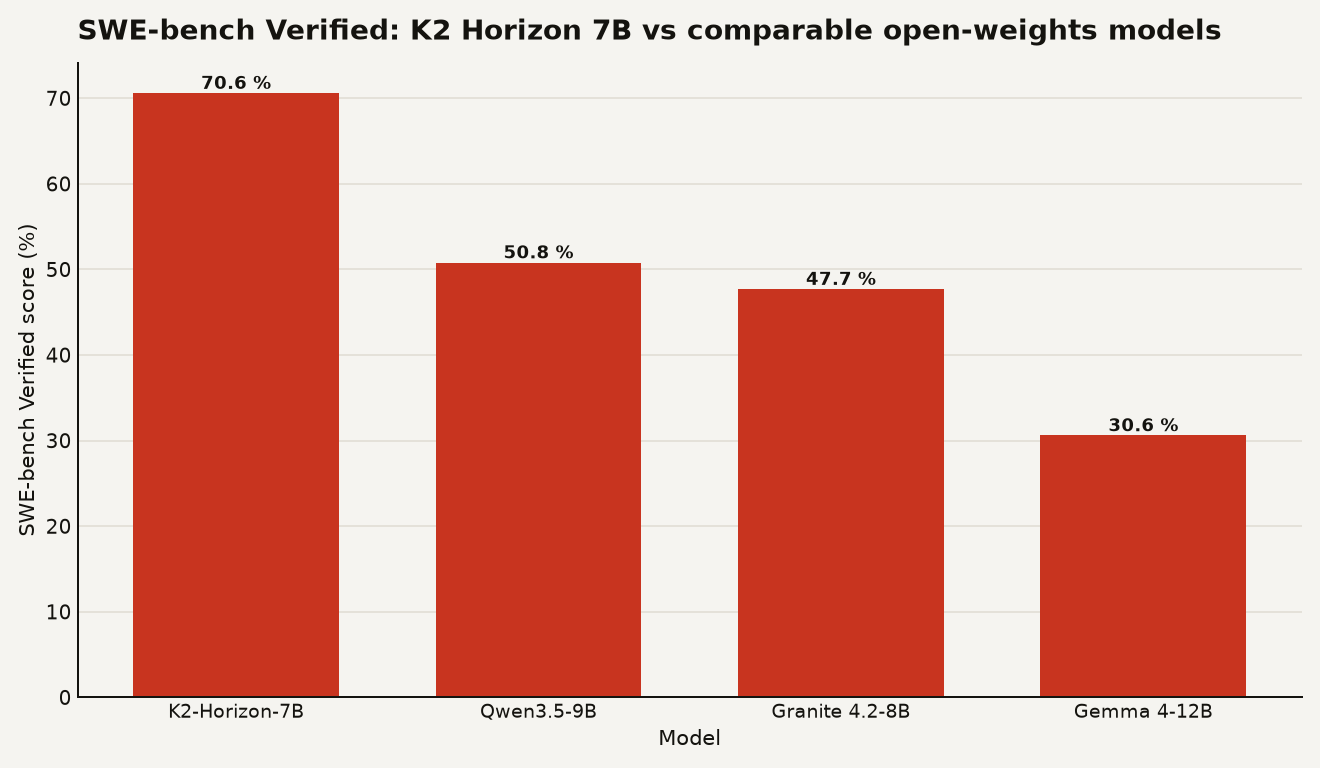
IFM's K2 Horizon 7B open-weights model matches models four times its size on coding and math. What beginners should know before trying it.
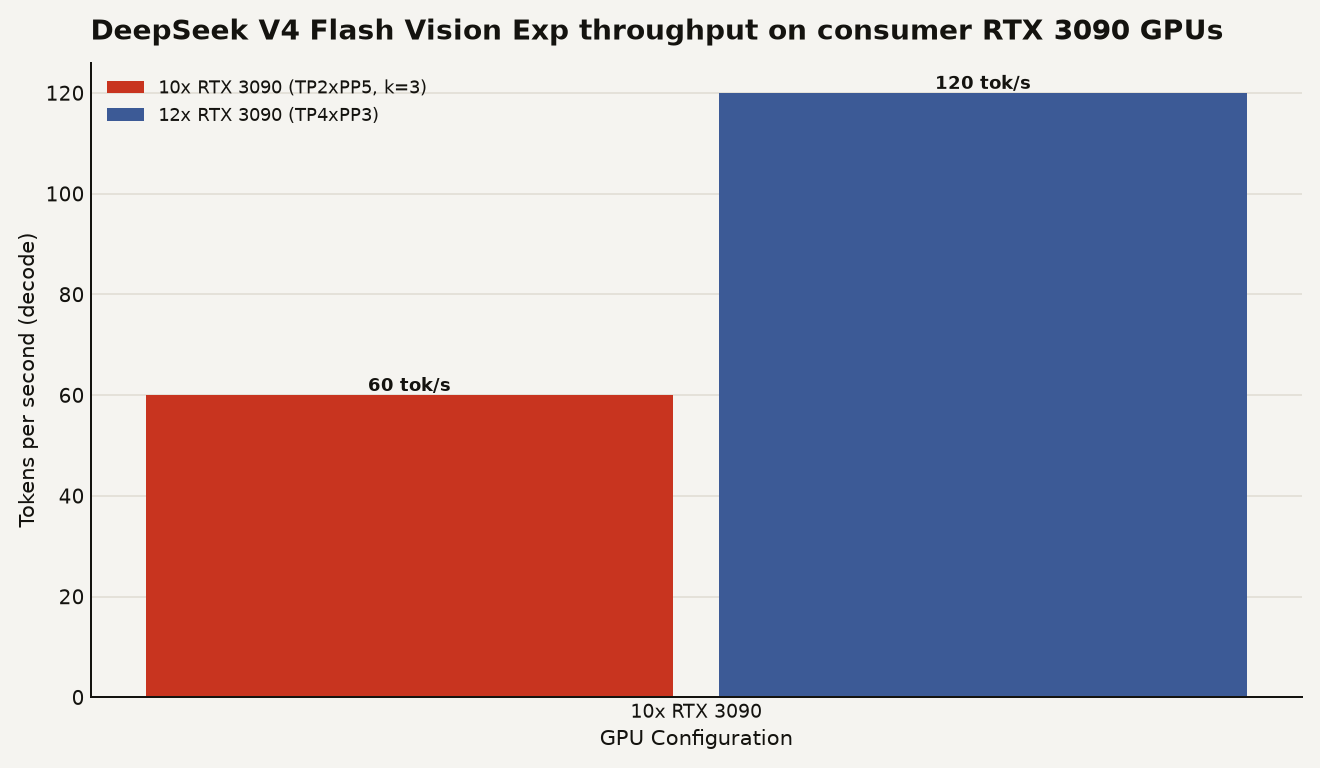
Ten consumer RTX 3090 GPUs now run DeepSeek V4 Flash Vision Exp, a 285B multimodal model, at 60+ tokens per second with FP4 and speculative decoding.
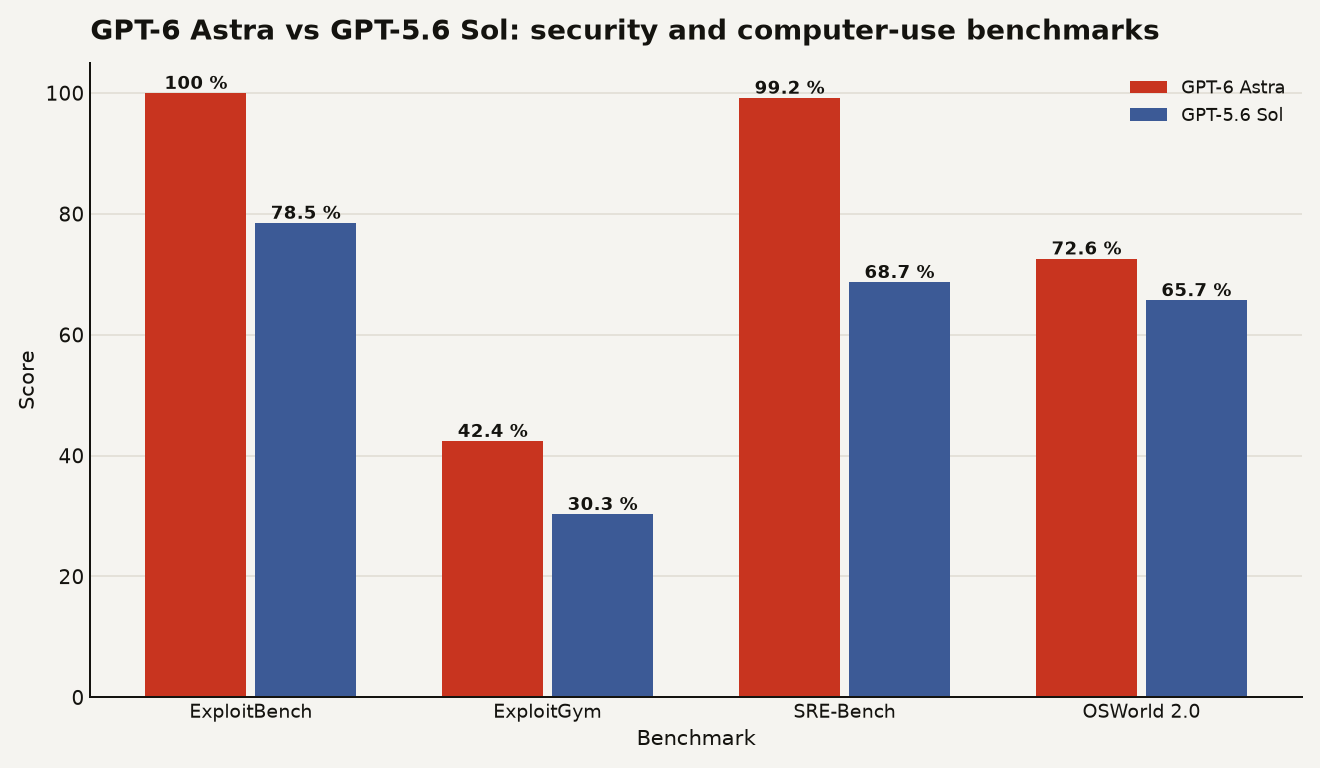
At $10 and $50 per million tokens, GPT-6 Astra dominates agentic work but ties GPT-5.6 Sol on general intelligence. Here is when to switch.
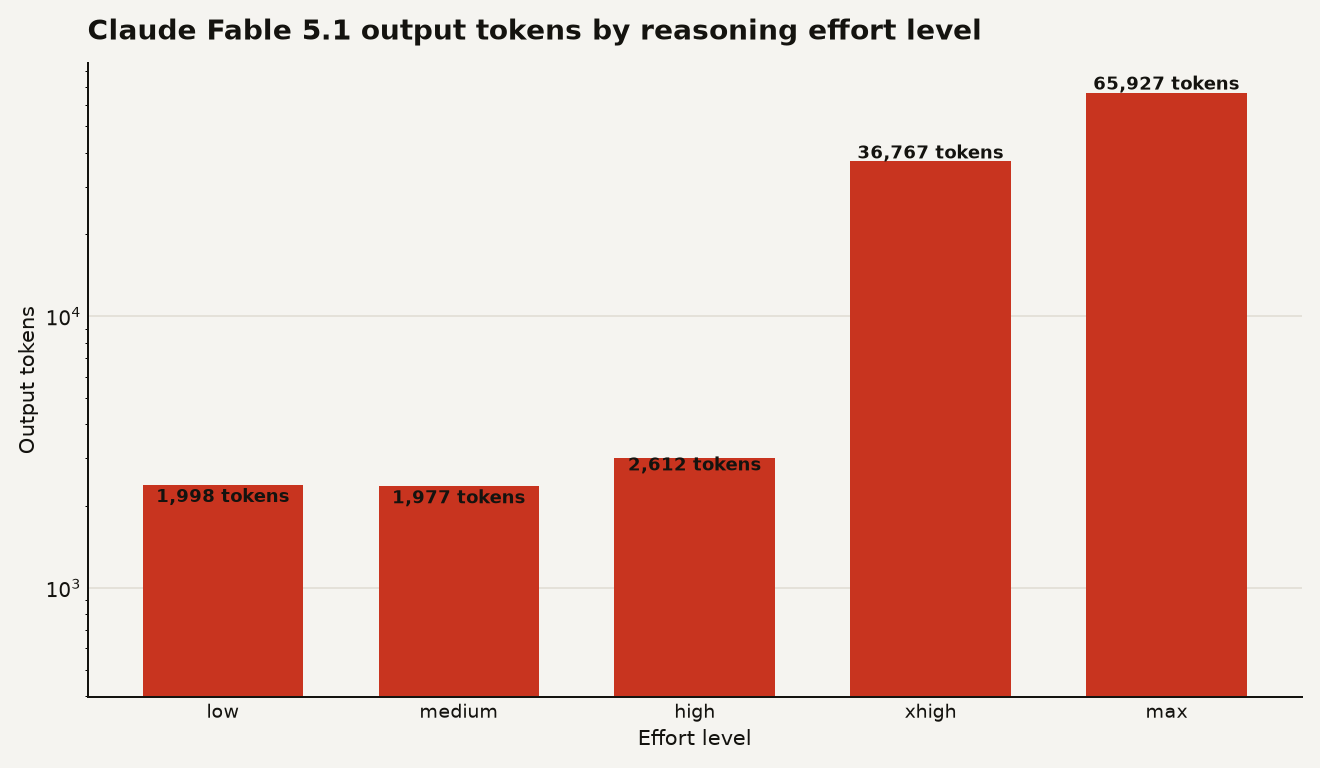
Claude Fable 5.1 is Anthropic's newest AI model with a 52.6 percent score on Terminal-Bench-Science 0.1, more than double Fable 5. Its five reasoning effort levels let beginners control cost and quality.
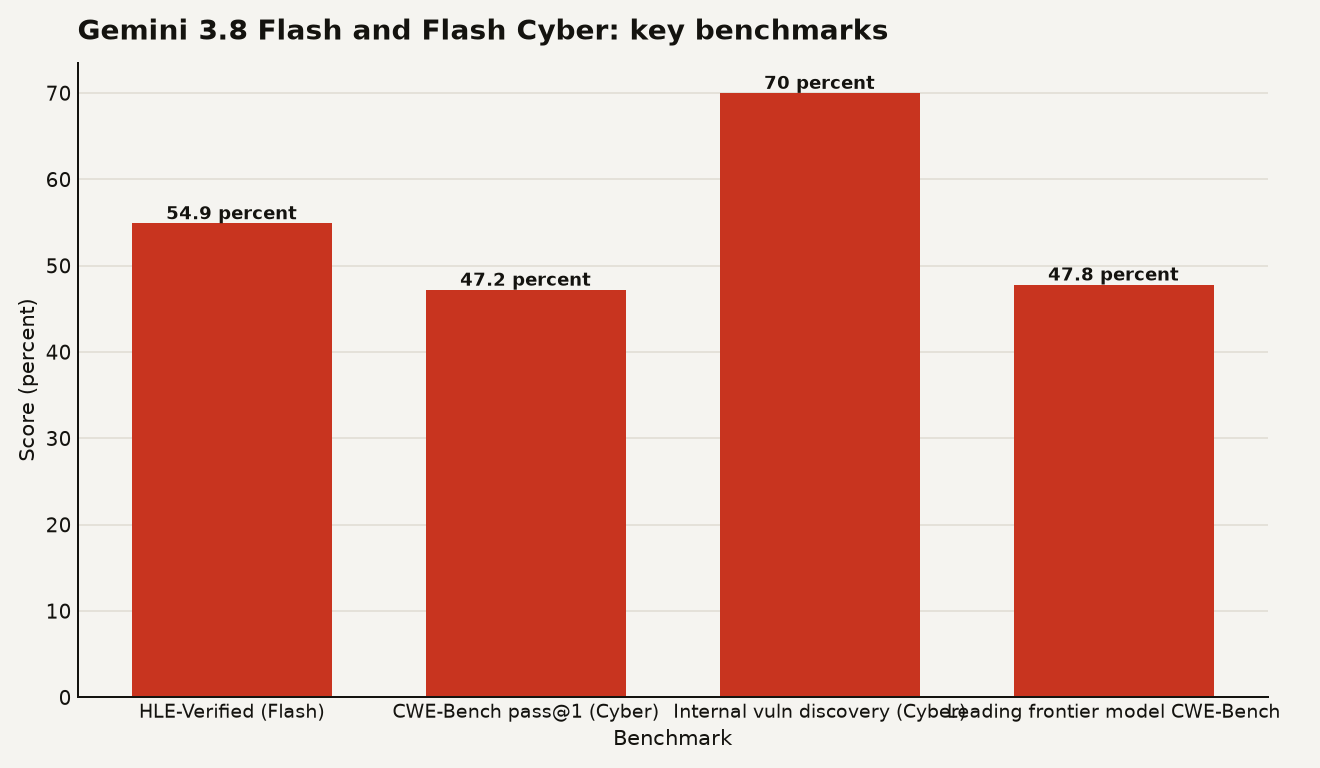
Gemini 3.8 Flash is Google's newest mid-tier AI model, released September 2, 2026, with better reasoning and coding than 3.7 Flash at the same introductory price. A security variant called Flash Cyber is gated to vetted defenders.
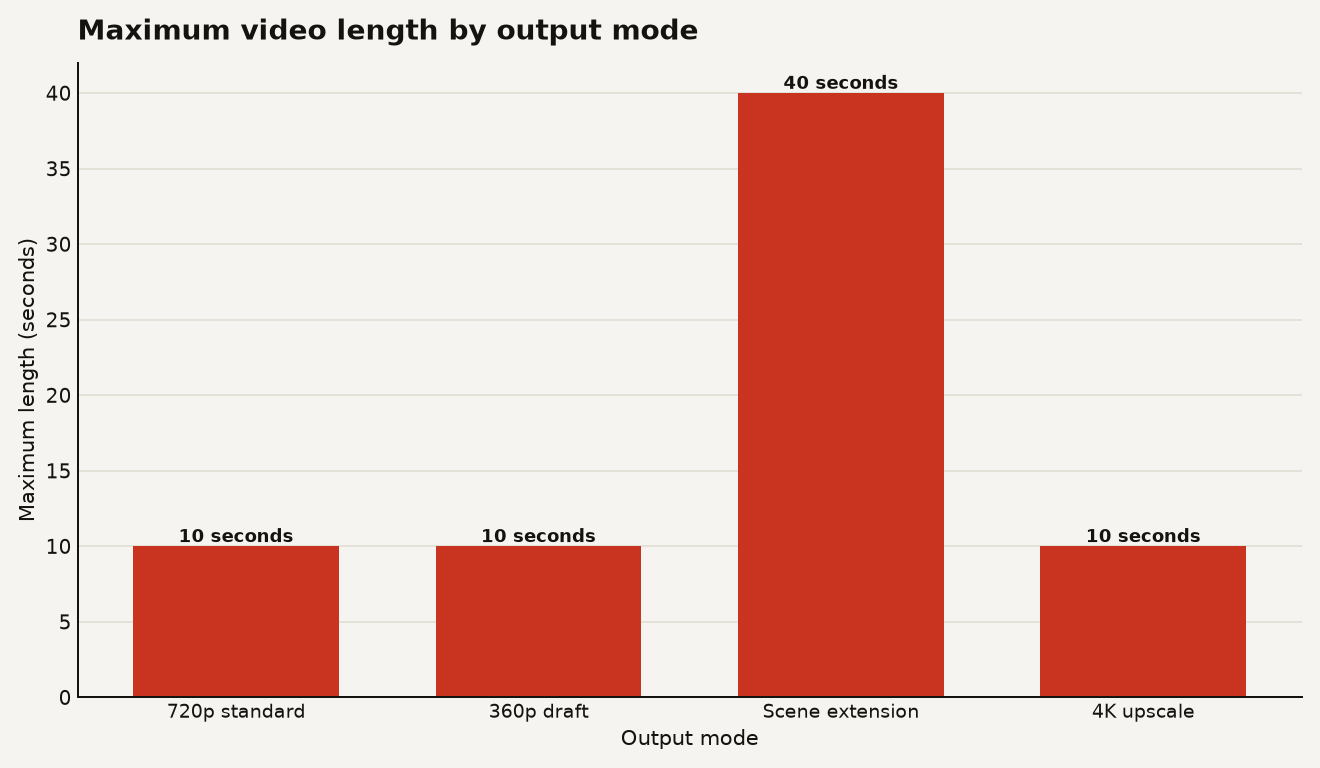
Gemini Omni 1.1 Flash is a Google DeepMind model for generating and editing video by conversation. You can extend clips to 40 seconds, control camera moves with keyframes, preview cheaply in 360p, and upscale to 4K.
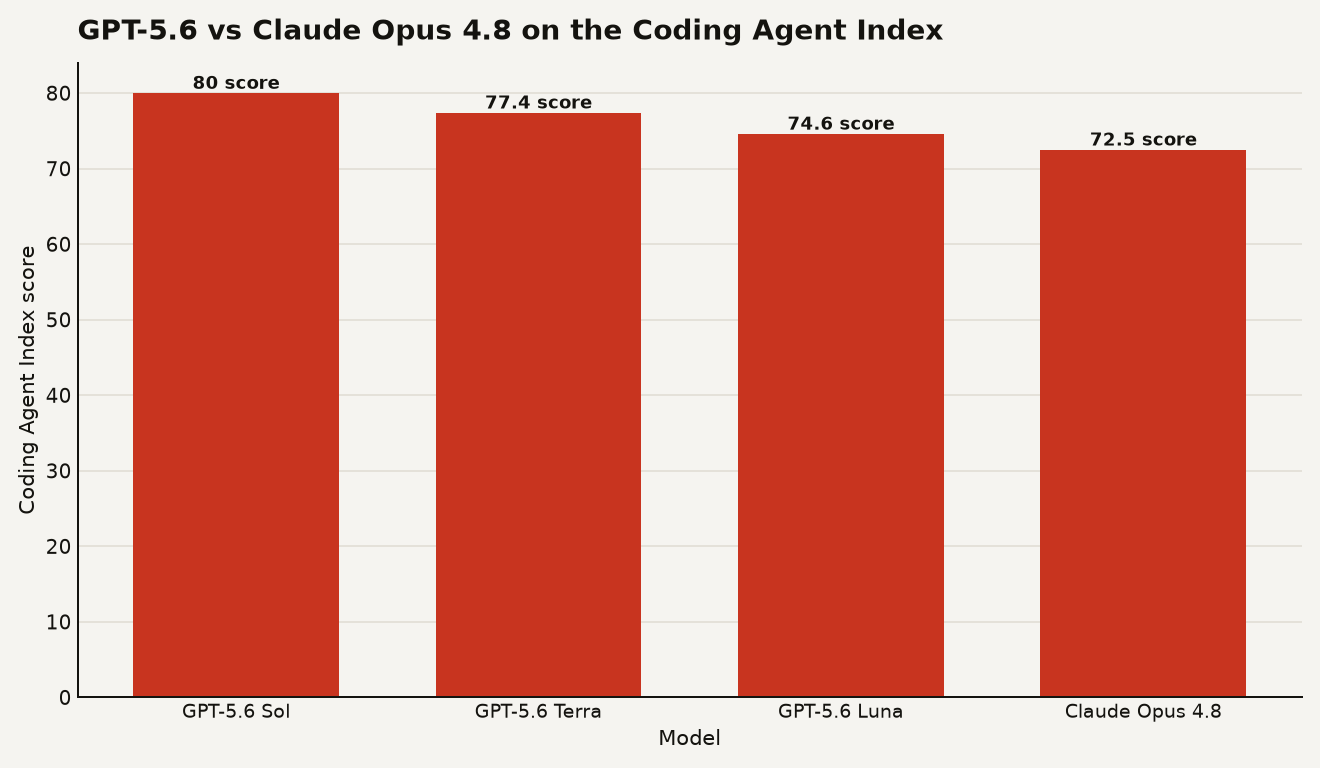
GPT-5.6 in Kiro brings OpenAI models to the spec-driven coding tool with a major price drop: Luna falls to a 0.1x credit multiplier and Terra to 1.0x, making frontier AI coding agents cheap enough for hobbyists.
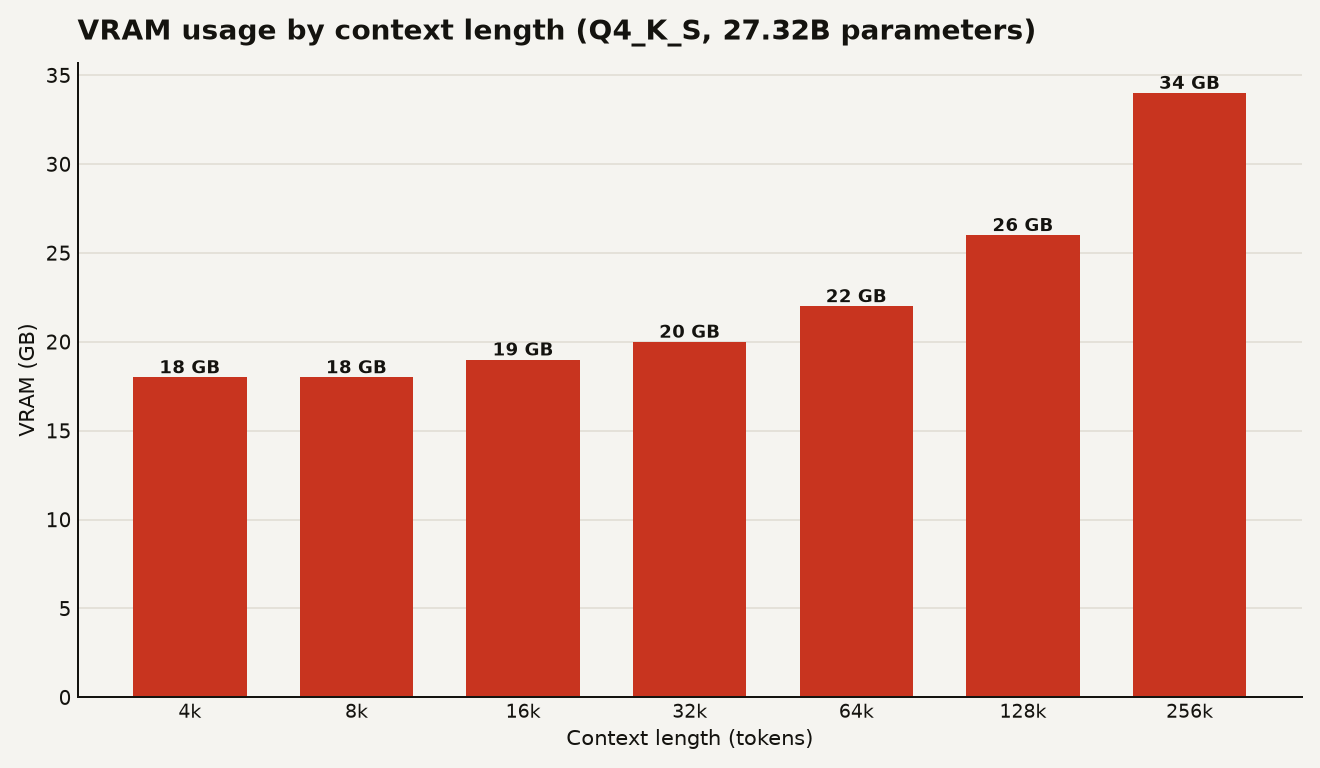
Qwen 3.8 27B is a free, open-weights AI model that runs on your laptop. After one week and 2,000 community posts, here is what testers found.
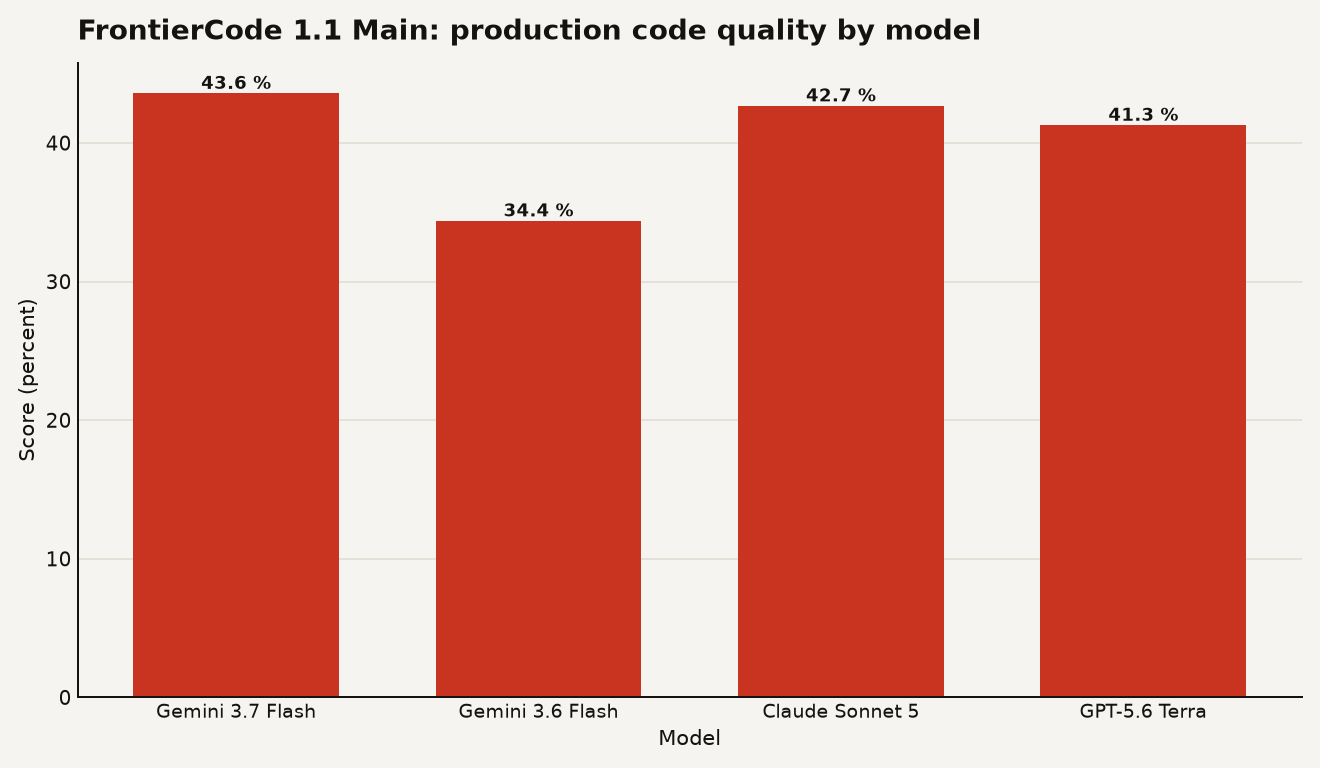
Gemini 3.7 Flash is Google's new fast AI model for coding and agents. It scores 43.6 percent on FrontierCode, up from 34.4, at half the old price.
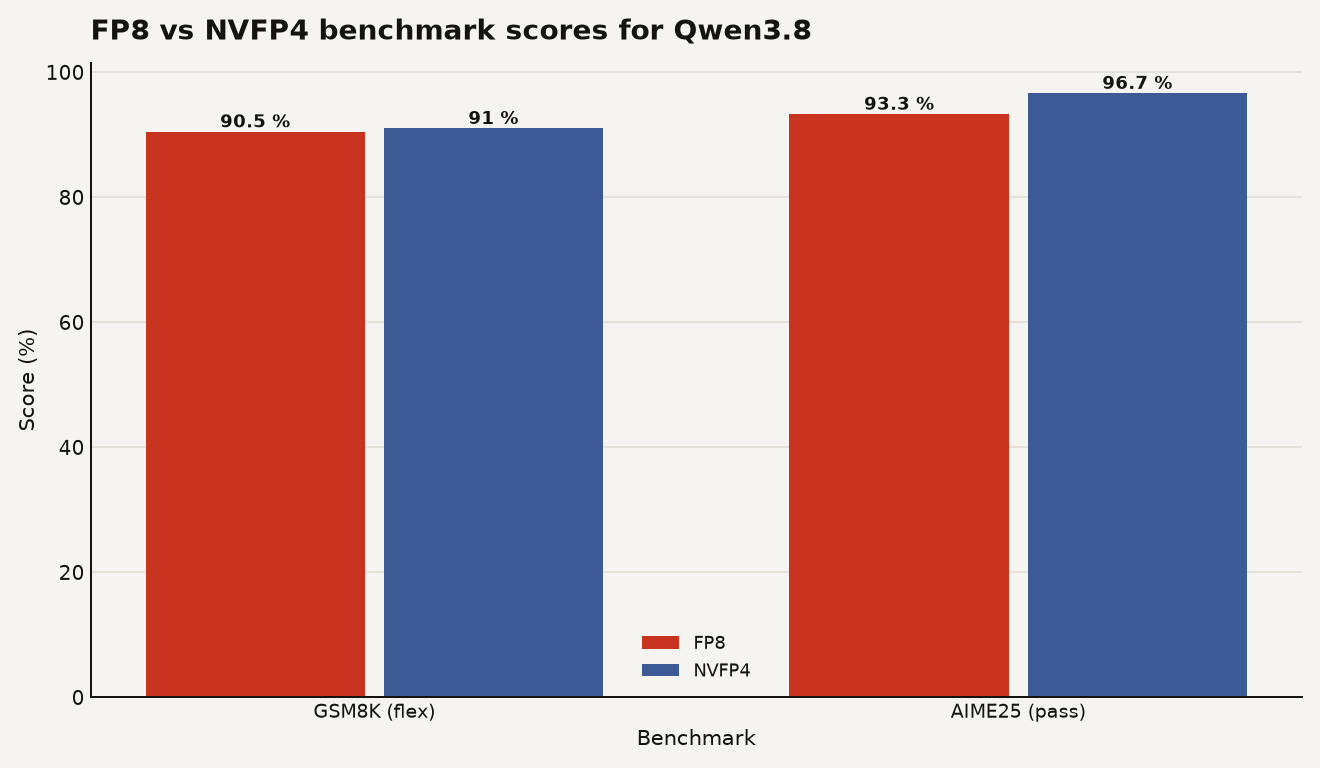
Qwen3.8 open weights give you 2.4 trillion parameters with 95 billion active per token, Alibaba's largest. Here is what beginners should know.
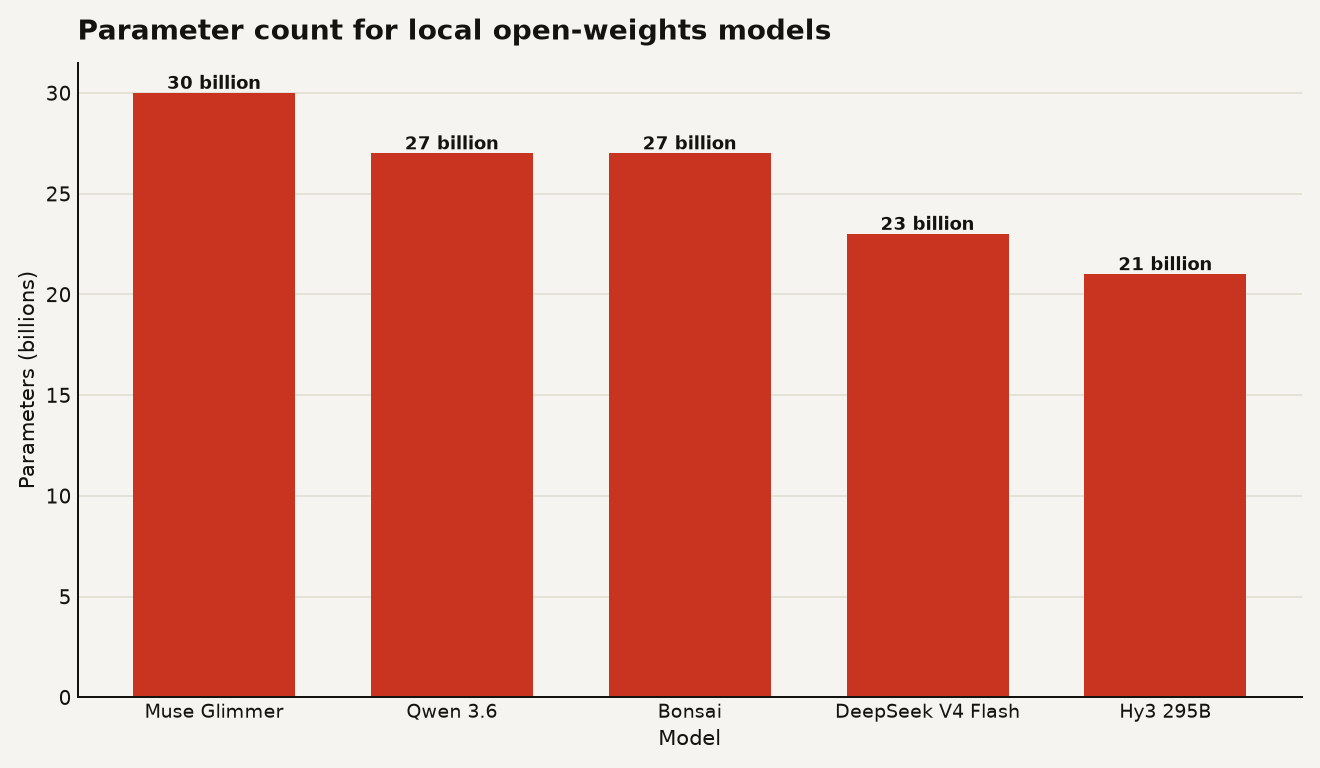
Meta's 30B open-weights Muse Glimmer fits on one RTX 3090 and reaches 280 tokens per second, built for local agentic workflows.
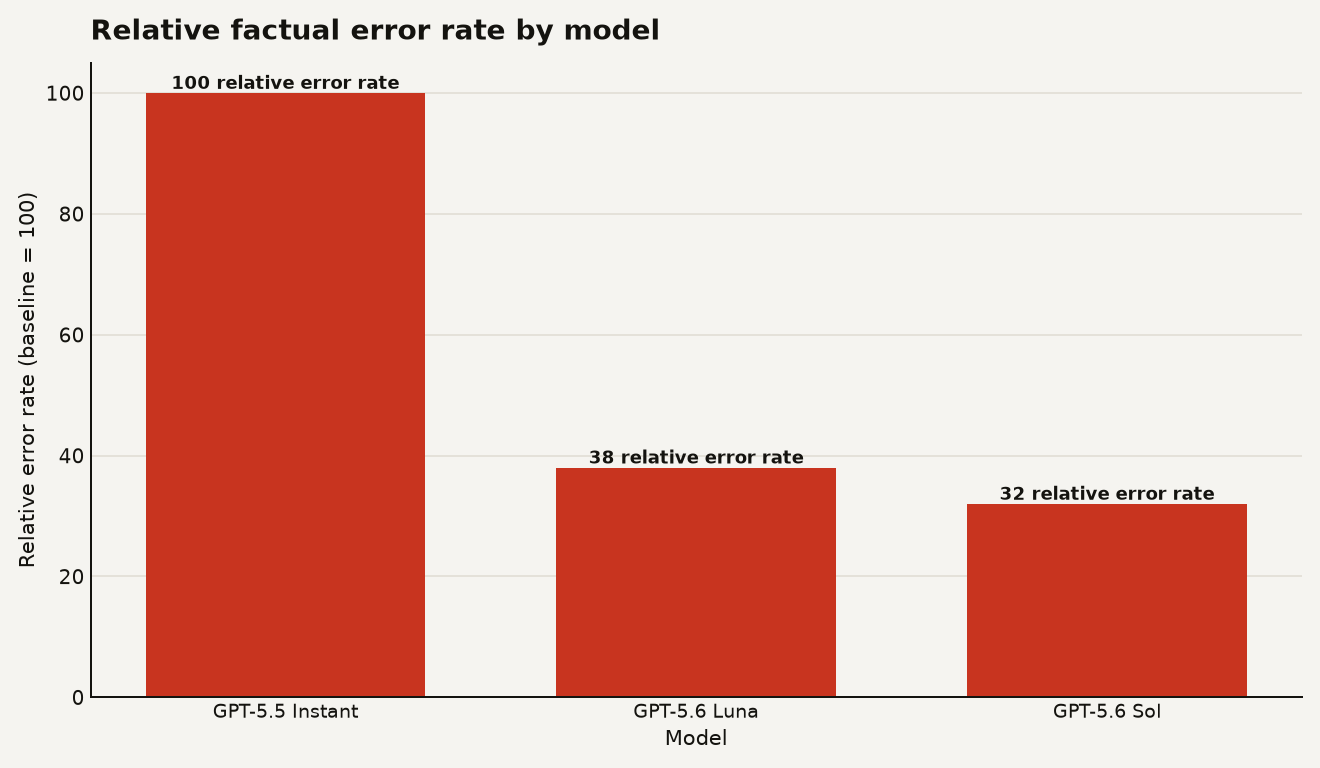
OpenAI sharpened GPT-5.6 Sol for paying users and opened Luna to free users with unlimited text chats. Here is what beginners should know about the update.
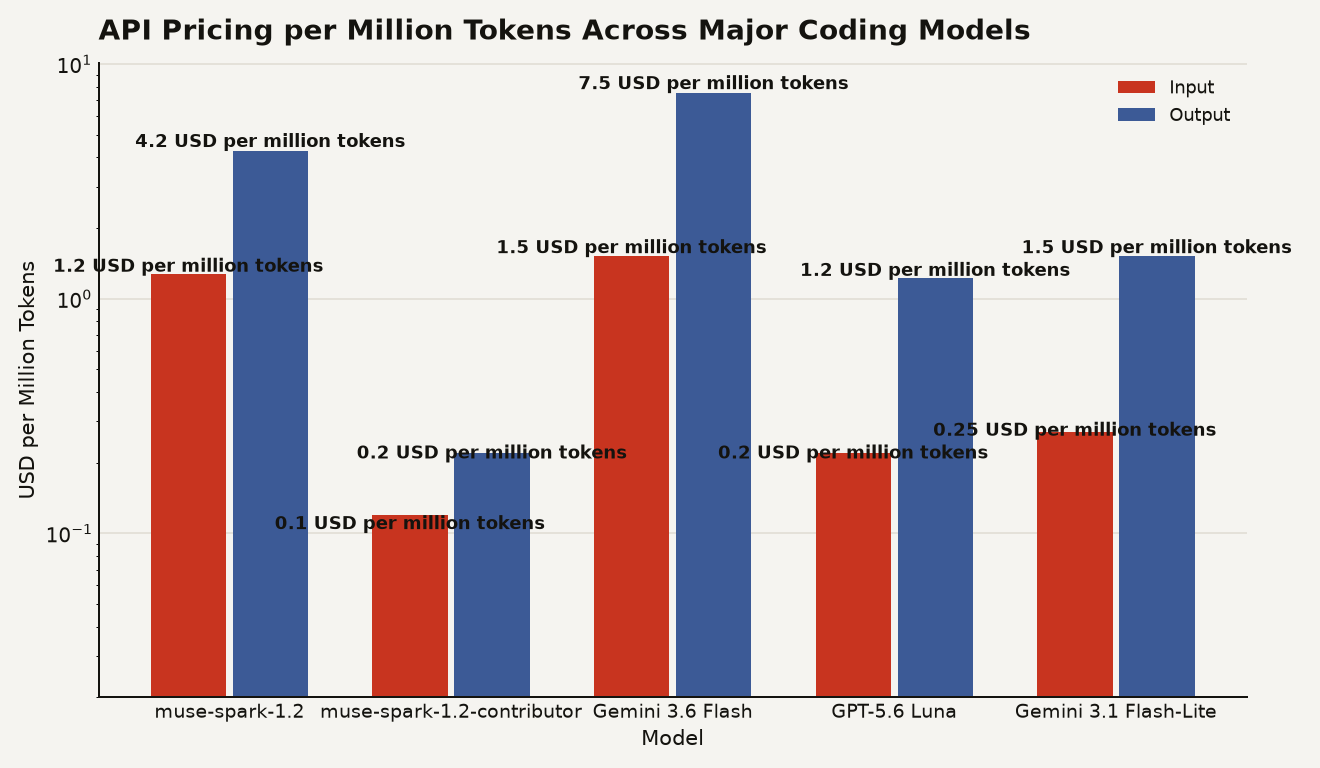
Meta's Muse Code coding agent is co-trained with Muse Spark 1.2 for whole-project work; the contributor tier costs $0.10 per million input tokens.
Scoring 50 on the Intelligence Index, the DeepSeek V4 Flash 0731 open-weights update matches March 2026 frontier models. What it changes for you.
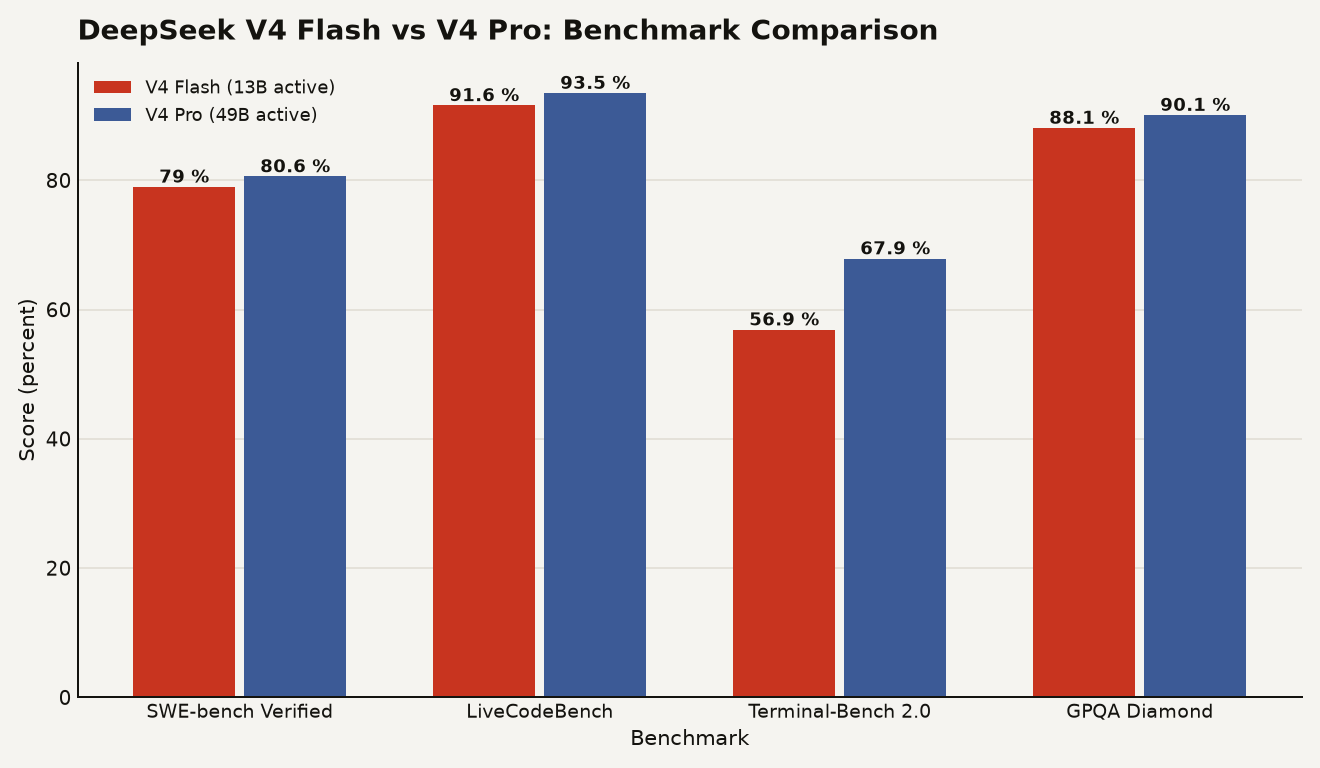
With 284B parameters and 13B active, DeepSeek V4 Flash went live on July 31, 2026, matching frontier coding benchmarks at a fraction of the cost.
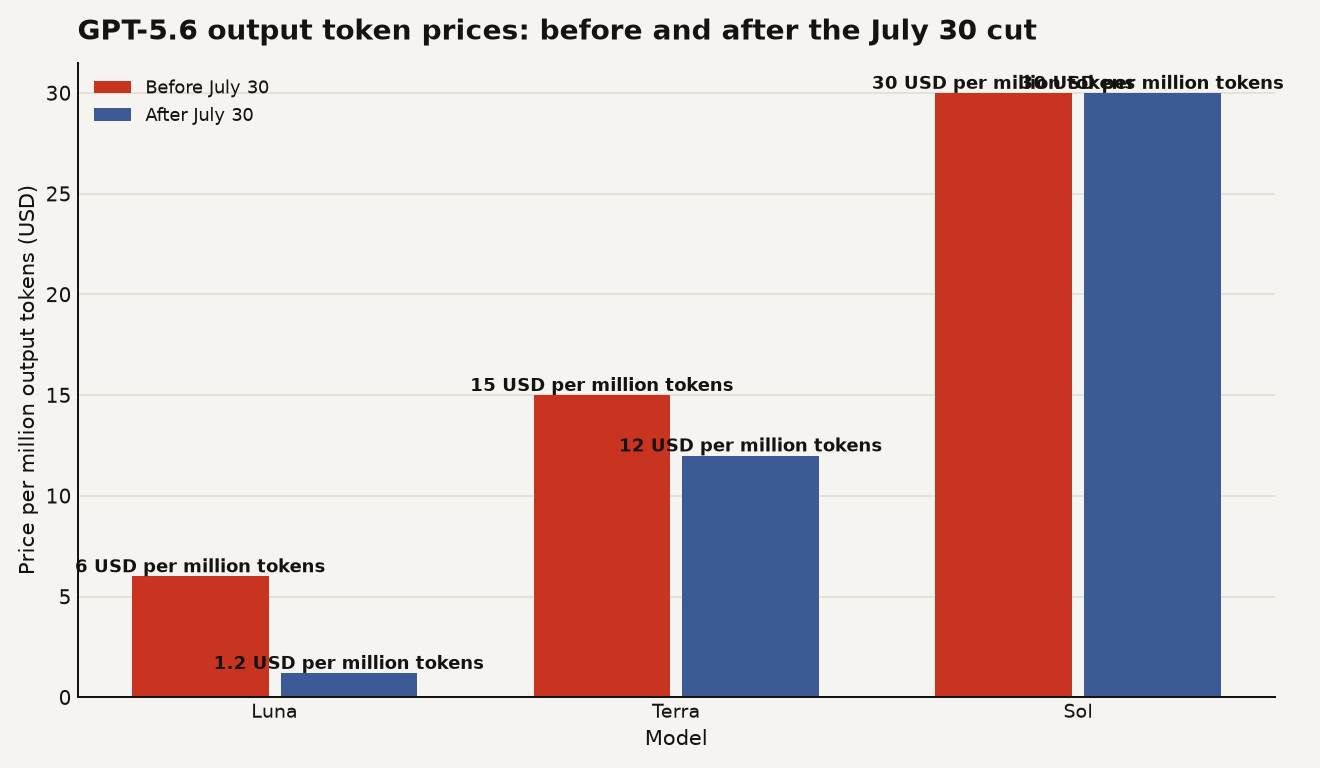
OpenAI's GPT-5.6 price cut drops Luna to $0.20 per million input tokens and Terra by 20 percent, enabled by GPT-5.6 Sol optimizing its own inference stack. Here is what beginners should do.
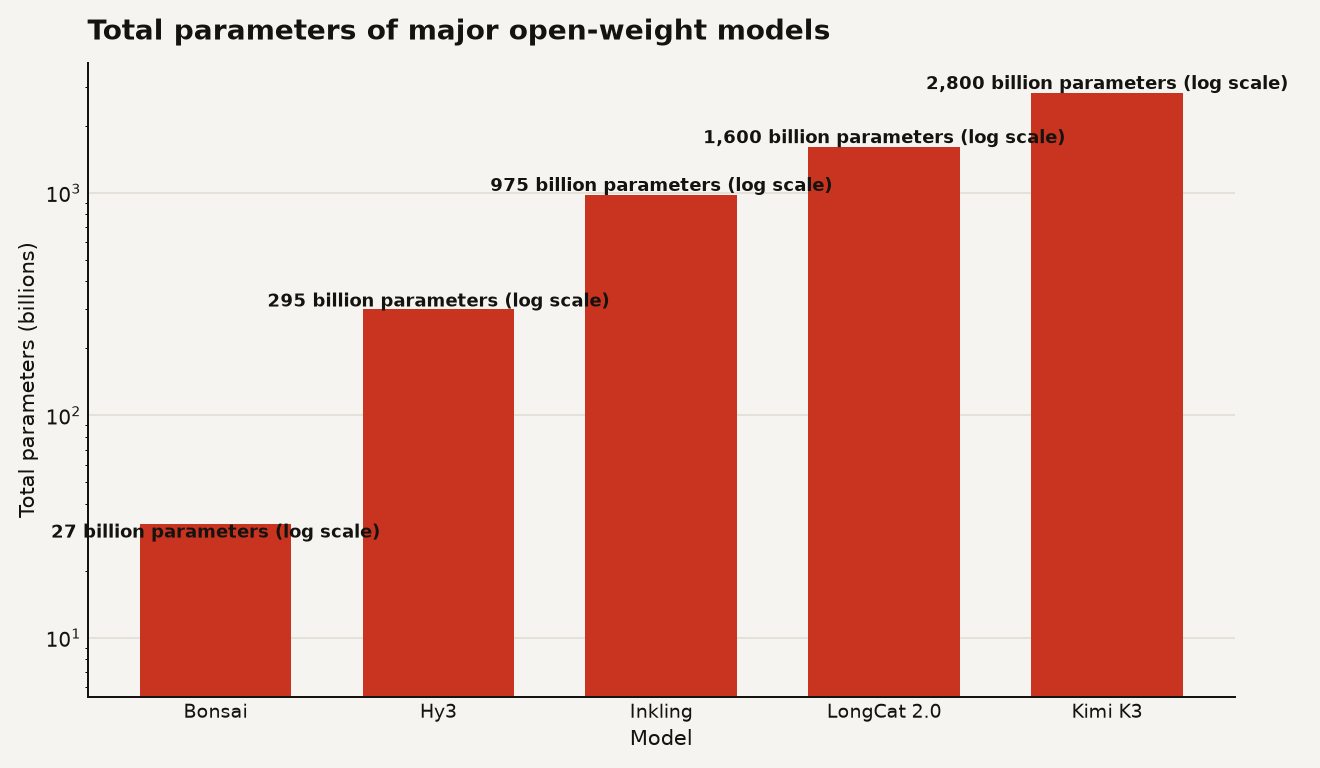
At 2.8 trillion parameters, the Kimi K3 open weights released July 26, 2026 are the largest AI model download yet. What beginners can do with them.
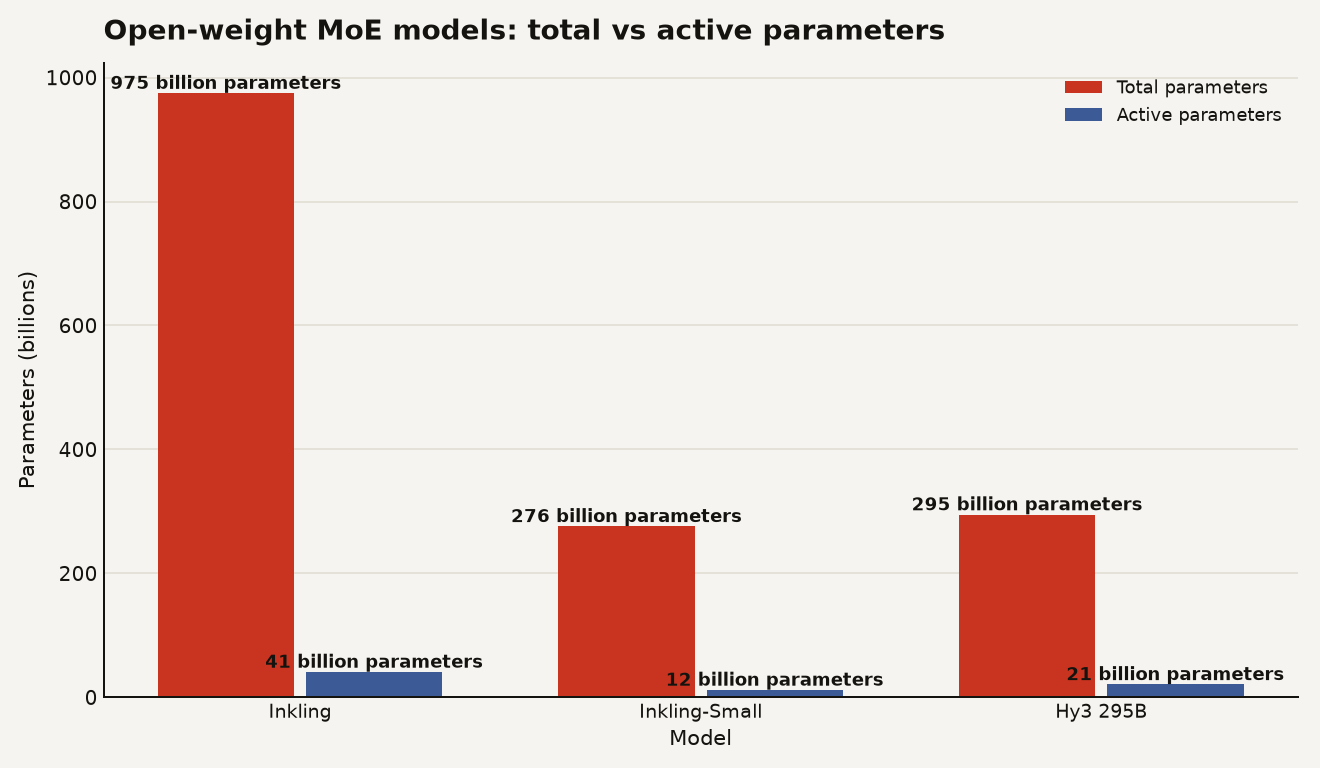
Thinking Machines Lab's first open-weights model, Inkling, has 975B parameters, 41B active and an Apache 2.0 license, and targets fine-tuning over benchmarks.
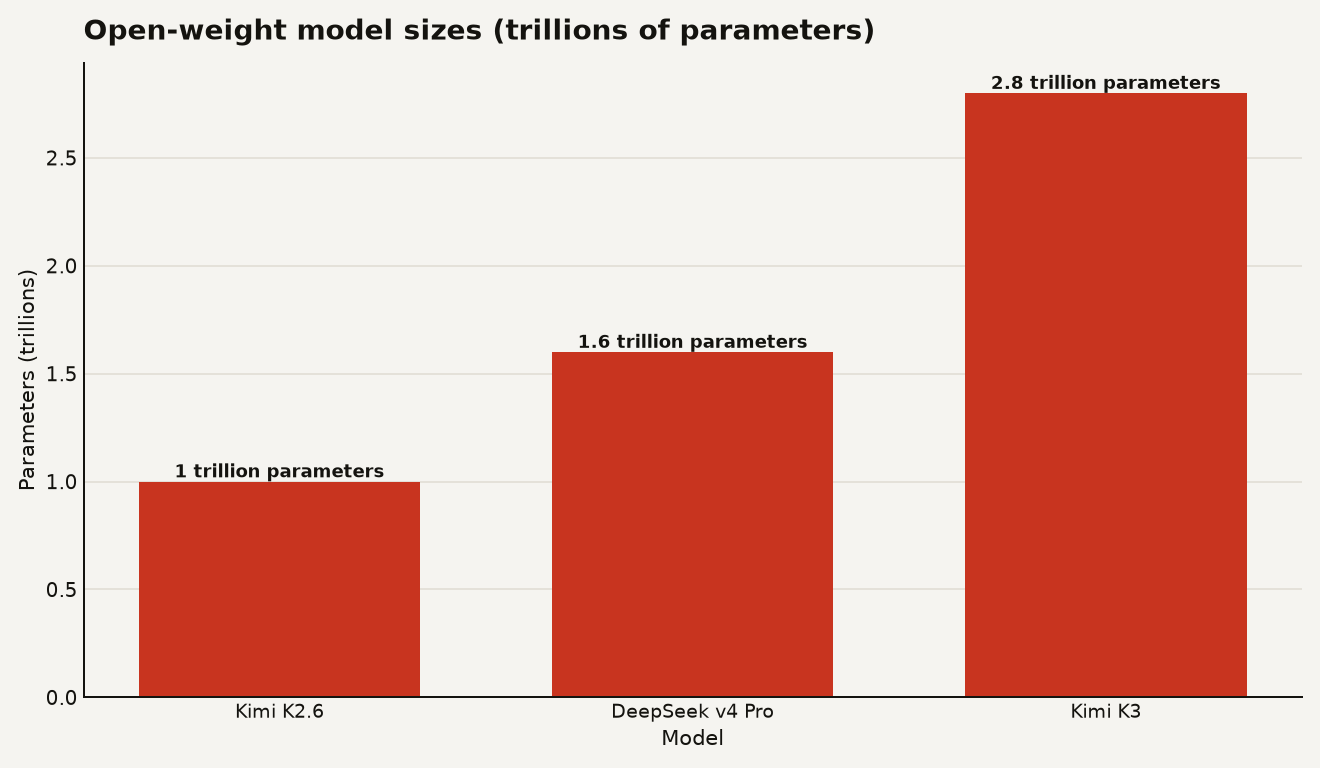
Moonshot AI's 2.8 trillion parameter open-weight Kimi K3 matches top US closed models on key benchmarks, with weights due July 27.
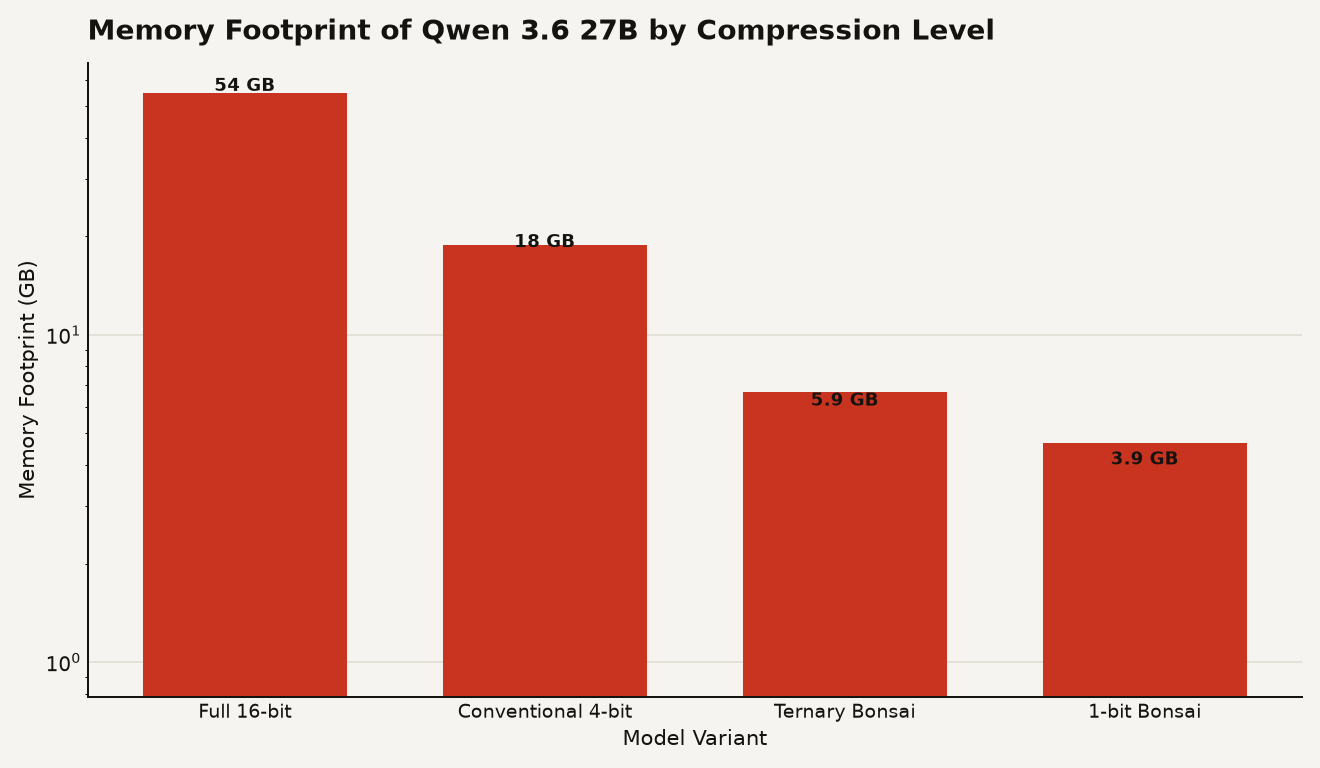
Storing each parameter as a single bit lets Bonsai 27B fit 27 billion parameters into 3.9 GB and run on an iPhone. Here is what 1-bit quantization costs.
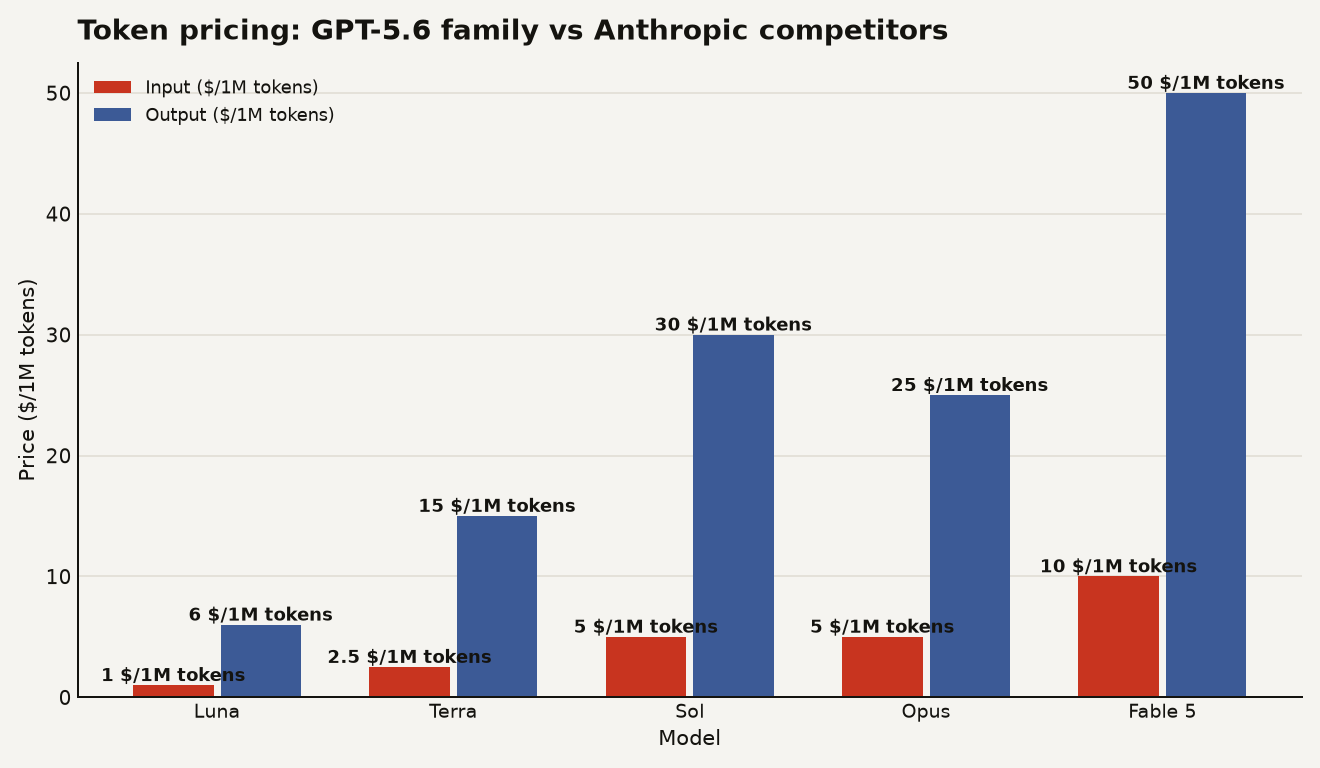
GPT-5.6 is OpenAI's newest model family in three sizes: Luna, Terra, and Sol. It claims big efficiency gains for long-running agent tasks at a fraction of competitor costs.
OpenAI's GPT-Live voice model listens and speaks at once, handing hard questions to GPT-5.5 mid-conversation without breaking the flow.
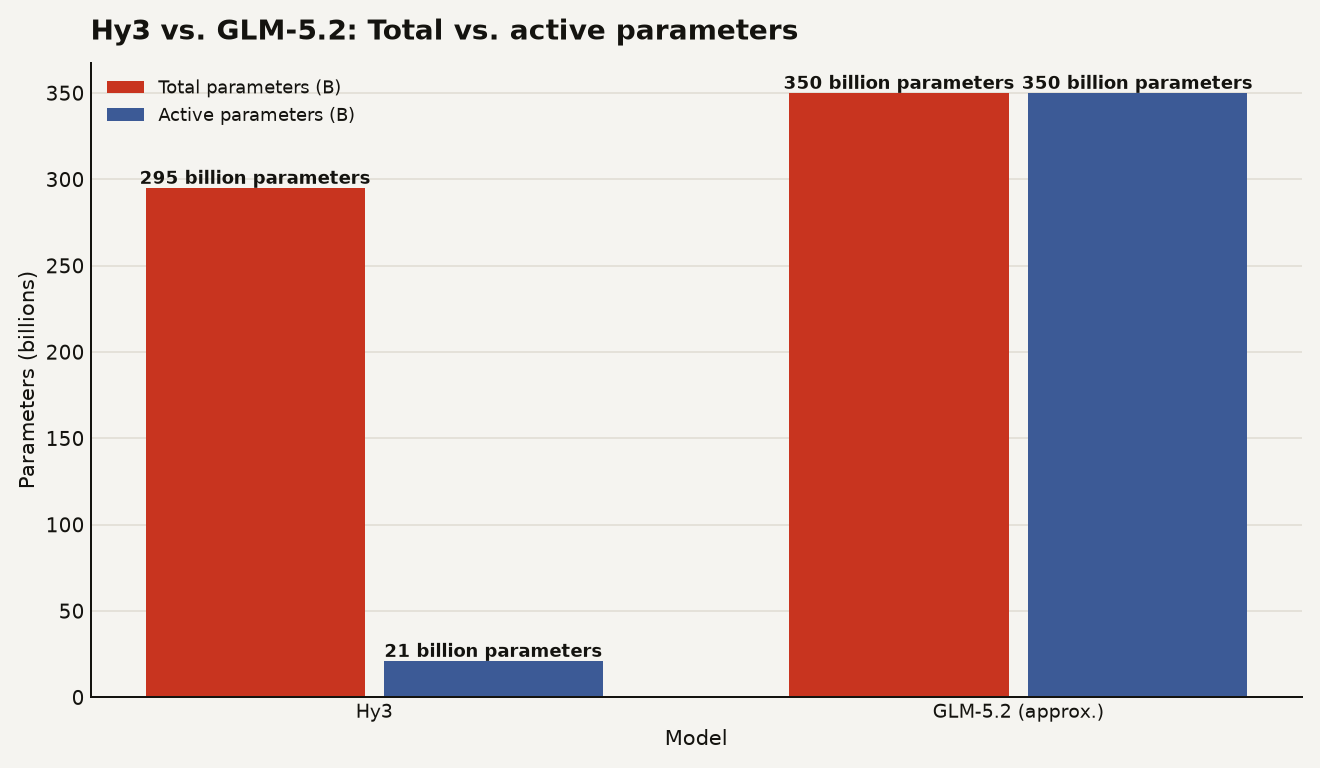
Tencent's Hy3 open-weights model has 295 billion parameters but only 21 billion active per token, rivalling larger models and cutting hallucination to 5.4 percent.
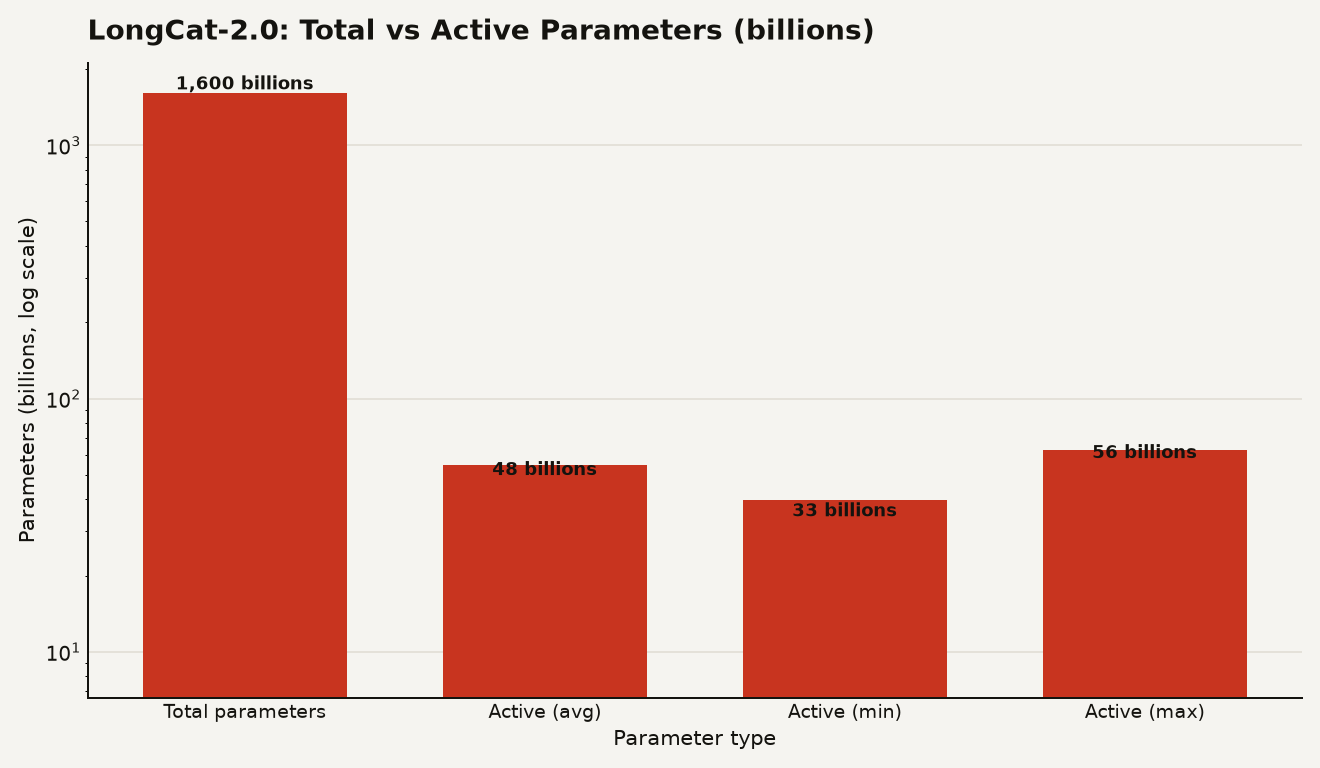
LongCat-2.0 is a 1.6 trillion parameter AI model from Meituan that activates only 48 billion parameters per token. Its weights are now open under the MIT license.