Engineering
Transformers GGUF inference nears llama.cpp speed on Mac
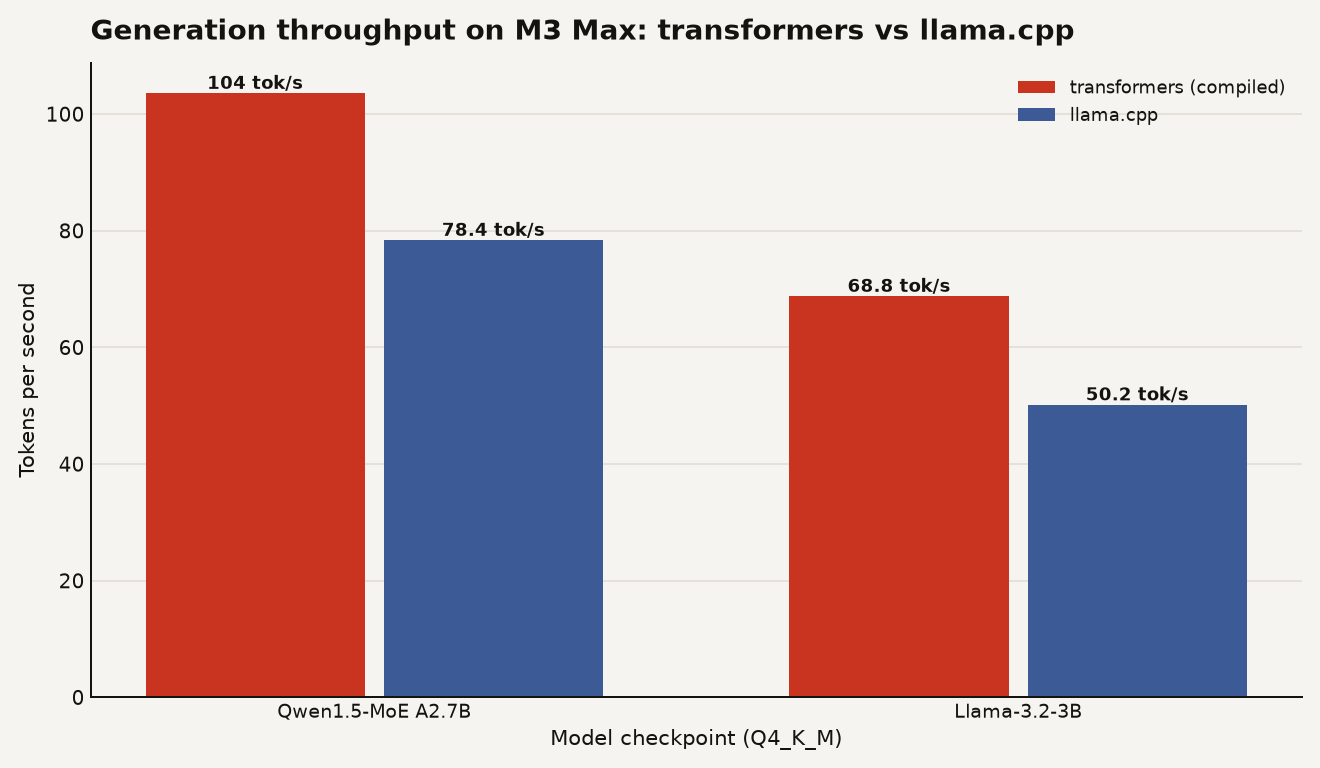
GGUF inference in transformers now matches llama.cpp on Apple Silicon, hitting 103.6 tok/s with ggml Metal kernels while keeping you in PyTorch.
8 stories tagged inference.
GGUF inference in transformers now matches llama.cpp on Apple Silicon, hitting 103.6 tok/s with ggml Metal kernels while keeping you in PyTorch.
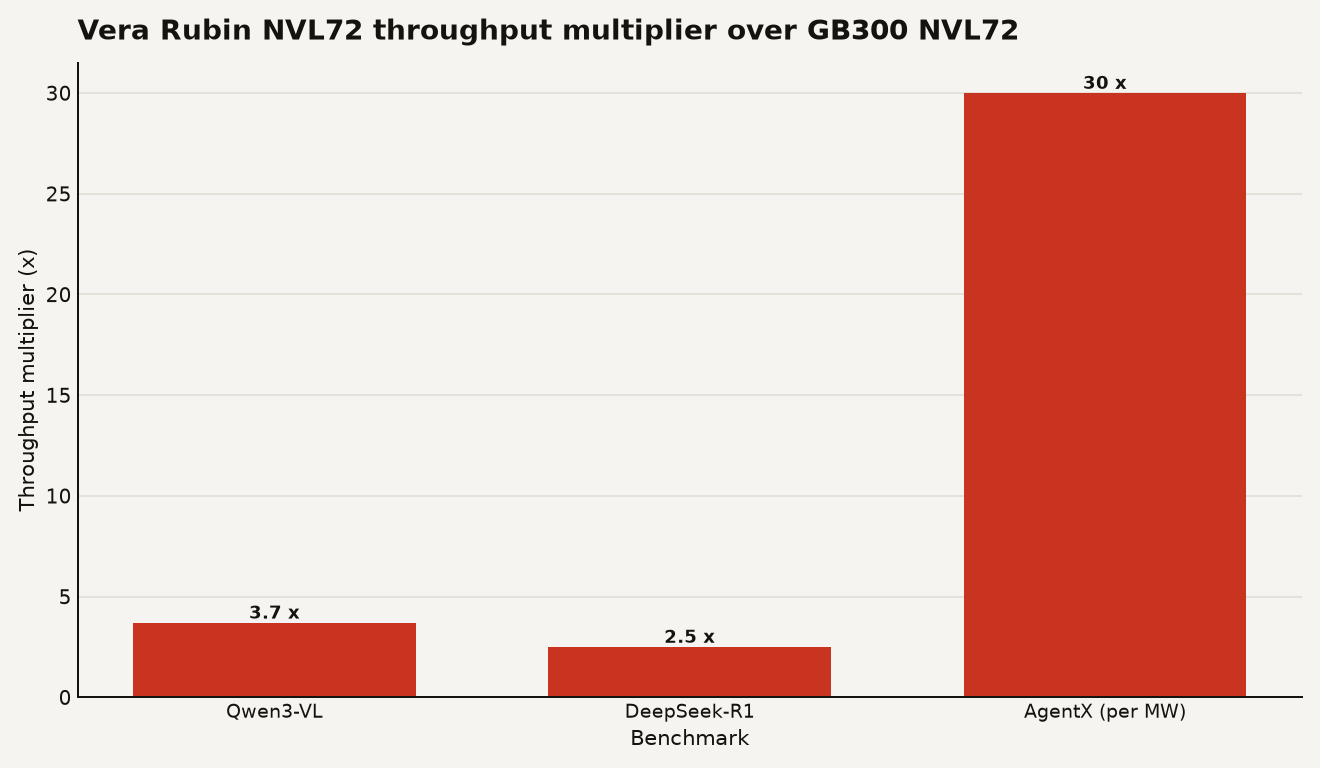
NVIDIA Vera Rubin NVL72 enters MLPerf Inference v6.1 with 3.7x throughput over GB300 NVL72, plus 99% scaling efficiency and 30x gains on agentic workloads.
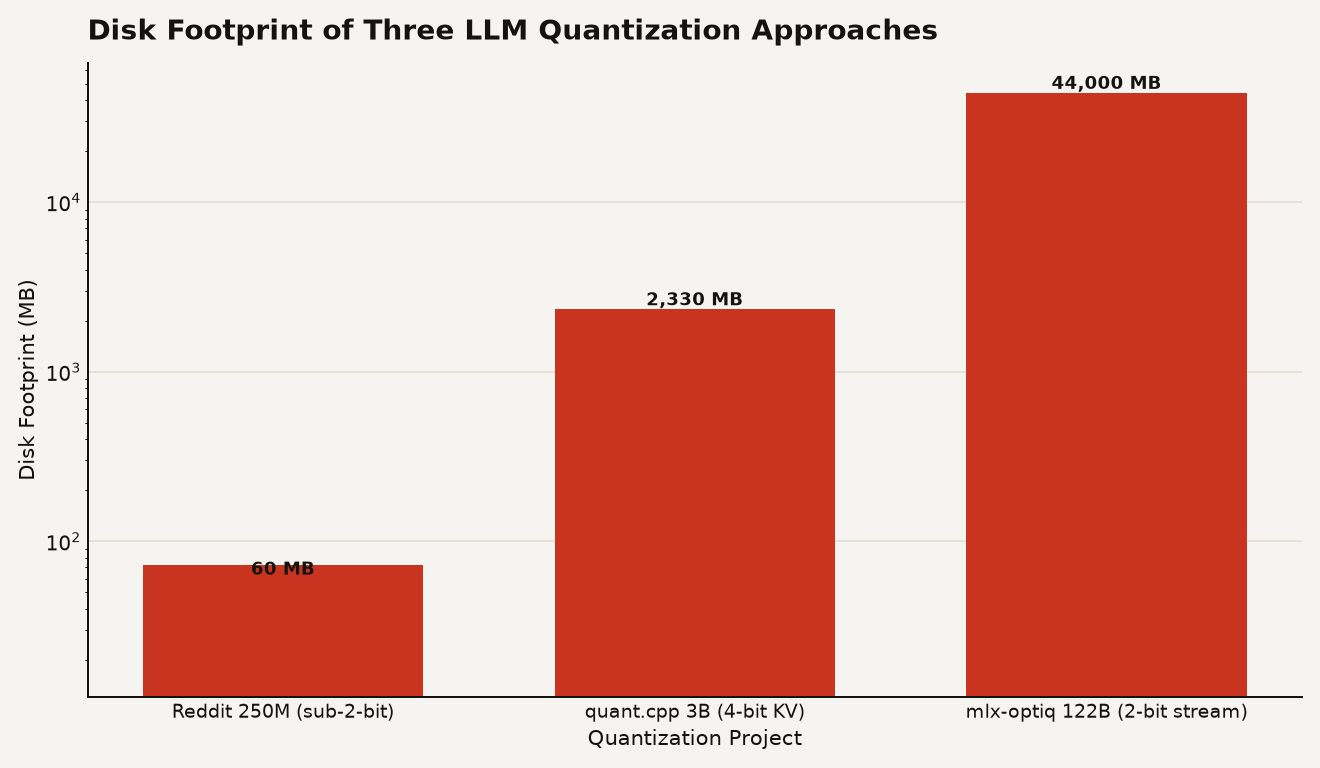
Sub-2-bit LLM quantization puts a 250M model in 60 MB of disk and 80 MB of RAM, running at 400 tok/s on a laptop CPU. The method keeps recent tokens at full precision and compresses the rest, pointing toward a new class of lightweight deployments.
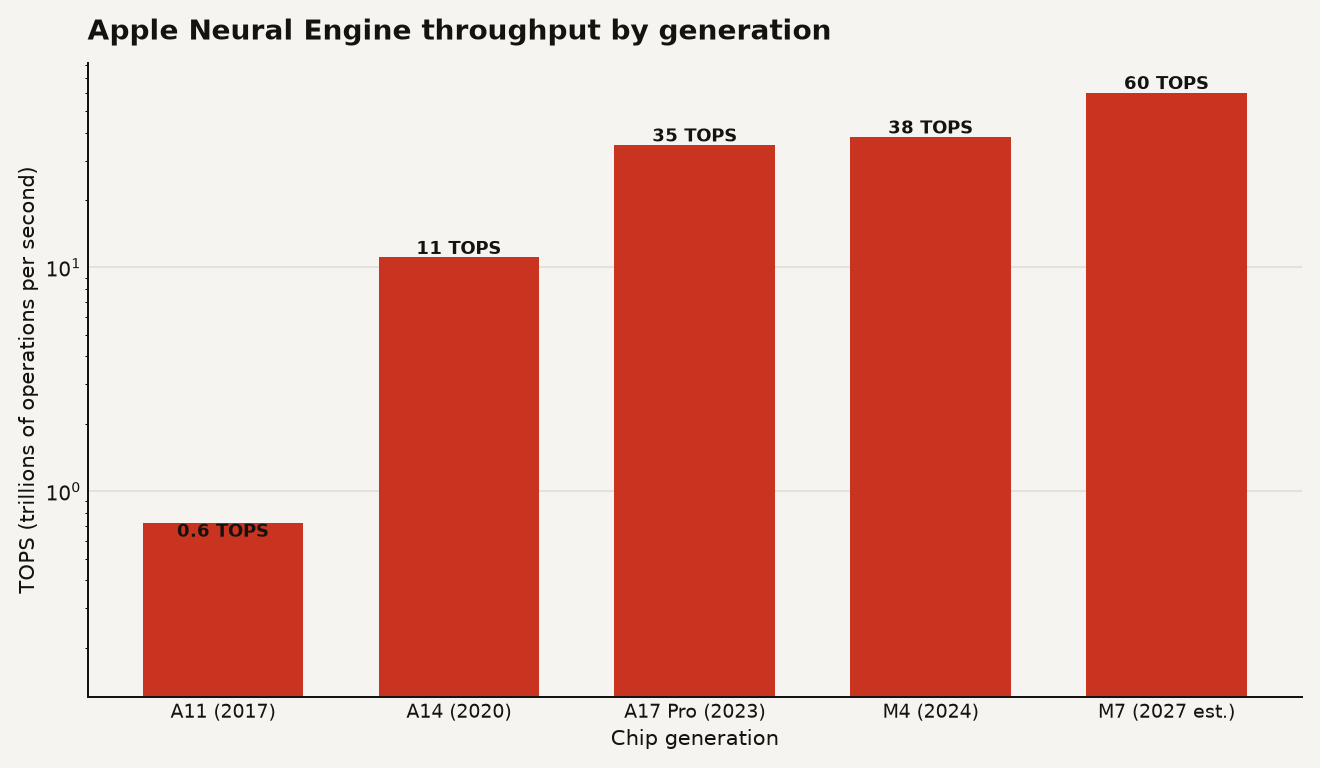
Apple's Neural Engine, born from its failed car project, became the backbone of on-device AI. The M7 Ultra with 1.5TB of RAM could put Apple in the server inference market by 2027.
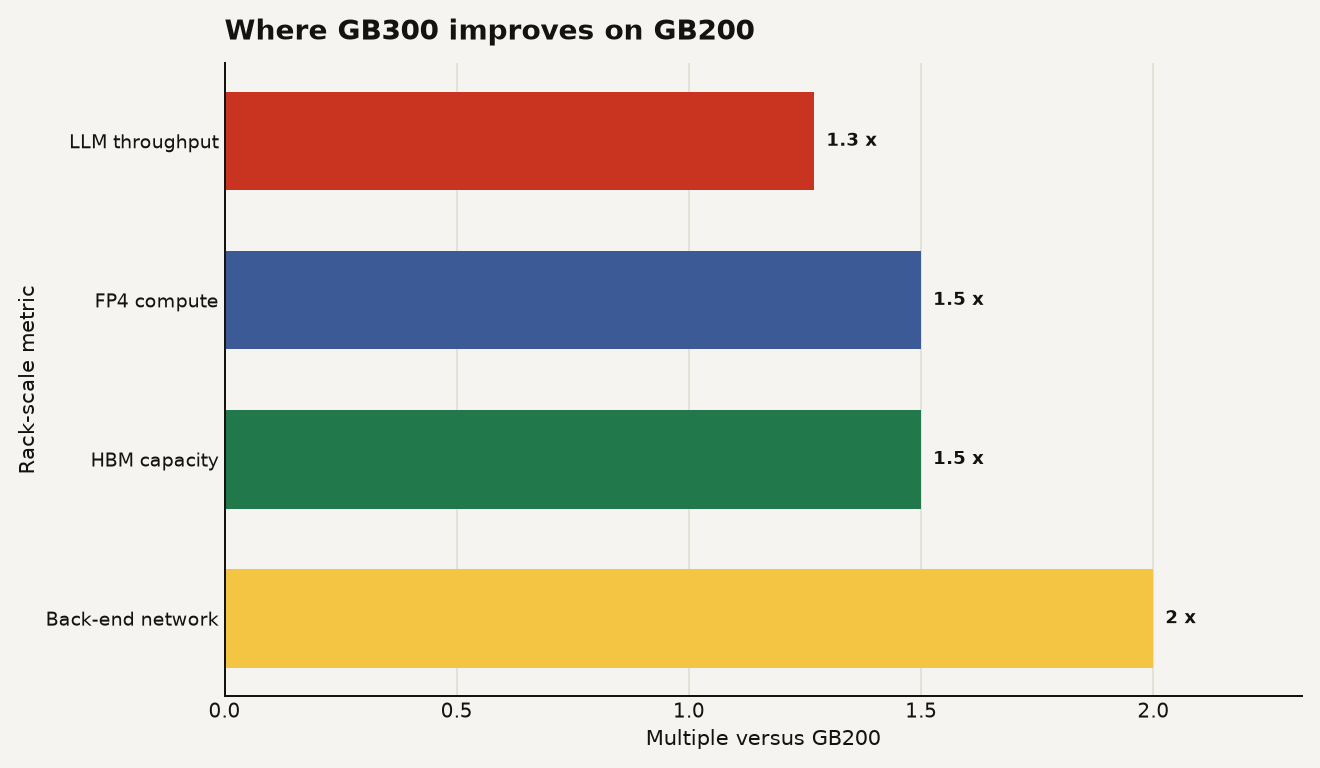
Generally available Claude on GB300 in Microsoft Foundry gives Azure teams more inference headroom, at the price of a tighter cloud bet.
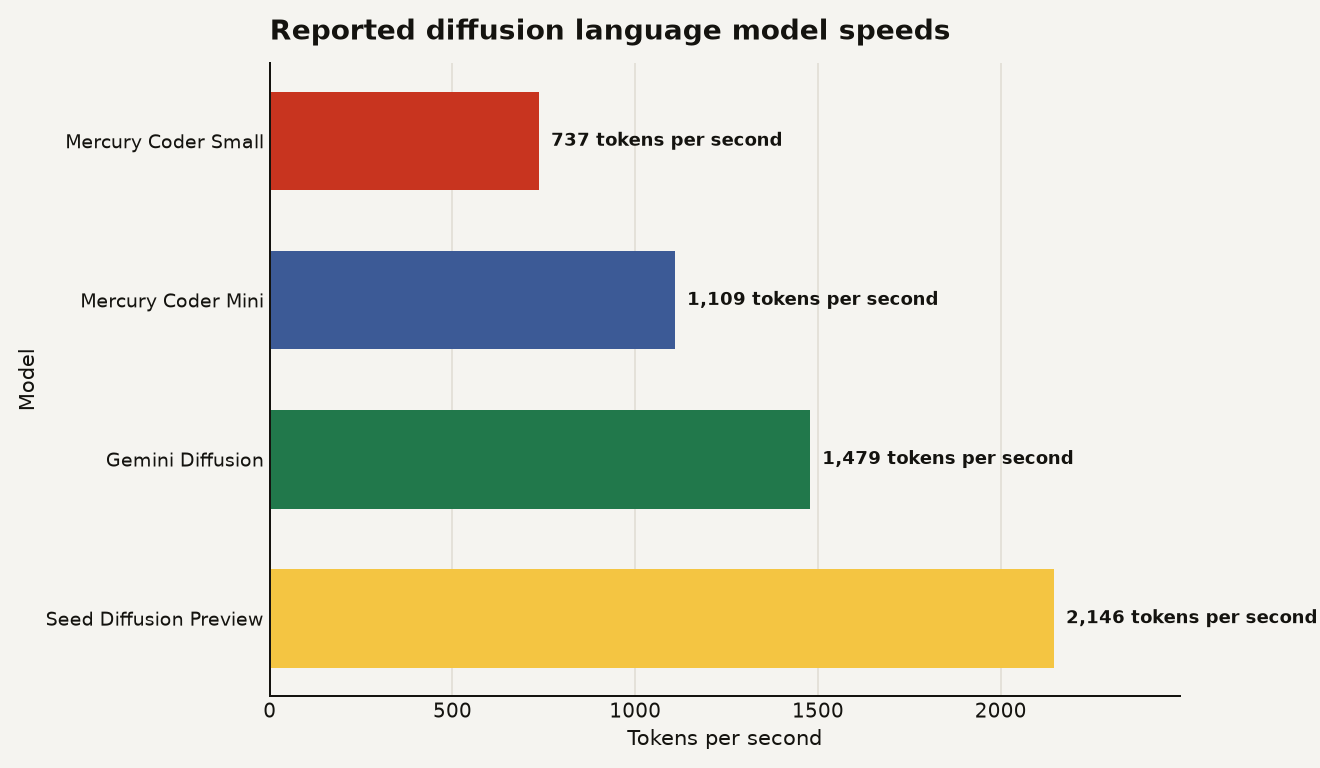
Diffusion language models generate by denoising full sequences, but an 8 model, 8 benchmark study shows deployment depends on inference choices.
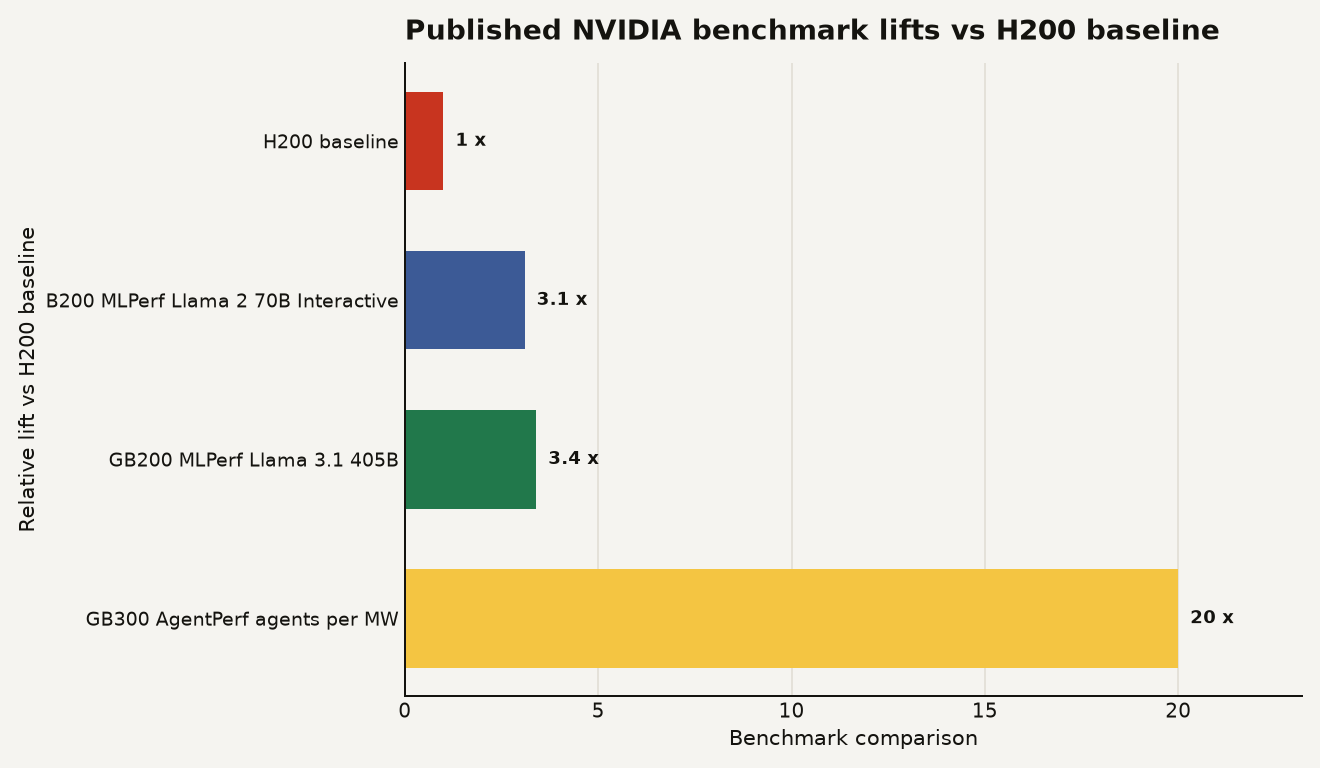
The first AgentPerf results for concurrent AI agents put NVIDIA GB300 NVL72 at up to 20 times Hopper's efficiency per watt.
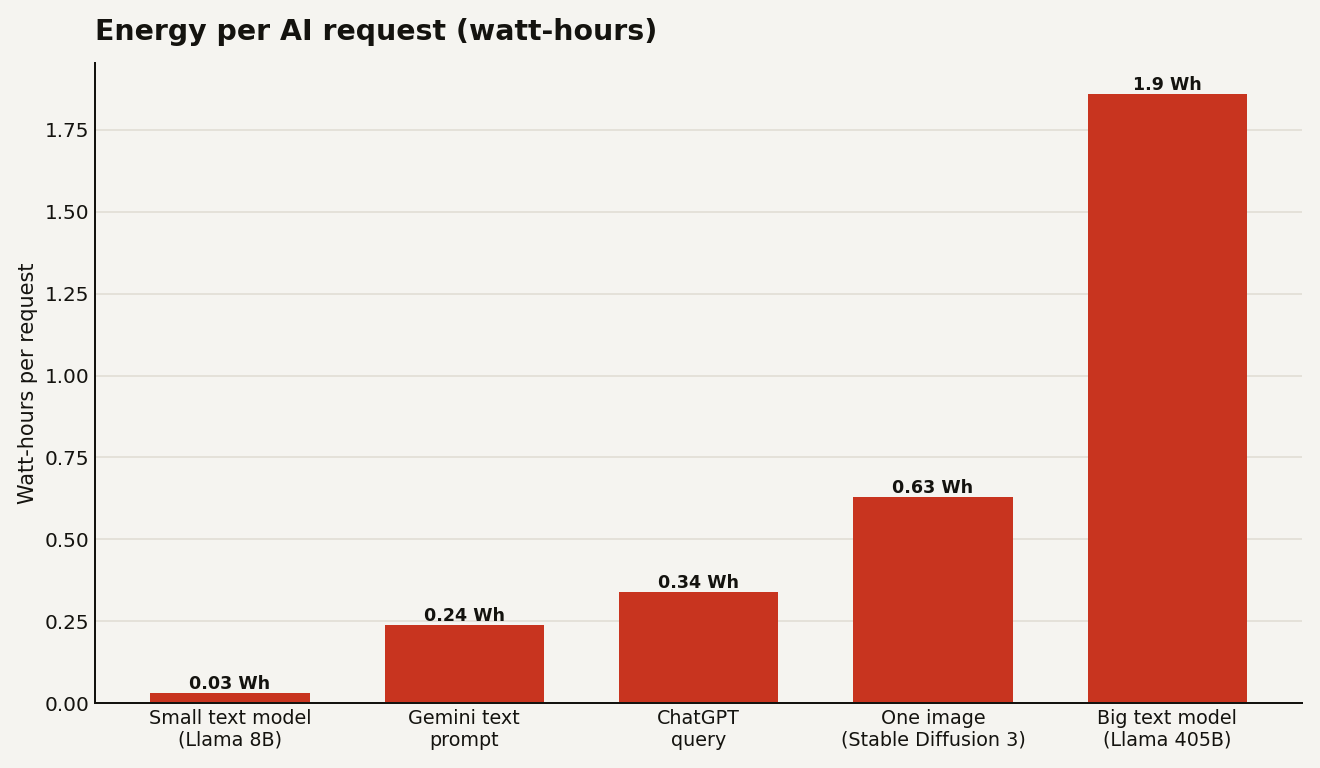
A typical AI text prompt uses roughly 0.24 to 0.34 watt-hours and a fraction of a milliliter of water, not a bottle per email. Training is huge but rare, and inference is what adds up.