Engineering
Transformers GGUF inference nears llama.cpp speed on Mac
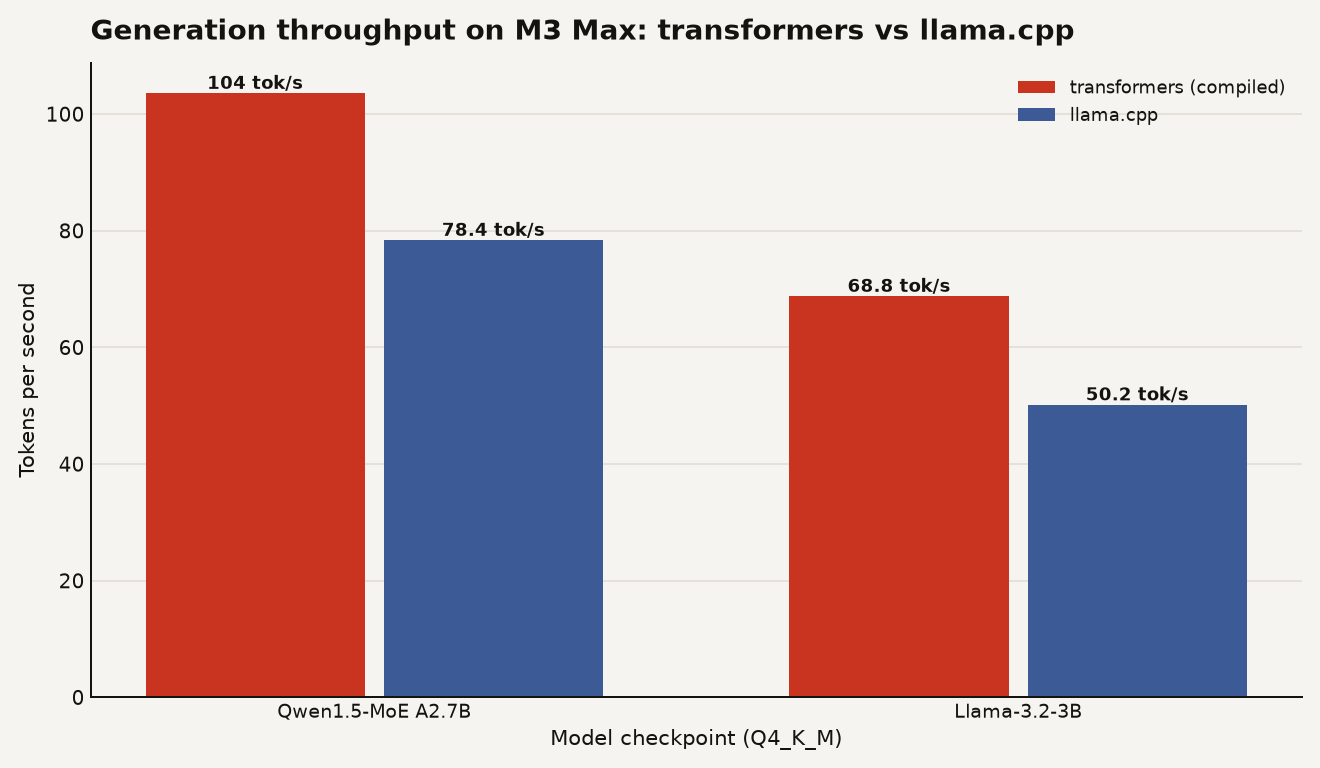
GGUF inference in transformers now matches llama.cpp on Apple Silicon, hitting 103.6 tok/s with ggml Metal kernels while keeping you in PyTorch.
3 stories tagged apple-silicon.
GGUF inference in transformers now matches llama.cpp on Apple Silicon, hitting 103.6 tok/s with ggml Metal kernels while keeping you in PyTorch.
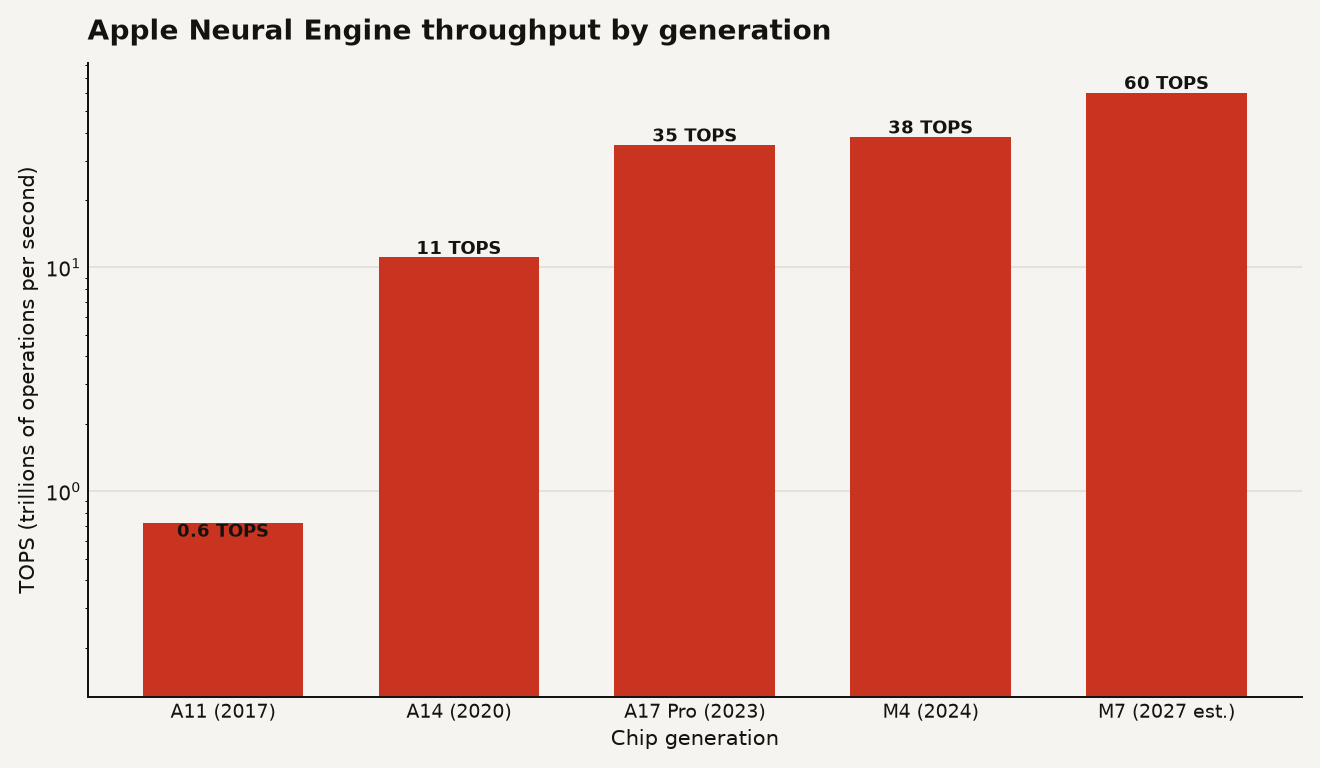
Apple's Neural Engine, born from its failed car project, became the backbone of on-device AI. The M7 Ultra with 1.5TB of RAM could put Apple in the server inference market by 2027.
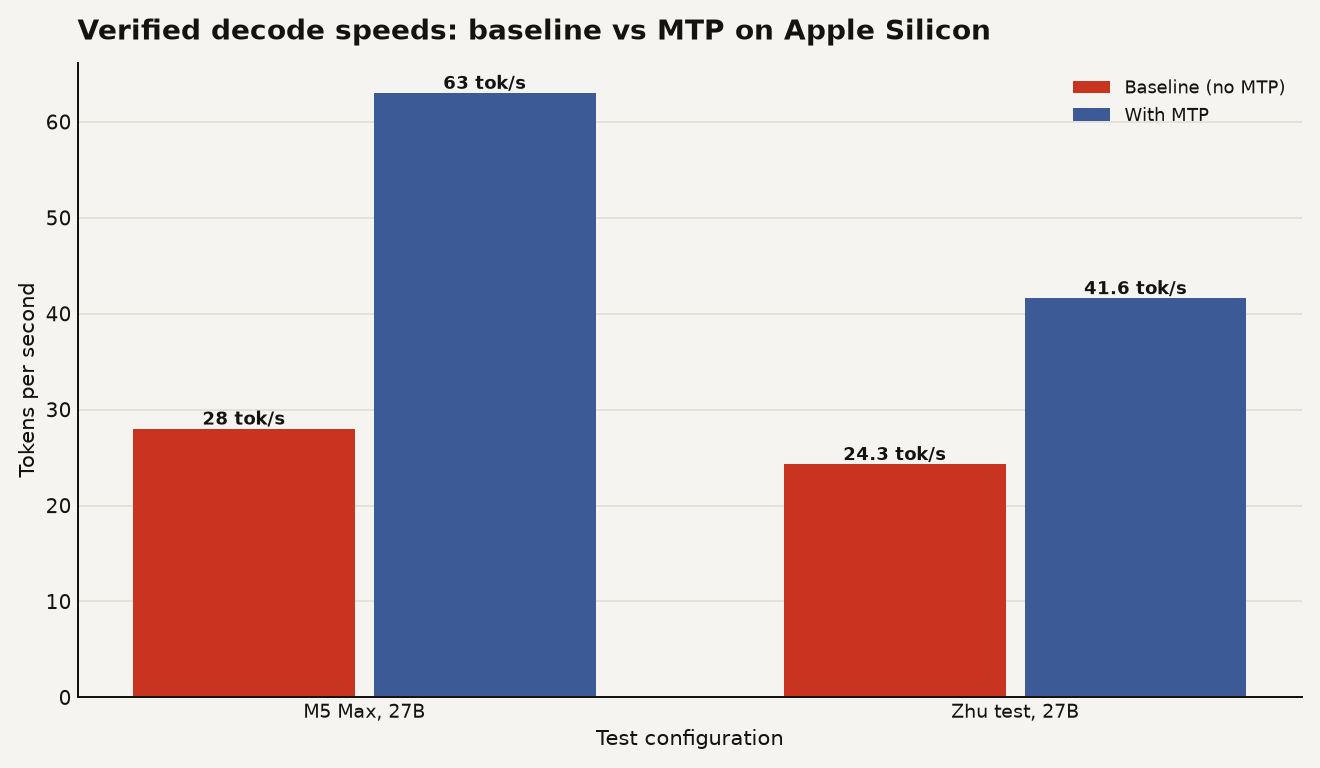
MTPLX v2 uses multi-token prediction to run local AI on Apple Silicon Macs up to 2.24x faster. Here is what beginners need to know.