AI for dummies
Qwen3.8-27B on one RTX 3090 hits 2,000 tok/s prefill
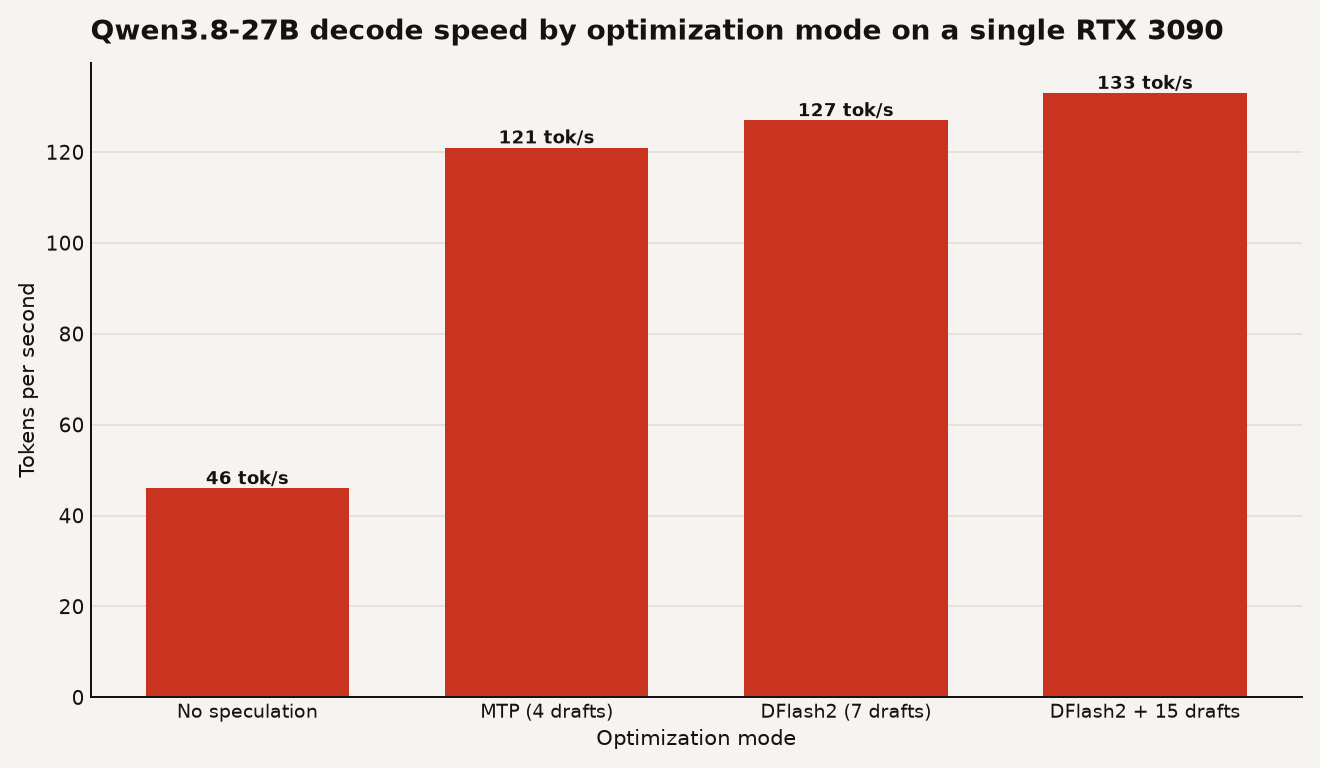
Community builders pushed Qwen3.8-27B to 2,000 tok/s prefill and 132 tok/s decode on a single RTX 3090. Here is what that speed means for local AI.
4 stories tagged local-llm.
Community builders pushed Qwen3.8-27B to 2,000 tok/s prefill and 132 tok/s decode on a single RTX 3090. Here is what that speed means for local AI.
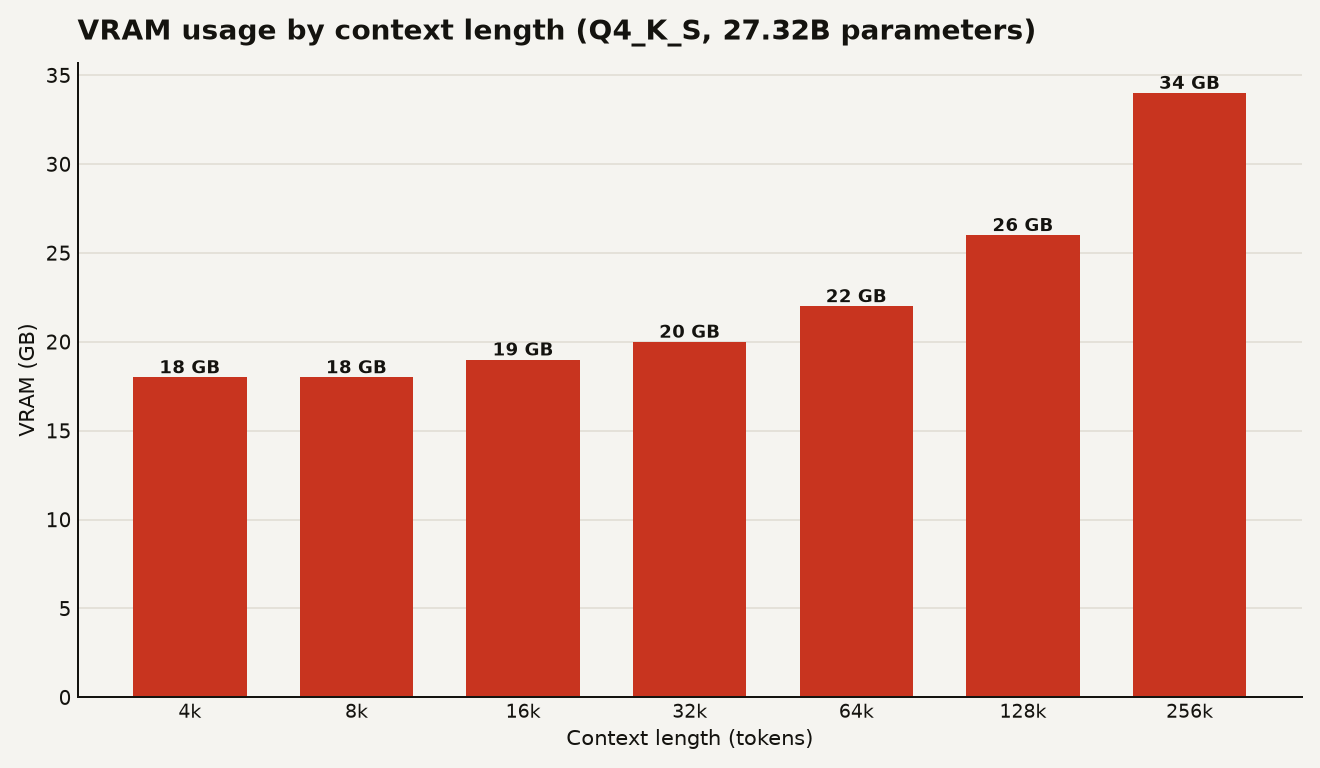
Qwen 3.8 27B is a free, open-weights AI model that runs on your laptop. After one week and 2,000 community posts, here is what testers found.
Scoring 50 on the Intelligence Index, the DeepSeek V4 Flash 0731 open-weights update matches March 2026 frontier models. What it changes for you.
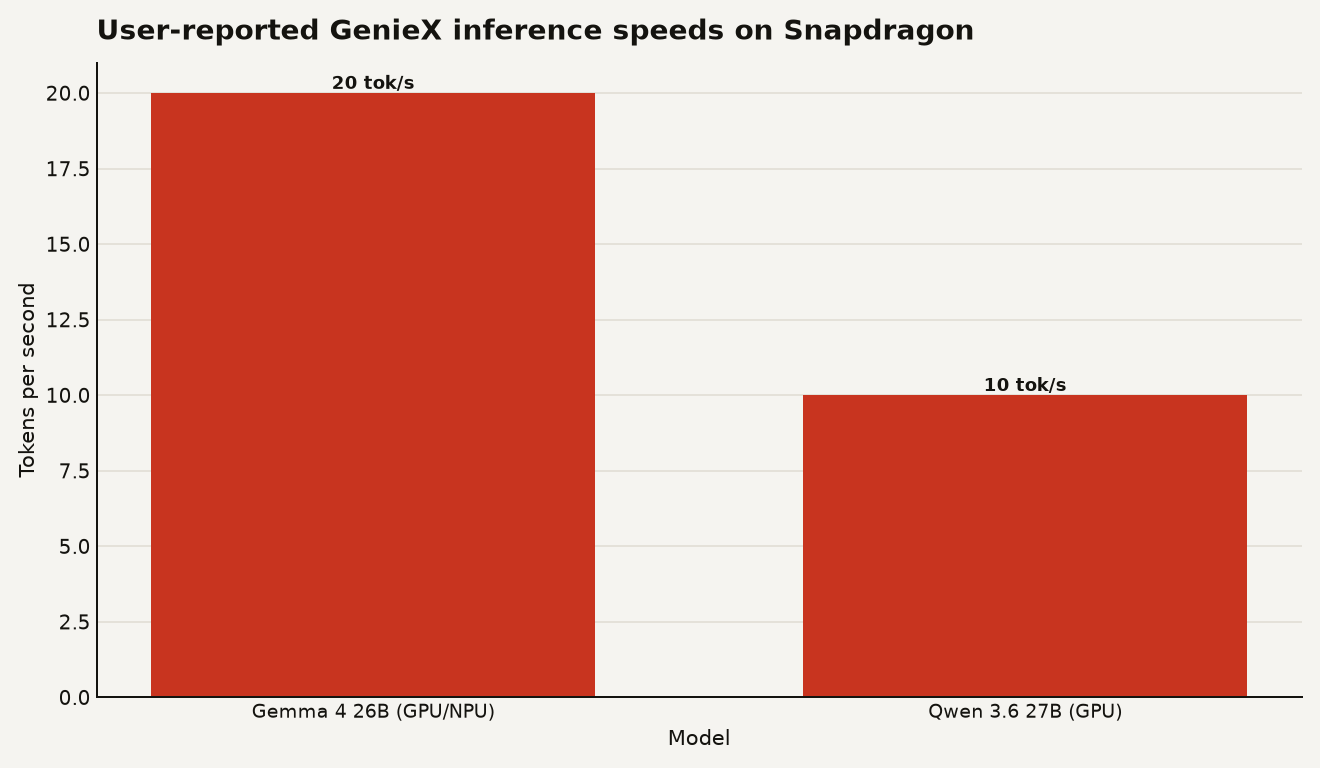
Early users report 20 tokens per second on a 26B model with GenieX, Qualcomm's runtime for running LLMs locally on Snapdragon laptops.