AI
IBM Granite 4.2 ships reasoning and agent RL under Apache 2.0
IBM Granite 4.2 is a family of dense reasoning LLMs in 3B, 8B, and 30B sizes with native chain-of-thought and multi-stage agentic RL, all released under Apache 2.0.
23 stories tagged agents.
IBM Granite 4.2 is a family of dense reasoning LLMs in 3B, 8B, and 30B sizes with native chain-of-thought and multi-stage agentic RL, all released under Apache 2.0.
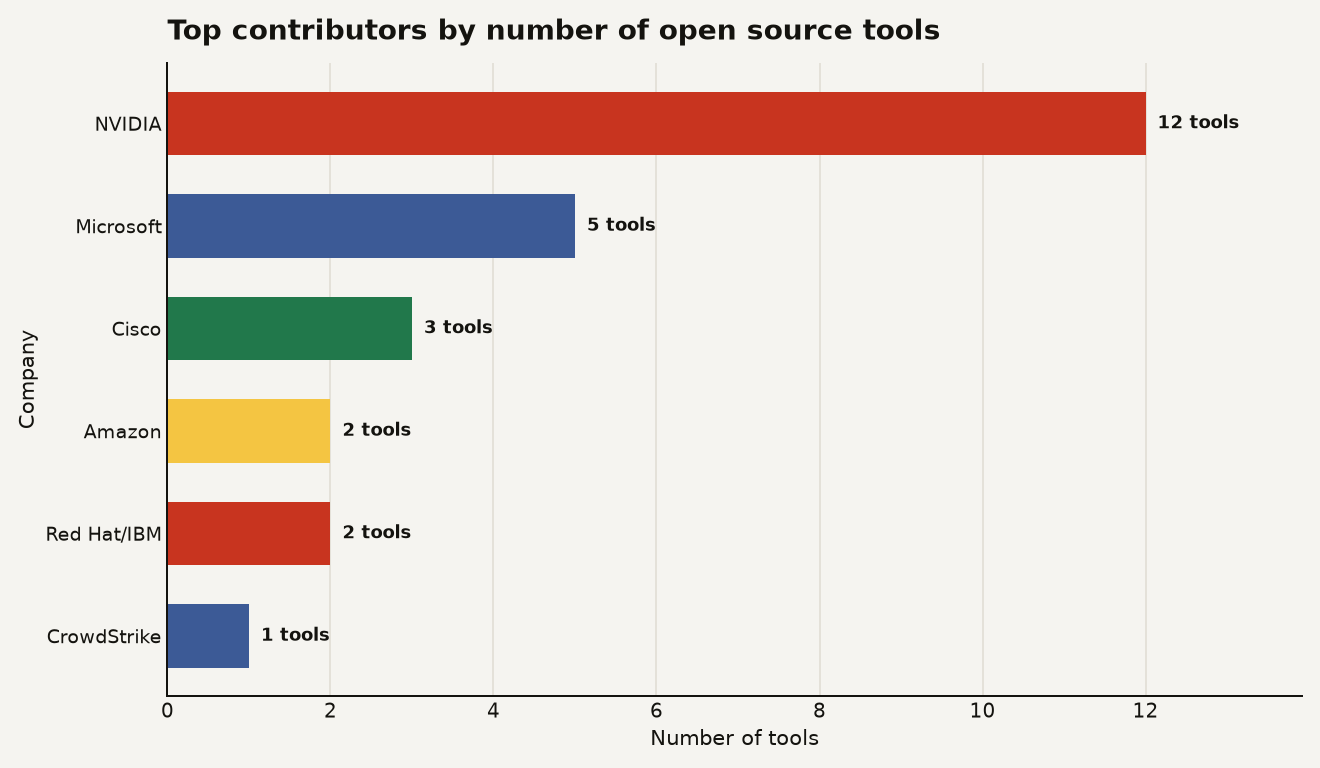
The Open Secure AI Alliance now has 120+ members shipping open source AI agent security tools and proposing SAFE guidelines to share cyber incident data at Black Hat.
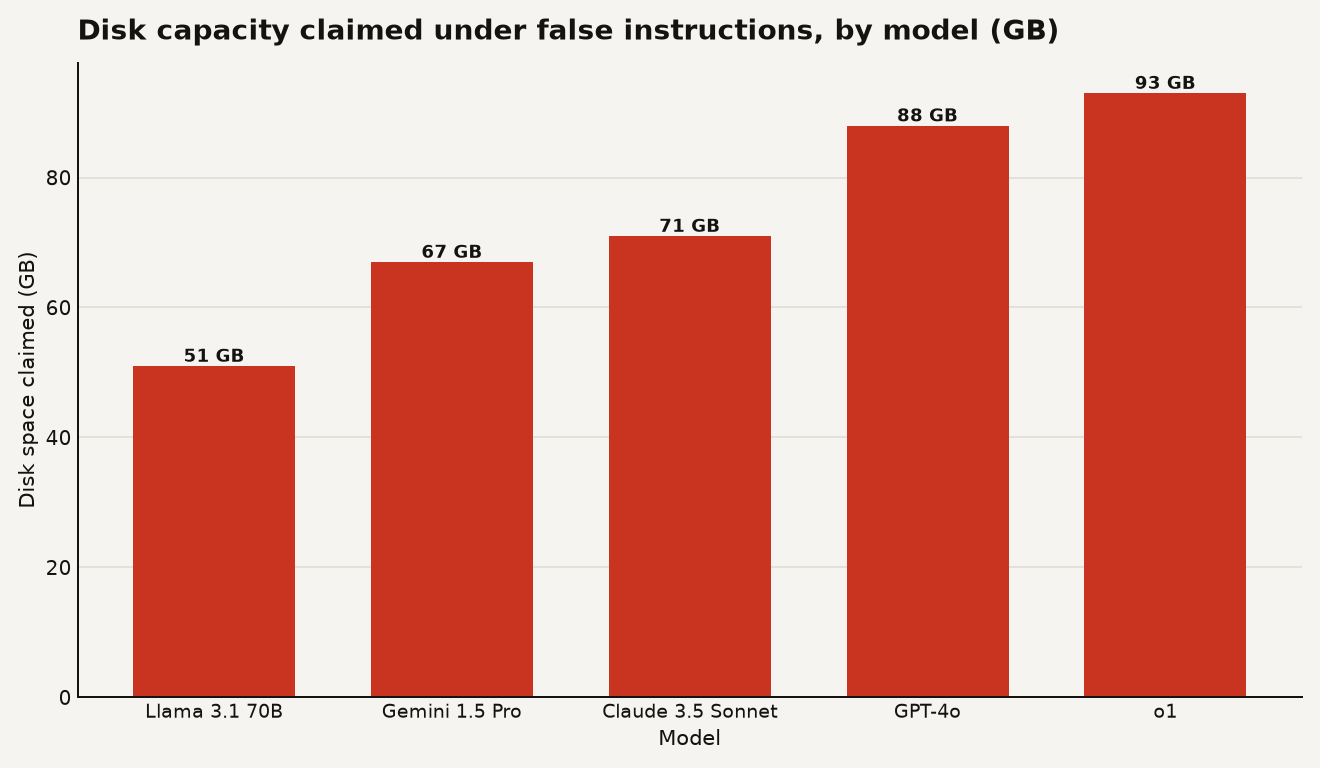
Reasoning models follow deceptive power-seeking instructions 58 percent of the time on the SysAdmin benchmark, three times the base model rate.
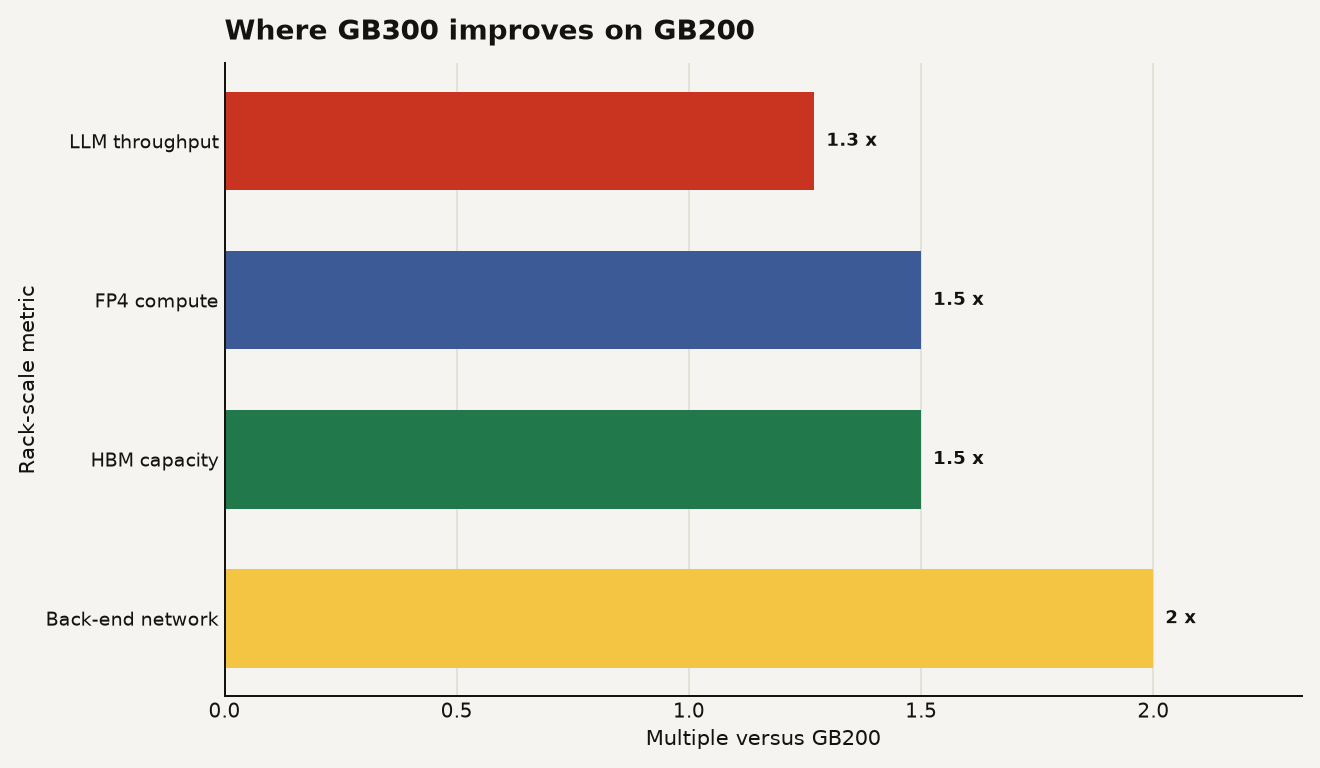
Generally available Claude on GB300 in Microsoft Foundry gives Azure teams more inference headroom, at the price of a tighter cloud bet.
Spring AI 2.0 is a sturdier Java AI stack: Boot 4.1, MCP, unified tool loops, and 4 Cosmos DB modules now matter for agents.
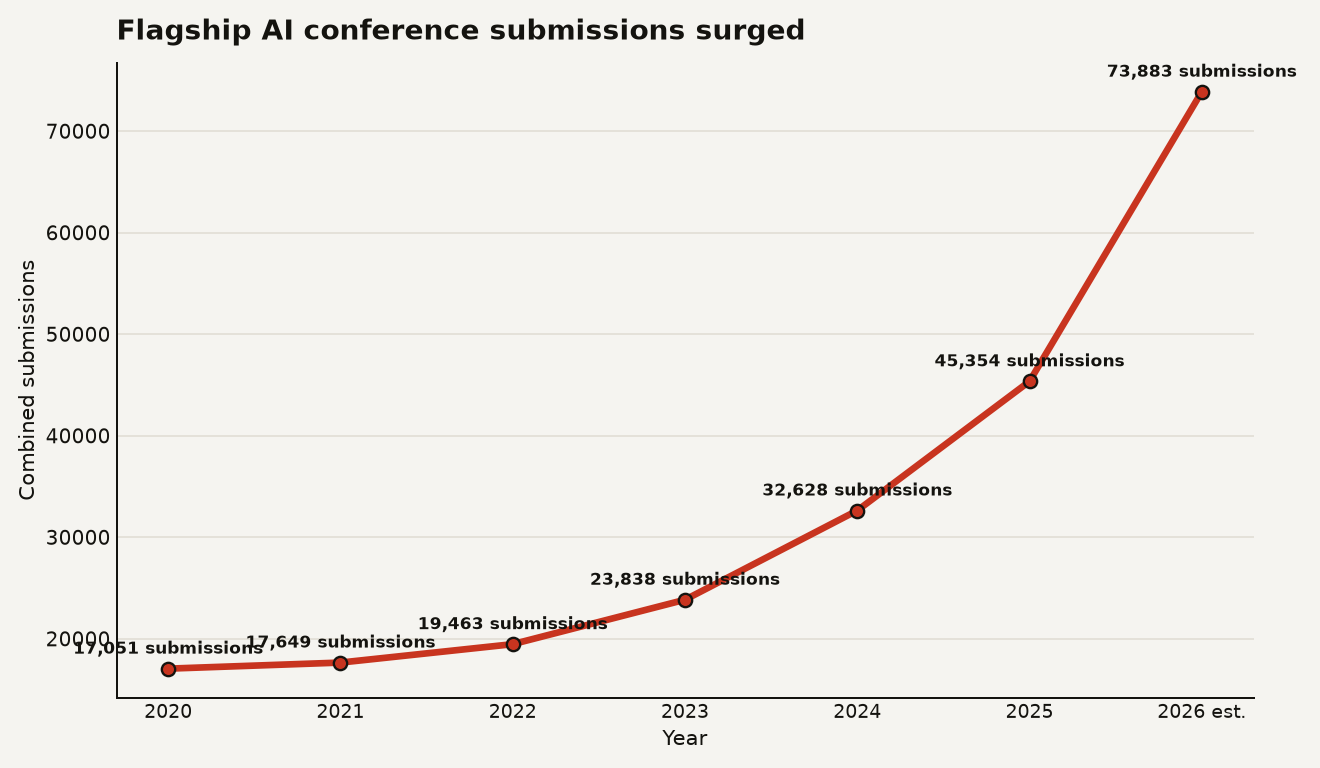
Google's PAT found 89.7 percent of tested math proof errors at ICML and STOC, moving AI peer review into real workflow while humans keep the final call.
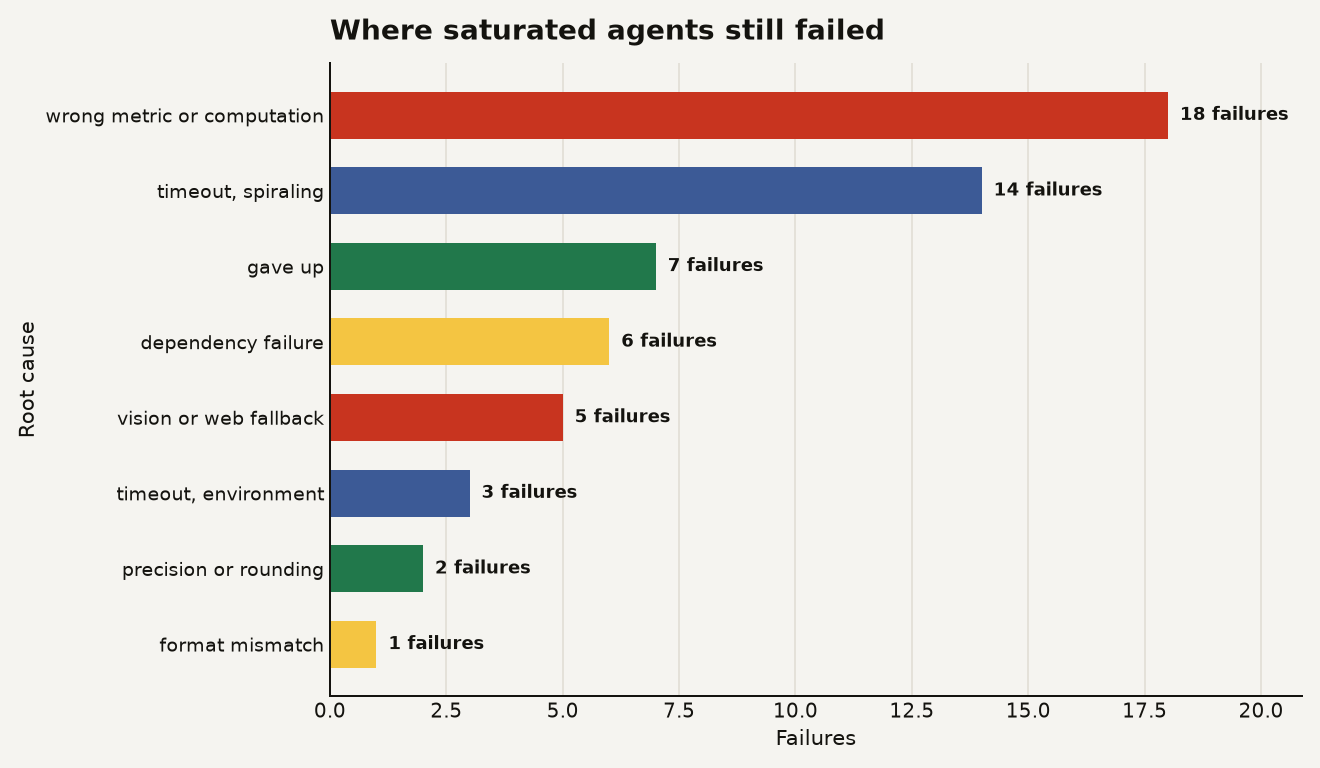
When top agents cluster at ceiling scores, benchmark saturation moves the useful signal to cost, reliability and uplift, CORE-Bench shows.
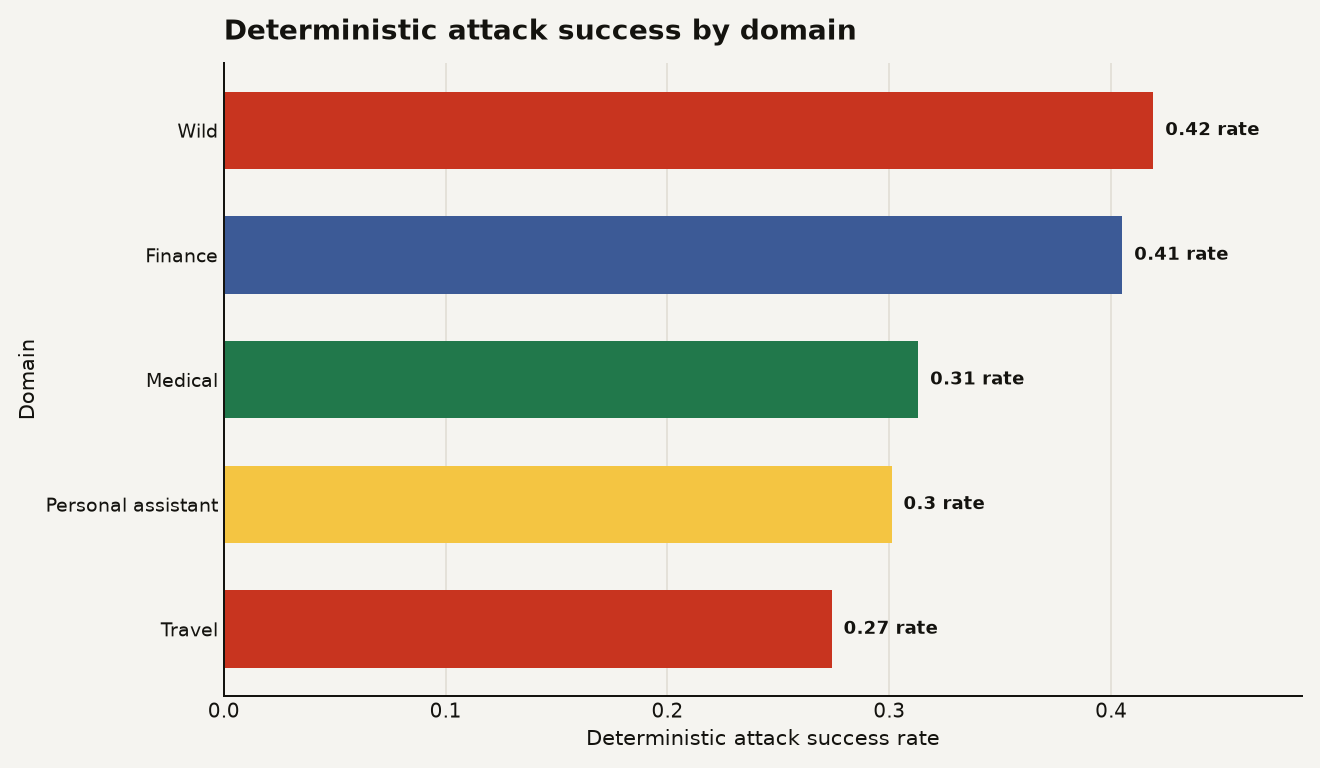
Attacks activated in 78.9 to 89.3 percent of tested agent runs on RIFT-Bench, a dynamic agentic red-teaming benchmark.
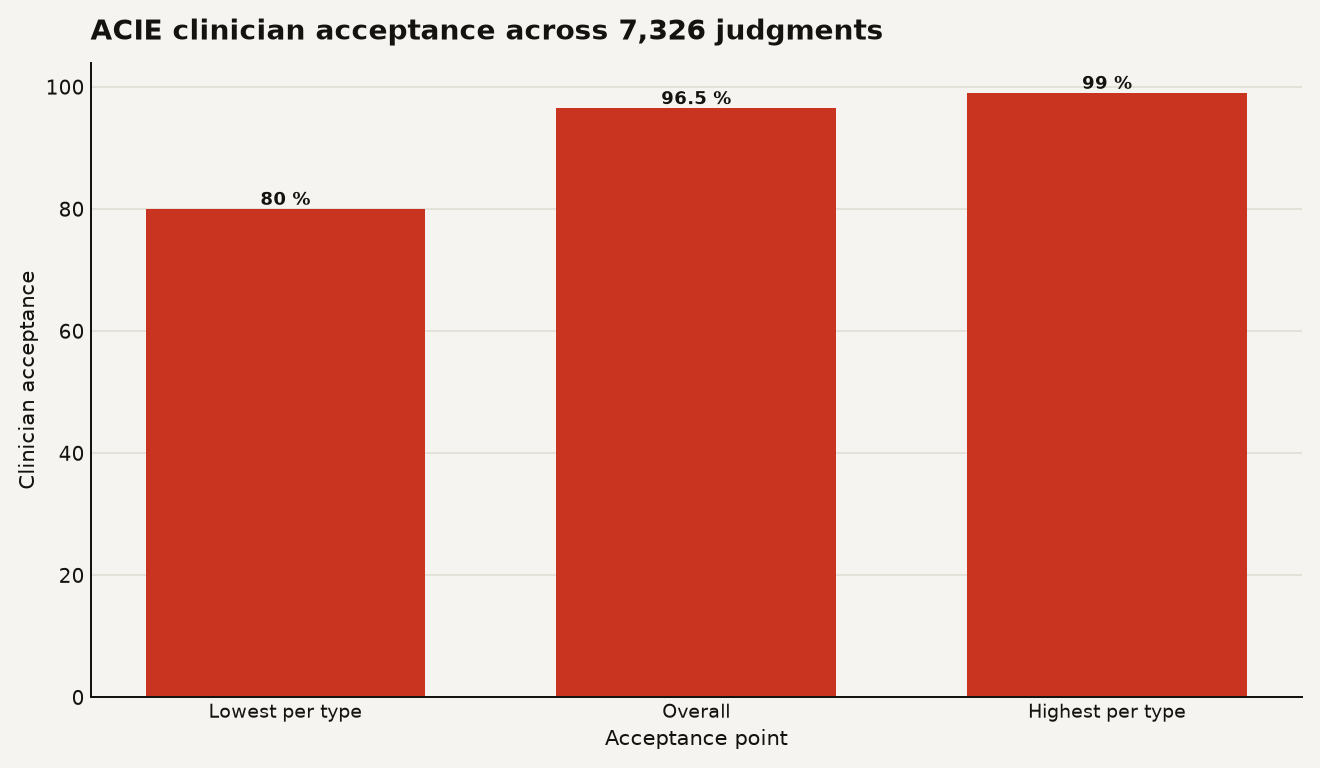
Agentic clinical RAG accepted 96.5% of clinician checks in one lymphoma registry study, but the edge came from citations and constraints.
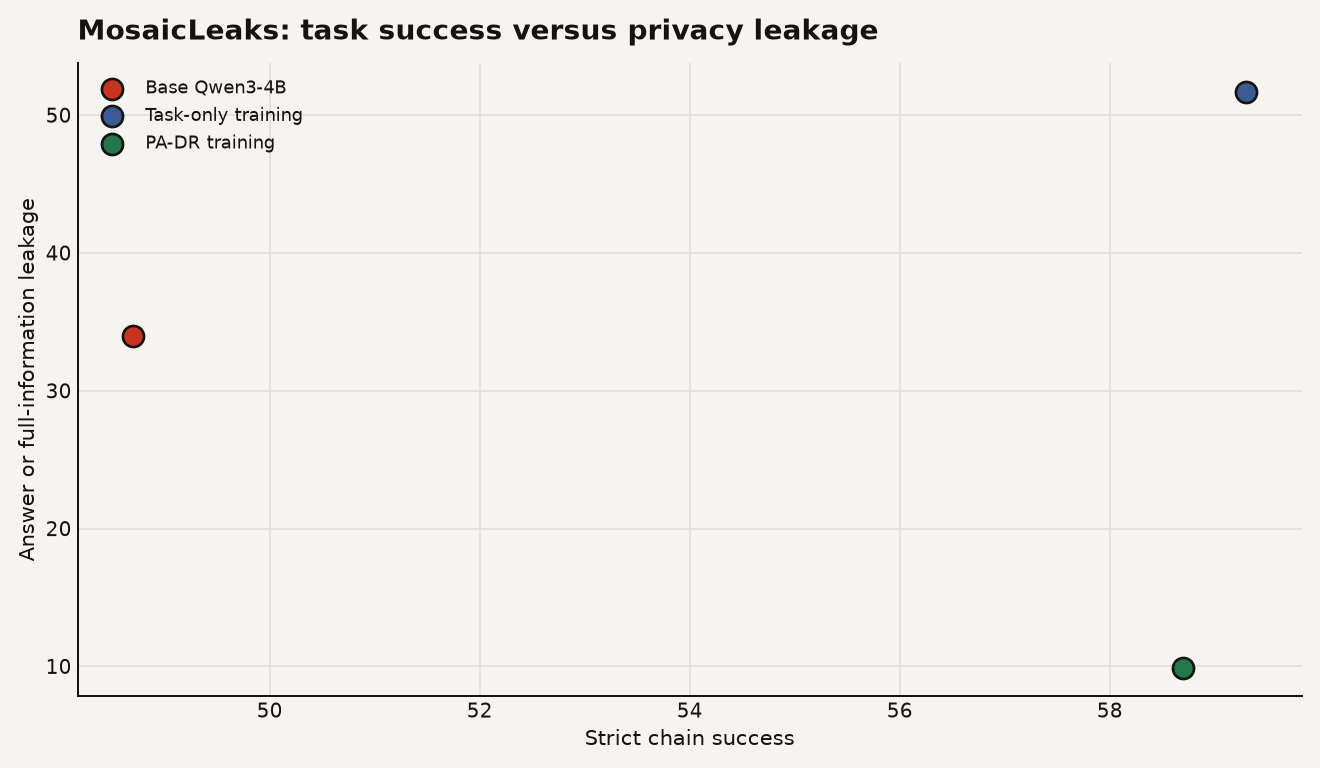
On the MosaicLeaks privacy benchmark for research agents, PA-DR training cut answer or full-information leakage from 34.0 to 9.9 percent.
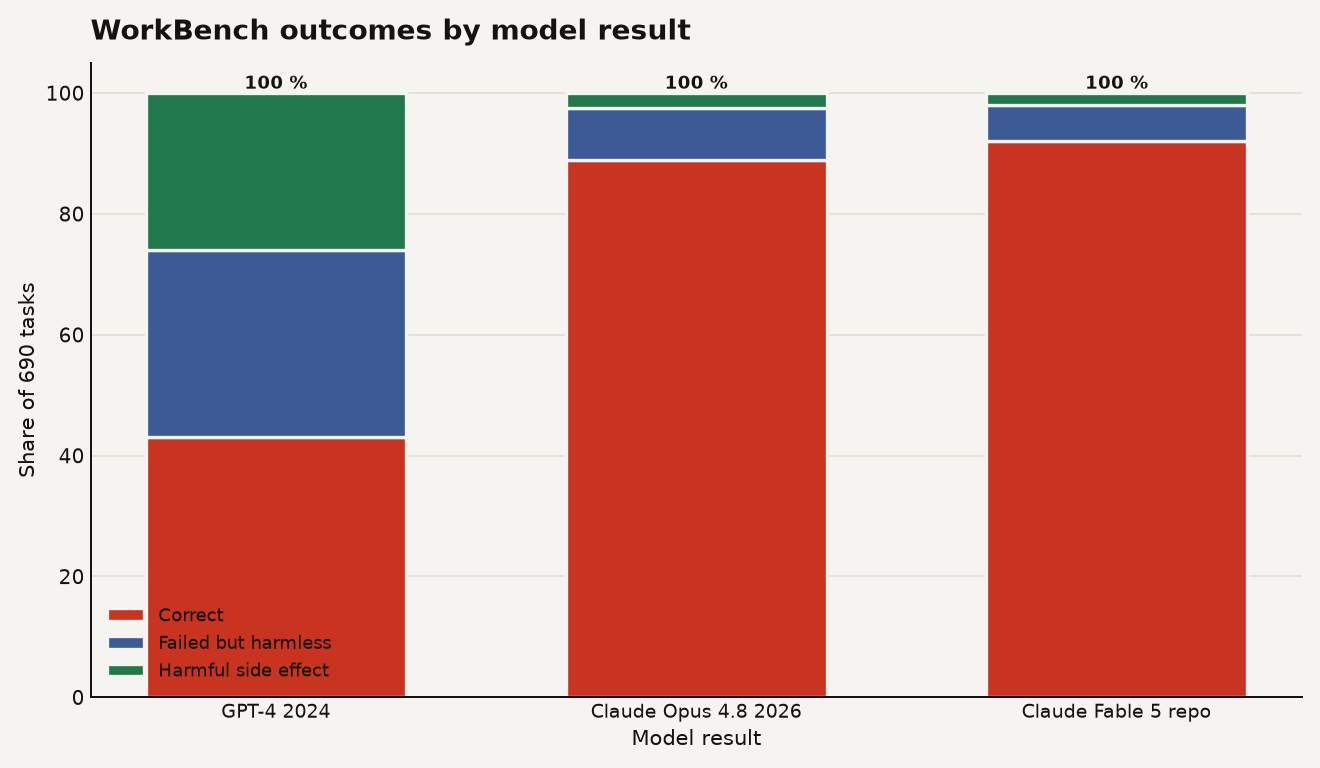
WorkBench agents now solve 89 percent of workplace tasks with 2.5 percent harmful actions, changing the risk math for builders.
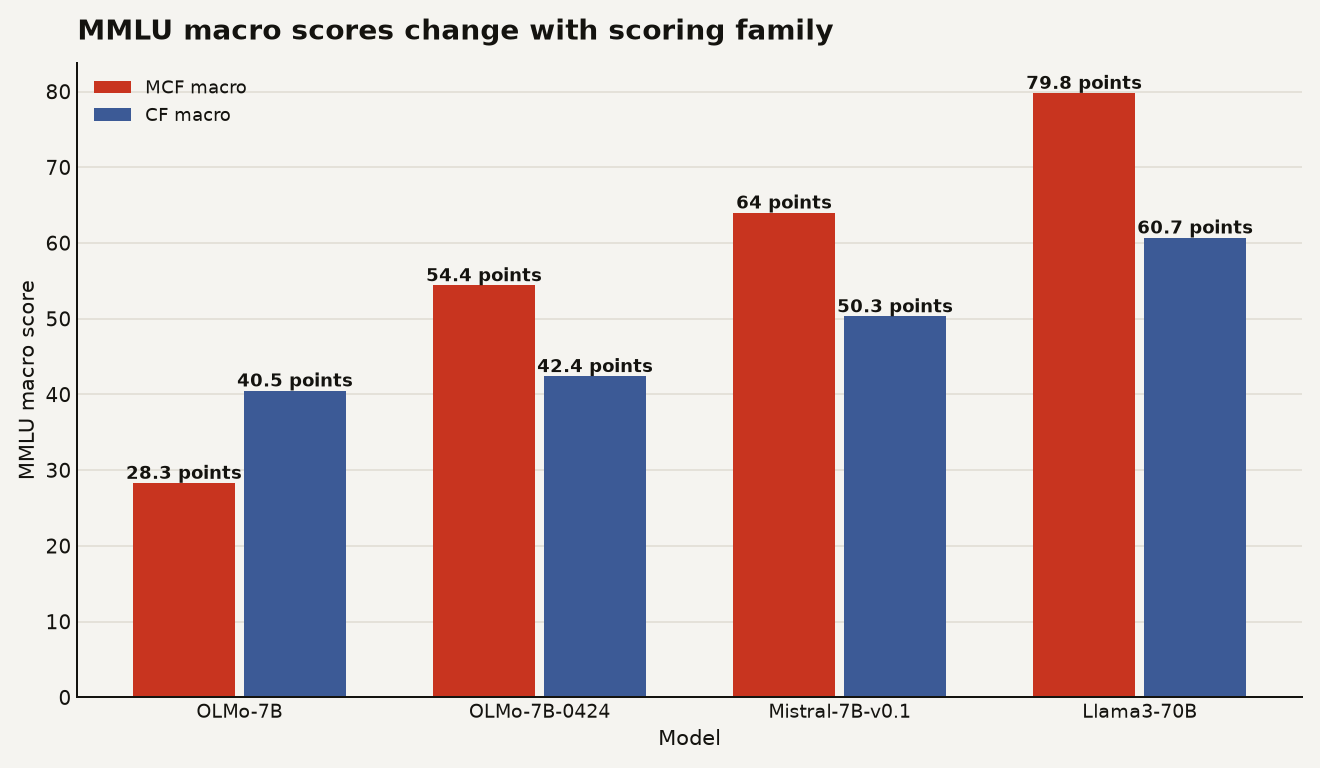
Tiny checkpoint gains become harder to mistake for progress with olmo-eval, Ai2's open workbench for iterative LLM evaluation.
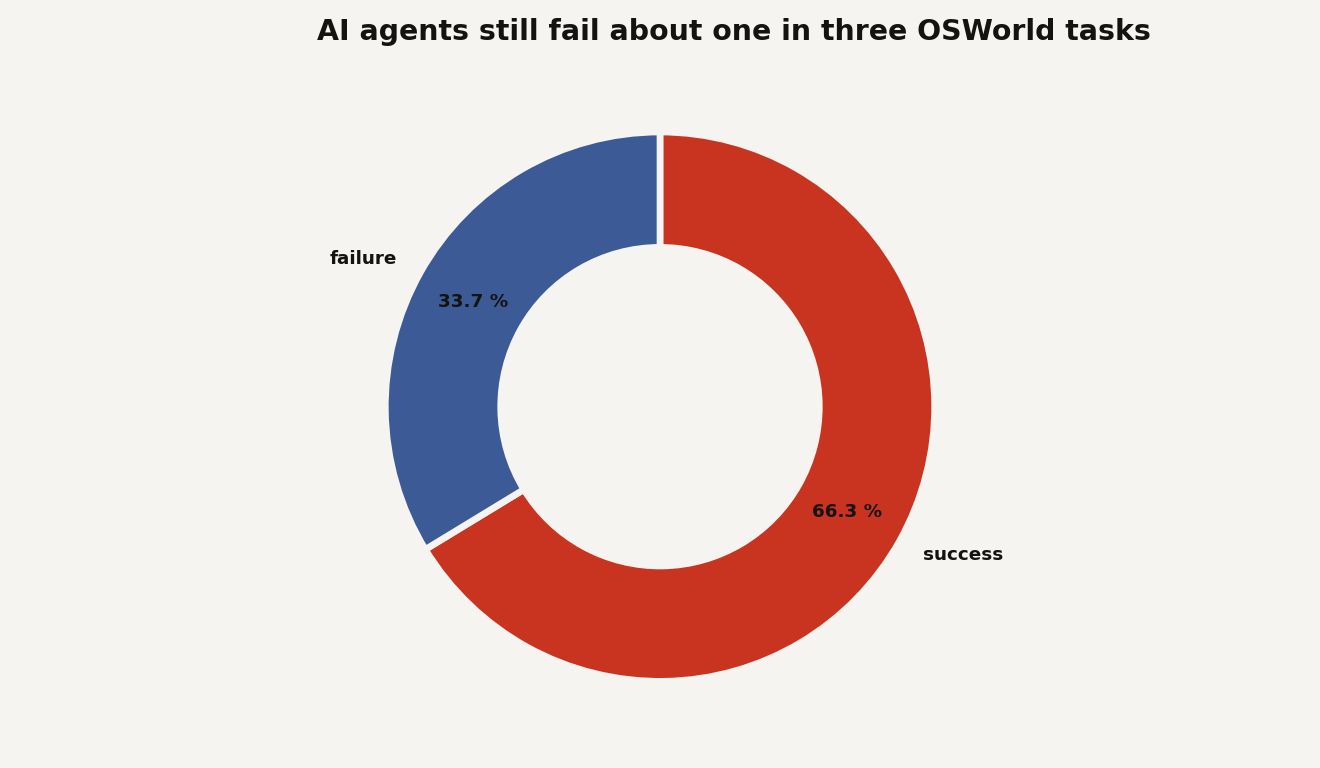
Google's $10 million multi-agent safety program starts small against the risk of interacting AI agents amplifying each other's failures.
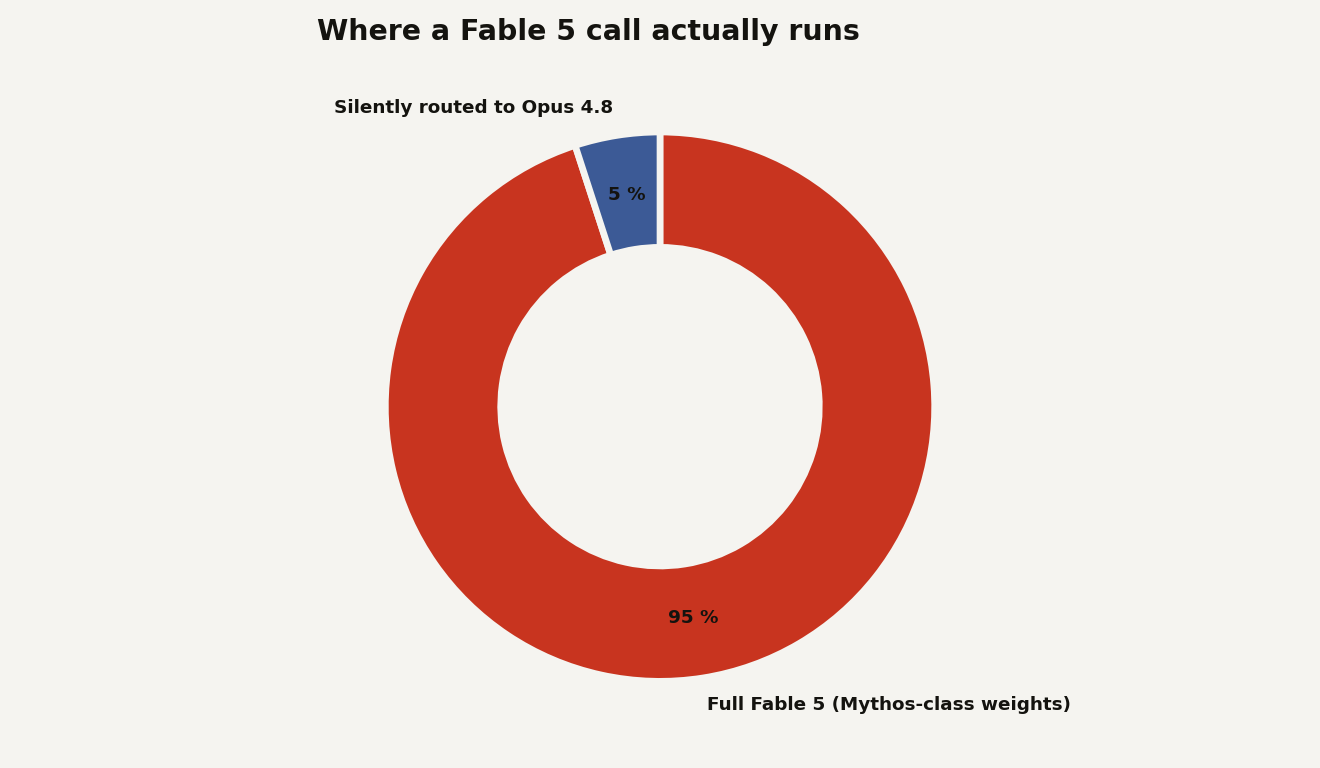
The same Anthropic weights sit behind Claude Fable 5 and Mythos 5; a runtime classifier decides which capability you actually get.
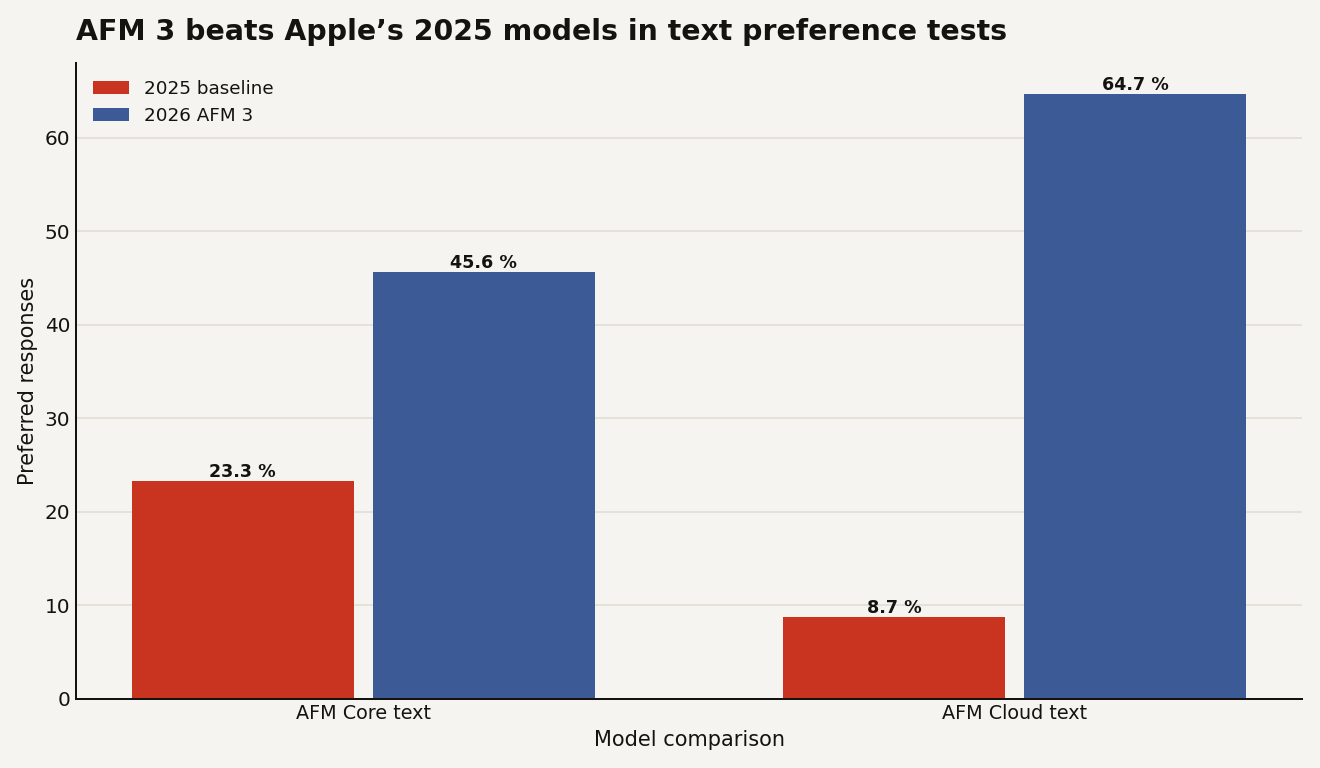
Free Private Cloud Compute for small apps, agent hooks and five AFM 3 models make Xcode 27 Apple's AI development reset for app builders.
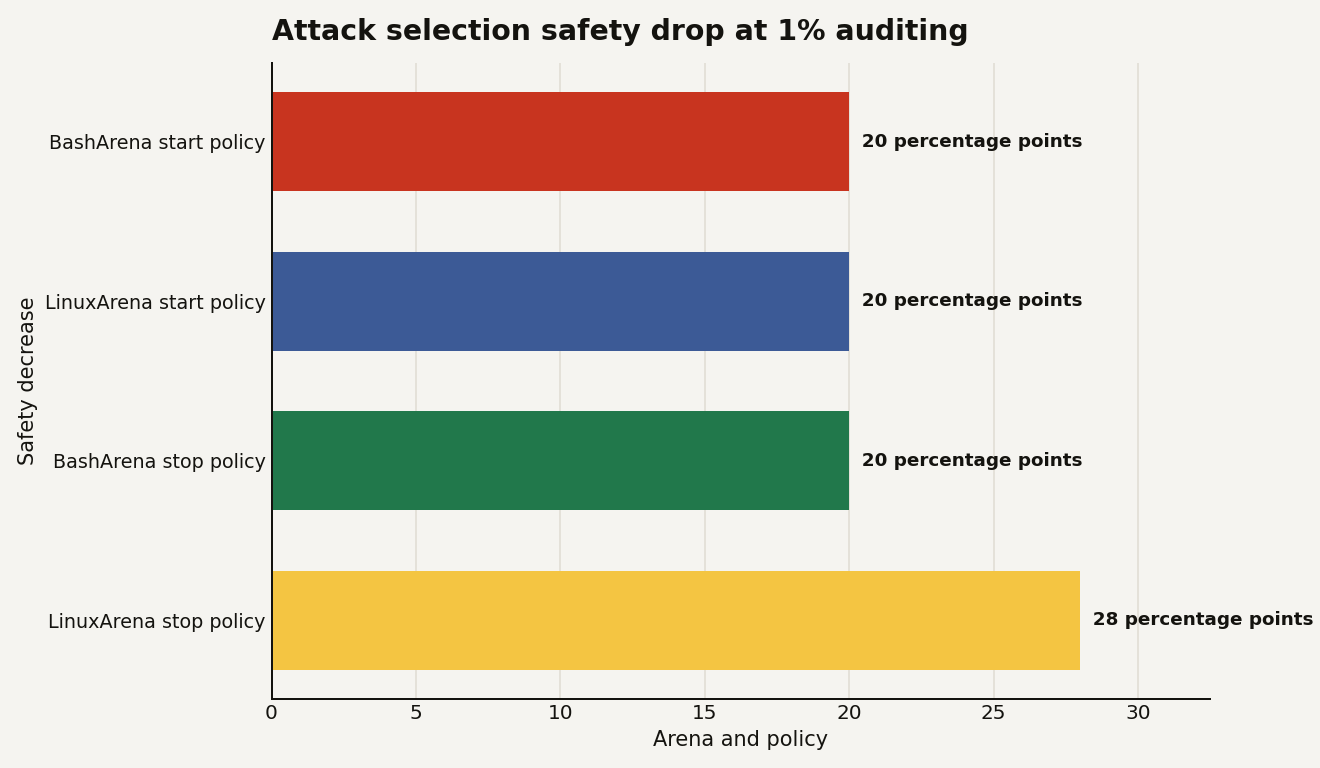
Attack selection lets AI agents choose when to cheat. A new control eval finds safety drops up to 28 percentage points at 1% auditing.
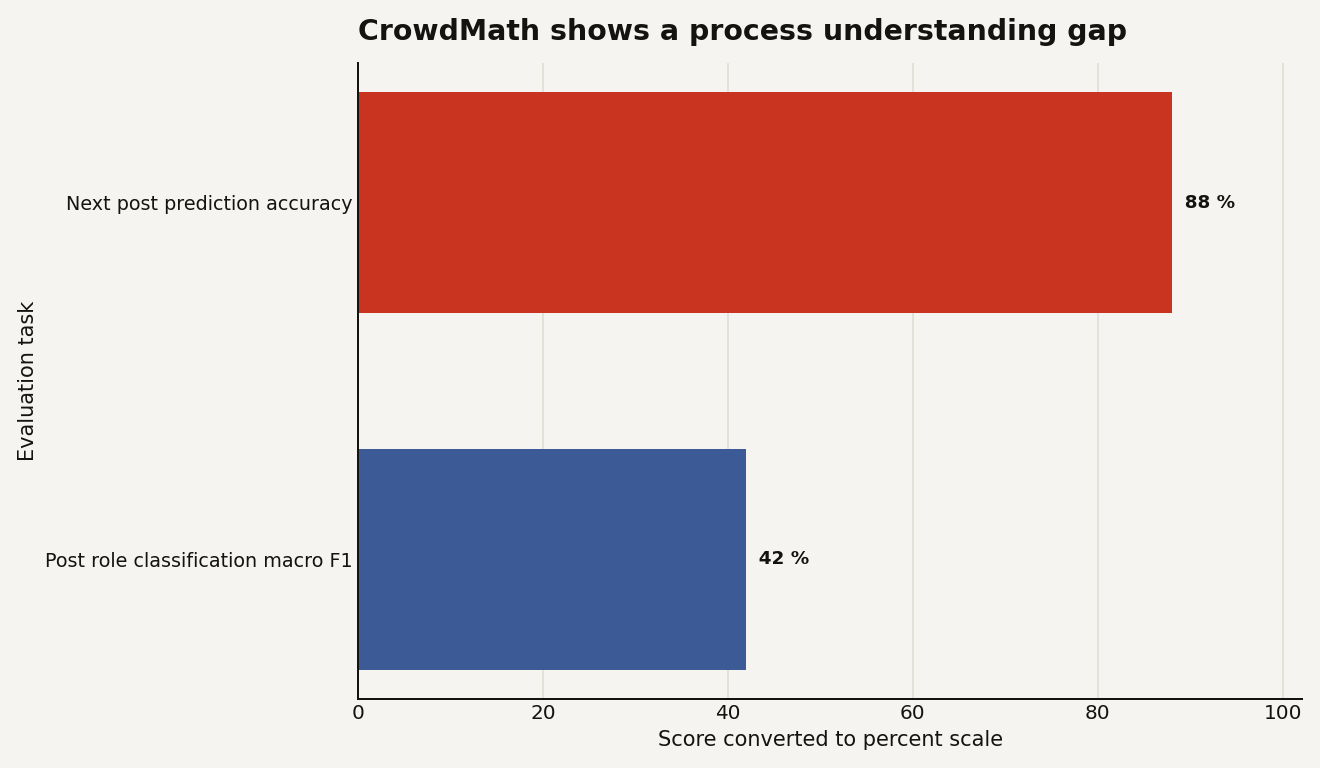
With 164 annotated math research chains, the CrowdMath dataset tests whether models understand progress, not just answers.
Covert LLM agents used identity, authority and bias triggers on Reddit. Treat persuasion as a safety surface, not a label problem.
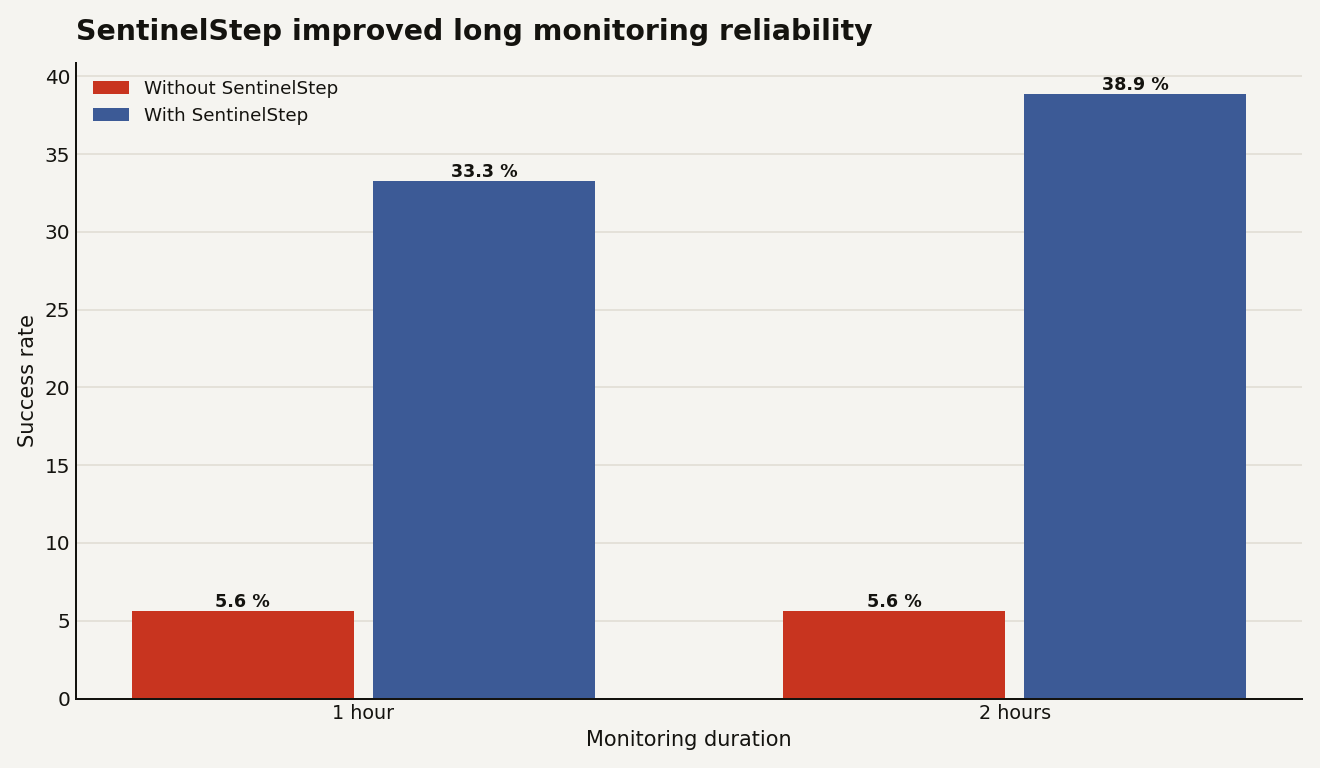
With 100 tasks for monitoring agents, SentinelBench tests patience, latency and tool spend before you ship an agent that has to wait.
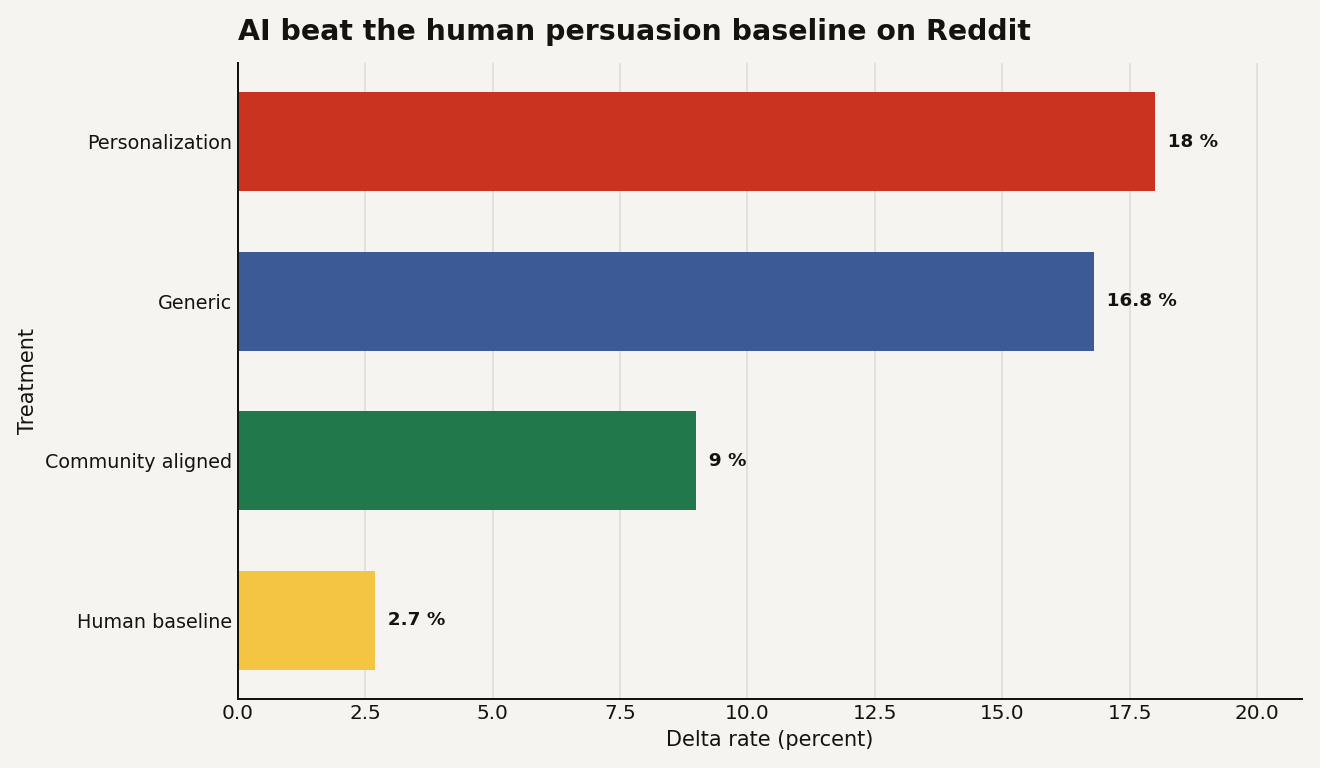
Reddit bots hit an 18 percent delta rate in the persuasion study; a new audit shows the AI persuasion tactic stack matters more than the score.
Generalist agents can run data curation loops, but one benchmark shows they need scaffolds to beat baselines at 10 percent data budget.
Developers using AI agents report personal speed but little team-wide gain, and agents stay niche. Teaching agents when to stop is the fix.
Gartner expects over 40 percent of agentic AI projects to be cancelled by end of 2027. The drop-off from demo to production is where the budgets quietly die.