Engineering
Agent-aware KV cache cuts serving latency by 45 percent
A runtime layer that learns how agents reuse context cuts TTFT by up to 45 percent and lifts throughput by up to 57 percent on multi-agent workloads.
3 stories tagged kv-cache.
A runtime layer that learns how agents reuse context cuts TTFT by up to 45 percent and lifts throughput by up to 57 percent on multi-agent workloads.
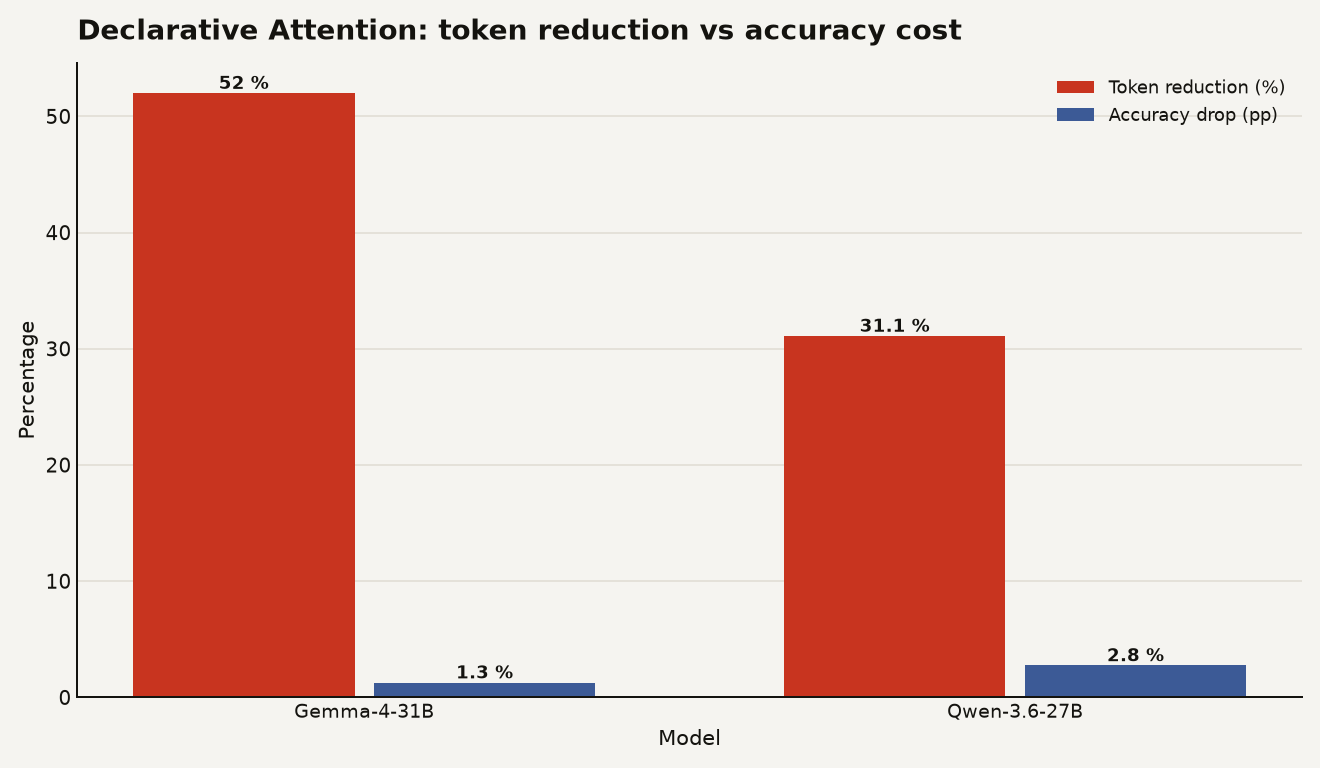
Declarative Attention lets LLMs declare which context regions to read, cutting attended tokens 52% with only 1.27pp accuracy loss on Gemma-4-31B.
Agentic coding dominates Copilot at scale. A study of 13M sessions finds 87% of LLM calls are agent-initiated, rewriting AI infrastructure planning.