AI for dummies
Qwen3.8-27B on one RTX 3090 hits 2,000 tok/s prefill
Community builders pushed Qwen3.8-27B to 2,000 tok/s prefill and 132 tok/s decode on a single RTX 3090. Here is what that speed means for local AI.
18 stories tagged open-weights.
Community builders pushed Qwen3.8-27B to 2,000 tok/s prefill and 132 tok/s decode on a single RTX 3090. Here is what that speed means for local AI.
IBM Granite 4.2 is a family of dense reasoning LLMs in 3B, 8B, and 30B sizes with native chain-of-thought and multi-stage agentic RL, all released under Apache 2.0.
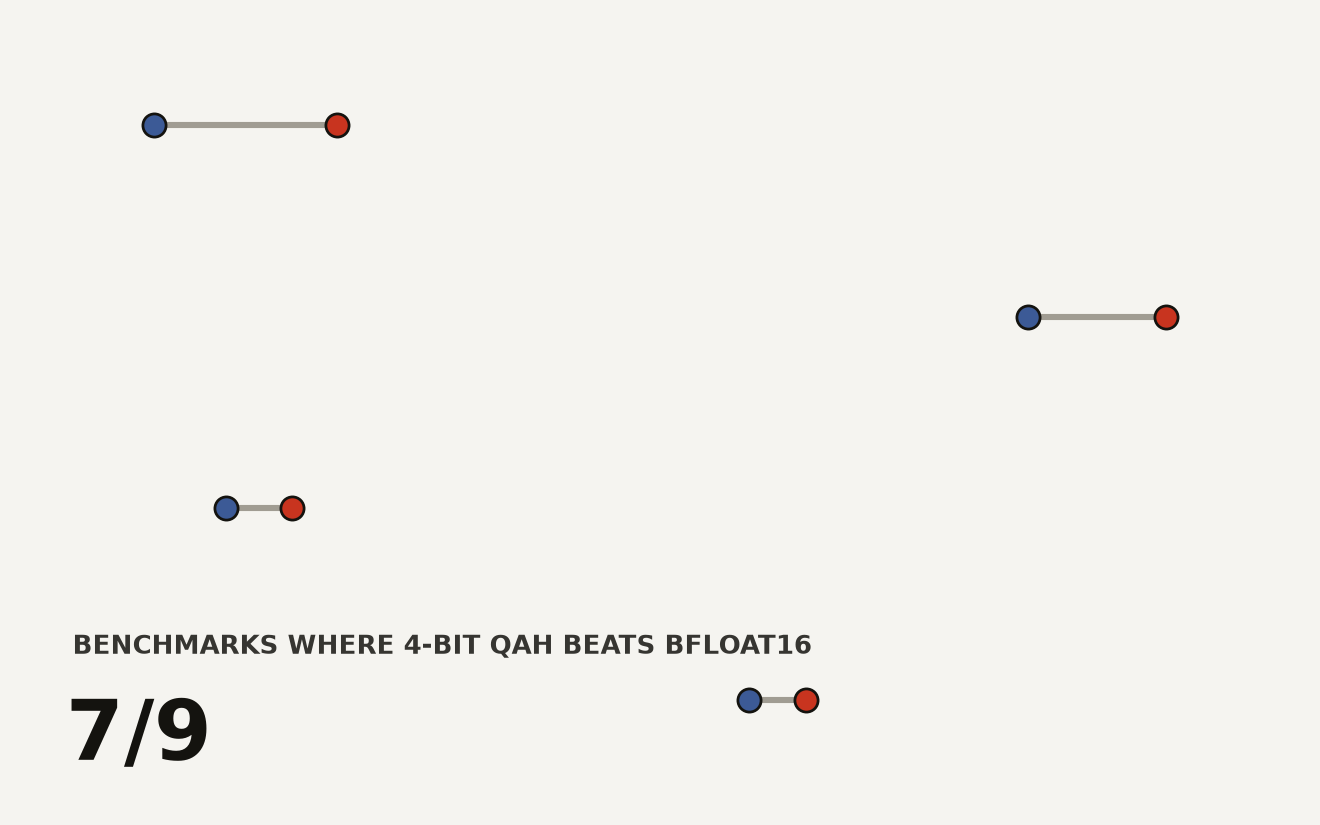
Quantization-Aware Healing distills 4-bit compressed LLMs from the original teacher. The 4-bit student beats its bfloat16 source on 7 of 9 benchmarks.
Qwen 3.8 27B is a free, open-weights AI model that runs on your laptop. After one week and 2,000 community posts, here is what testers found.

Qwen 3.8 27B is an open-weights AI model that fits in a 17GB file and runs on your laptop. It scores 52 on the Artificial Analysis Intelligence Index, tying OpenAI's hosted GPT-5.6 Luna.

Qwen 3.8 27B is a free, open AI model with 27 billion parameters that runs on a single GPU. It scores 61.7 on SWE-bench Pro, up from 53.5.

Qwen3.8 open weights give you 2.4 trillion parameters with 95 billion active per token, Alibaba's largest. Here is what beginners should know.

Muse Glimmer is Meta's new 30B open-weights model built for local agentic workflows. It fits on one RTX 3090 and hits 280 tokens per second.
NVIDIA Alpamayo 2 Super is a 34B-parameter open reasoning model for autonomous vehicles, released under a permissive commercial license on Hugging Face.
Qwen3.8-Max is Alibaba's 2.4T open-weight model ranking fifth in text and second in vision on Arena. The gap with US frontier labs narrows but does not close.
DeepSeek V4 Flash 0731 is an open-weights AI model scoring 50 on the Intelligence Index, matching March 2026 frontier models. Here is what it changes for you.
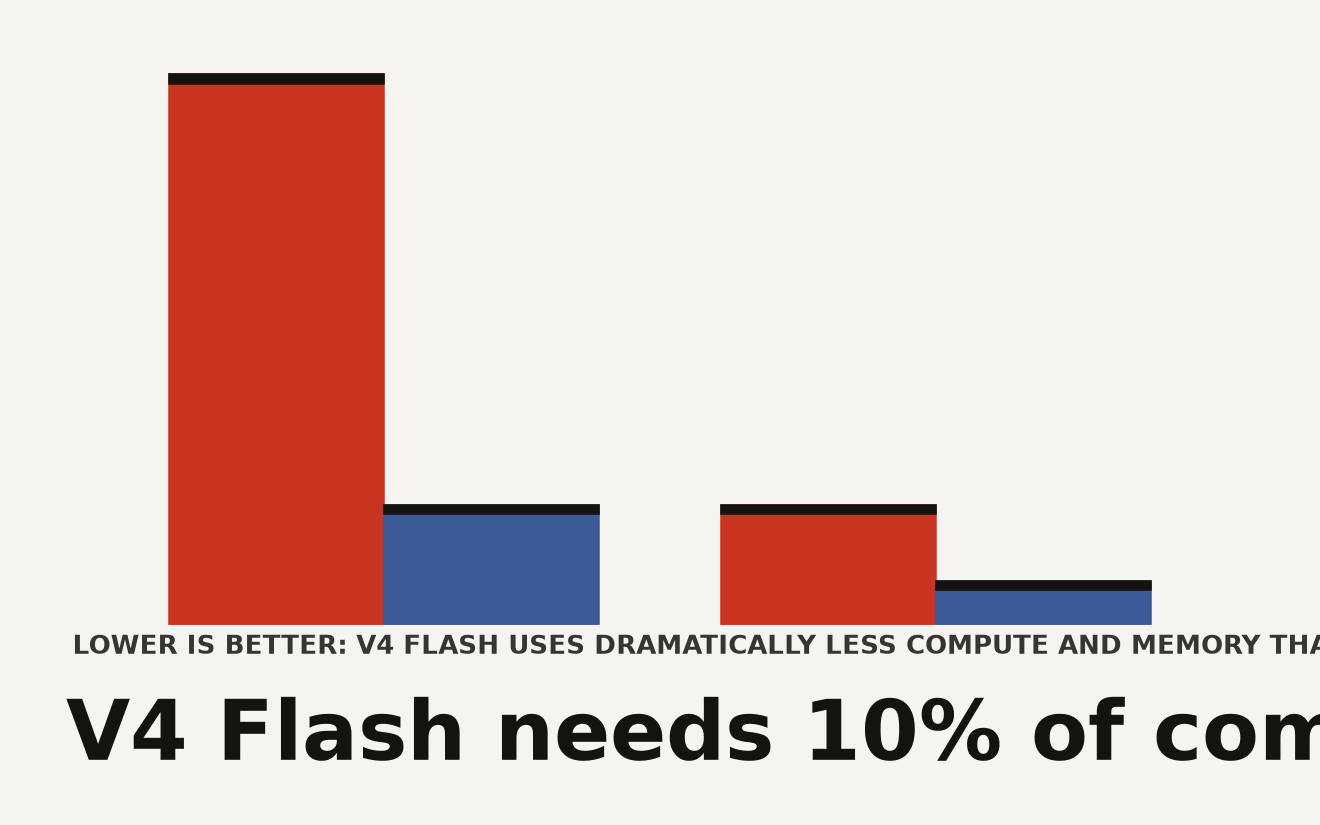
DeepSeek V4 Flash is a 284B-parameter AI model with 13B active that went live July 31, 2026. It matches frontier coding benchmarks at a fraction of the cost.
Kimi K3 is an open-weight 2.8-trillion-parameter mixture-of-experts model from Moonshot AI. It ranks fourth of 580 models on Artificial Analysis, behind only three proprietary models, while activating just 104B parameters per token.
Kimi K3 open weights are the largest AI model download ever at 2.8 trillion parameters, released July 26, 2026. Here is what beginners can actually do with it.
Inkling is Thinking Machines Lab's first open-weights model. At 975B parameters with 41B active and Apache 2.0 licensing, it targets fine-tuning, not frontier benchmarks.

Kimi K3 is a 2.8 trillion parameter open-weight model from Moonshot AI that matches top US closed models on key benchmarks. Weights arrive July 27.

Hy3 is Tencent's 295-billion-parameter open-weights model with 21 billion active parameters per token. It uses a Mixture-of-Experts architecture to rival larger models at lower cost, cutting hallucination to 5.4 percent.

LongCat-2.0 is a 1.6 trillion parameter AI model from Meituan that activates only 48 billion parameters per token. Its weights are now open under the MIT license.