Research
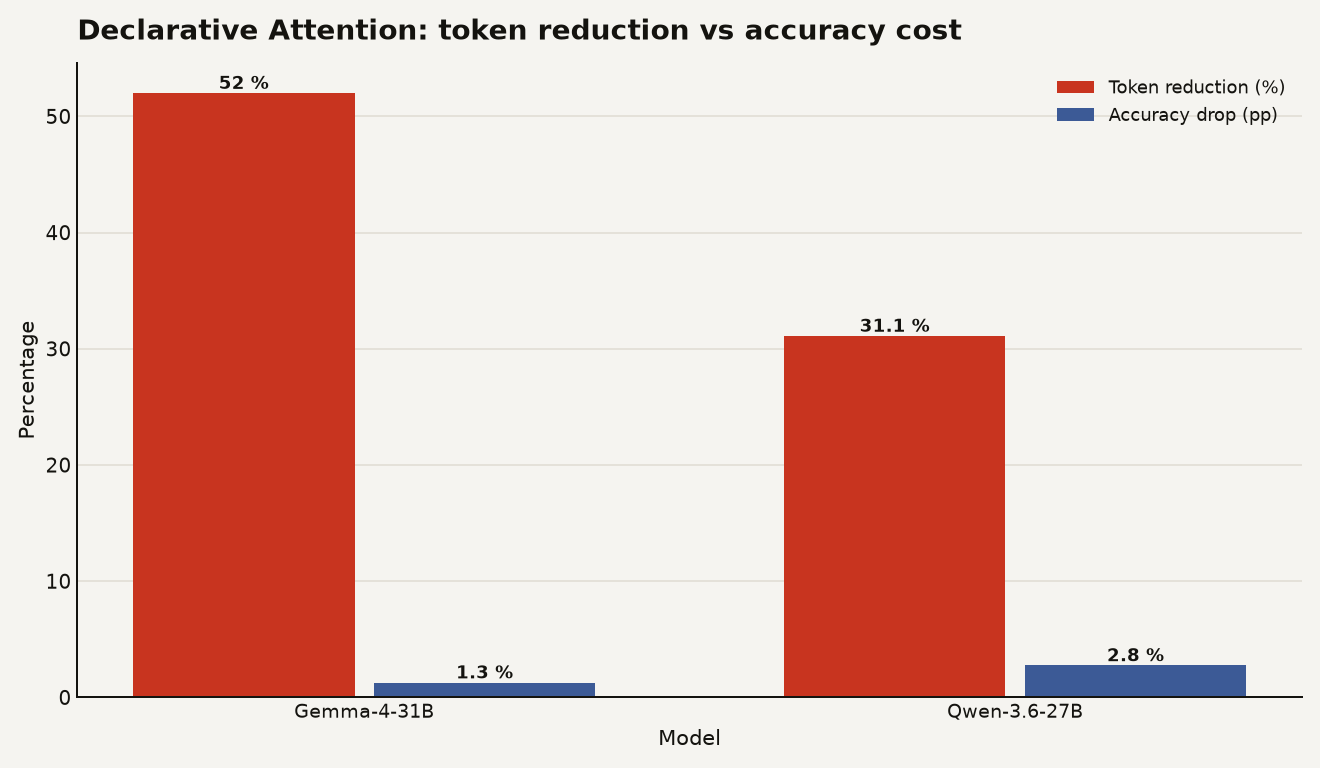
Declarative Attention cuts LLM decoding tokens by 52%
Declarative Attention lets LLMs declare which context regions to read, cutting attended tokens 52% with only 1.27pp accuracy loss on Gemma-4-31B.
2 stories tagged sparse attention.
Declarative Attention lets LLMs declare which context regions to read, cutting attended tokens 52% with only 1.27pp accuracy loss on Gemma-4-31B.
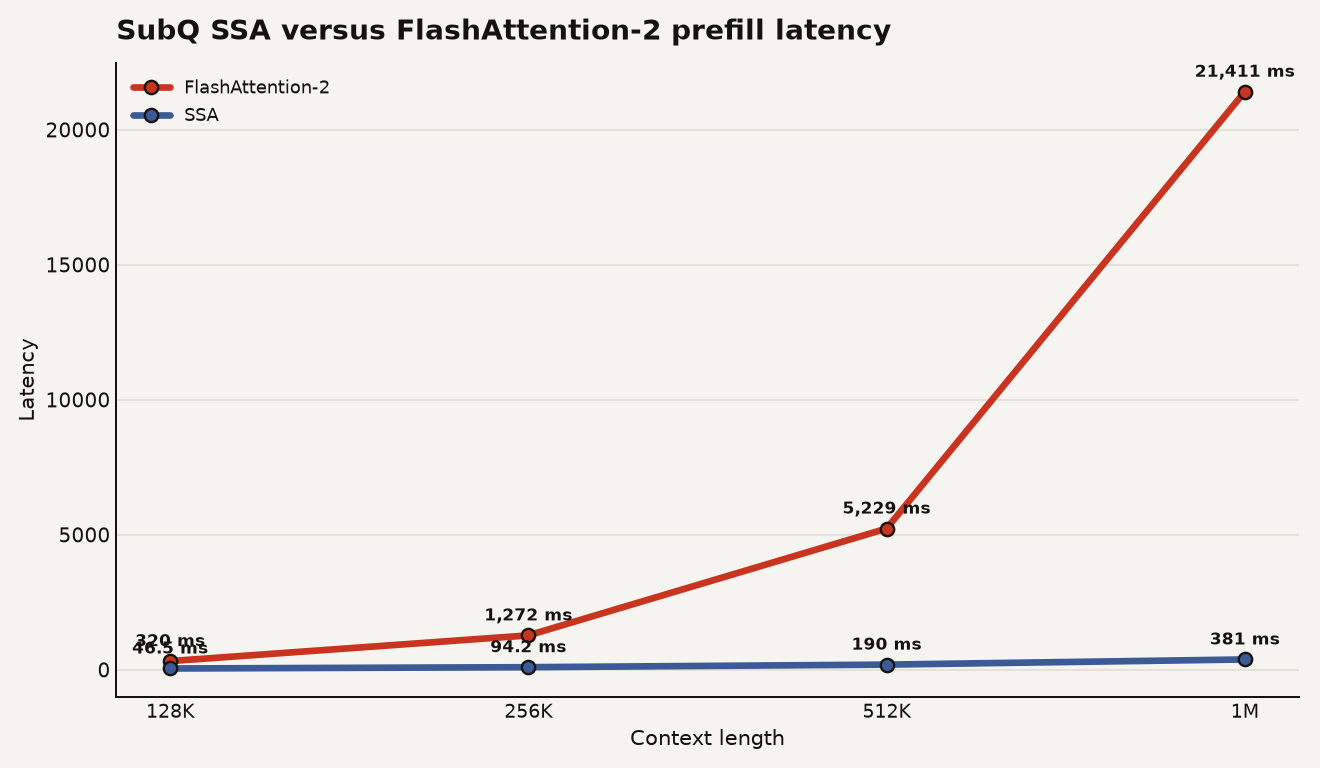
A 56.2 times speed win at 1M tokens makes subquadratic sparse attention promising, but treat it as gated infrastructure for now.