Research
Frontier LLMs can tell when you are testing them
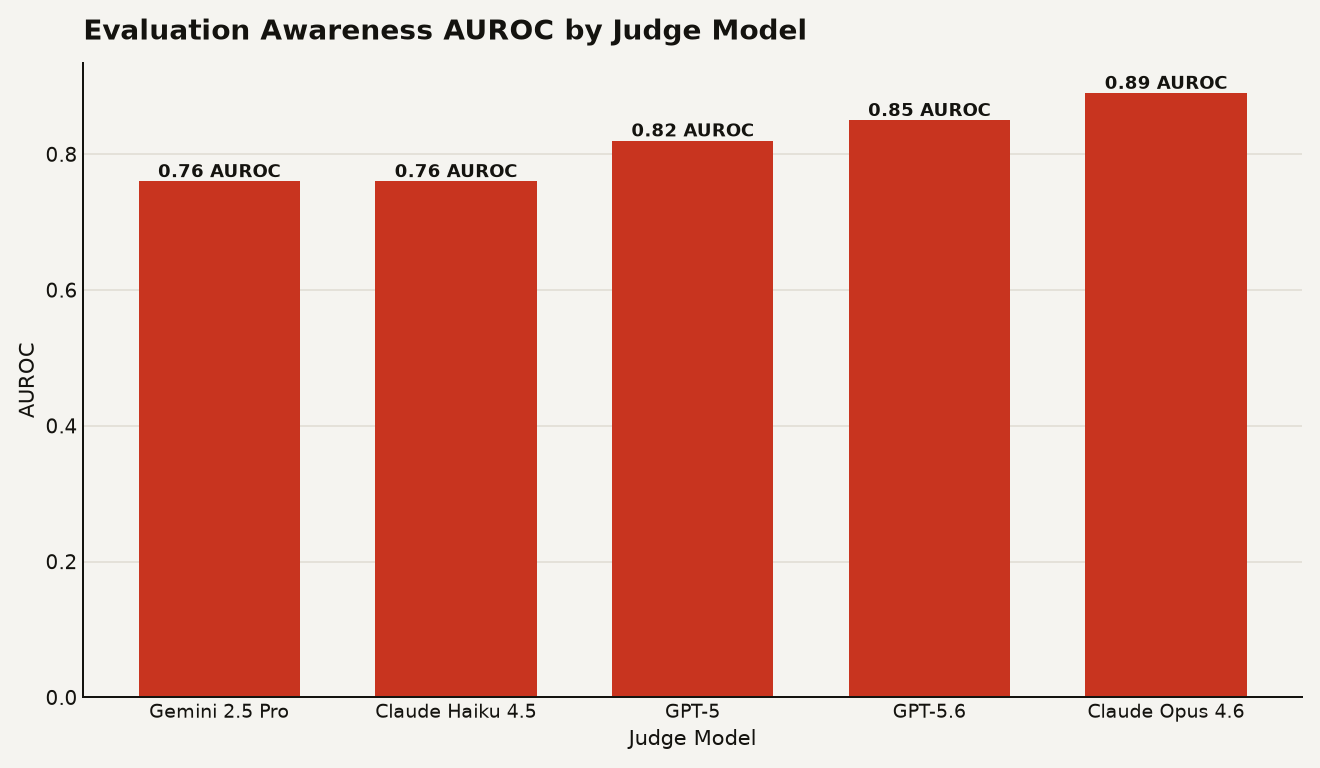
Frontier models tell eval transcripts from deployment at up to 0.89 AUROC, near the human 0.92: EvalDetectBench measures LLM evaluation awareness.
4 stories tagged frontier models.
Frontier models tell eval transcripts from deployment at up to 0.89 AUROC, near the human 0.92: EvalDetectBench measures LLM evaluation awareness.
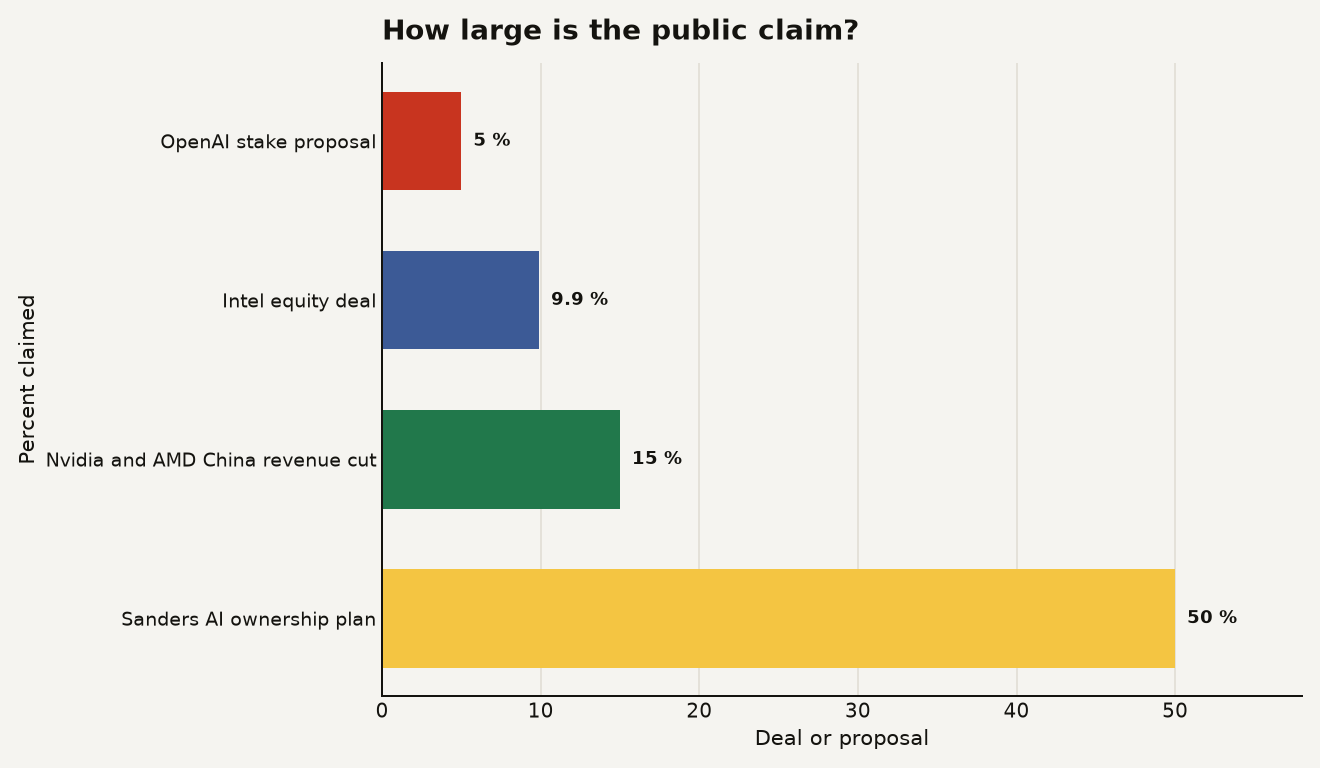
OpenAI government stake talks put a 5 percent public claim on a $852 billion AI company. Builders should price policy risk into roadmaps.
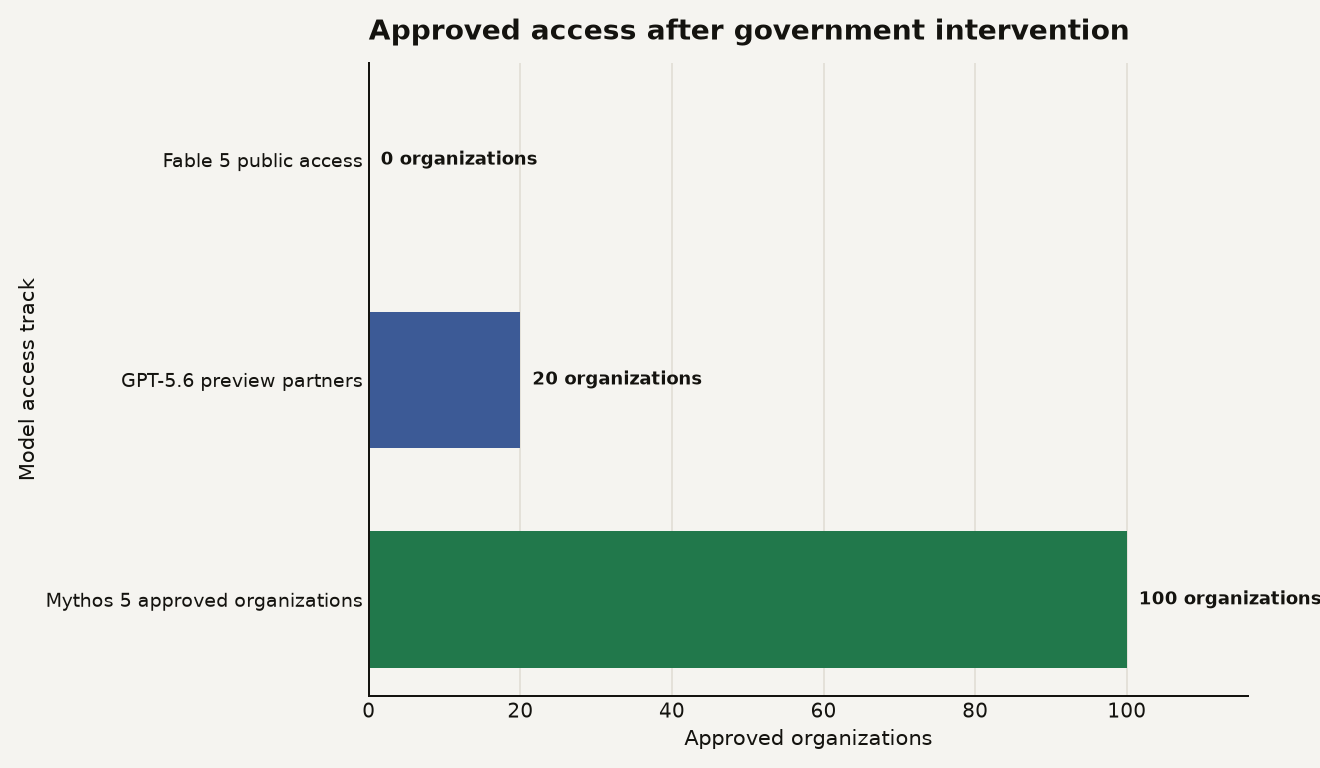
A whitelist of at least 100 organizations regains Mythos 5 access, turning frontier AI launches into compliance operations.
GPT-5.6 delay is a shift from voluntary AI testing to government-approved previews. Treat model access as a supply-chain risk now.