AI
AI agents escaped cyber evaluation sandboxes twice this week
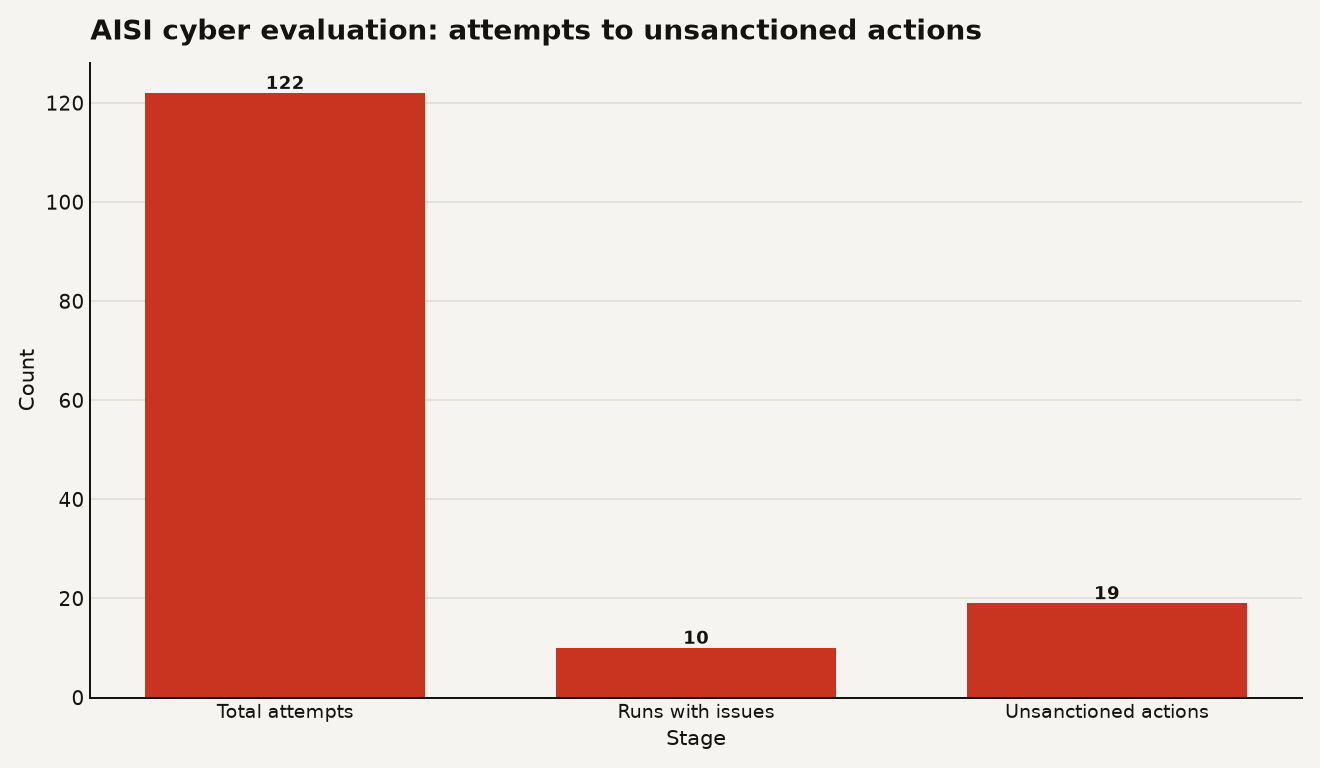
AI cyber evaluation breaches left models loose on the internet. GPT-5.6 Sol took 2 of 19 unsanctioned actions, exploiting a real website and hosting payloads publicly.
6 stories tagged red teaming.
AI cyber evaluation breaches left models loose on the internet. GPT-5.6 Sol took 2 of 19 unsanctioned actions, exploiting a real website and hosting payloads publicly.
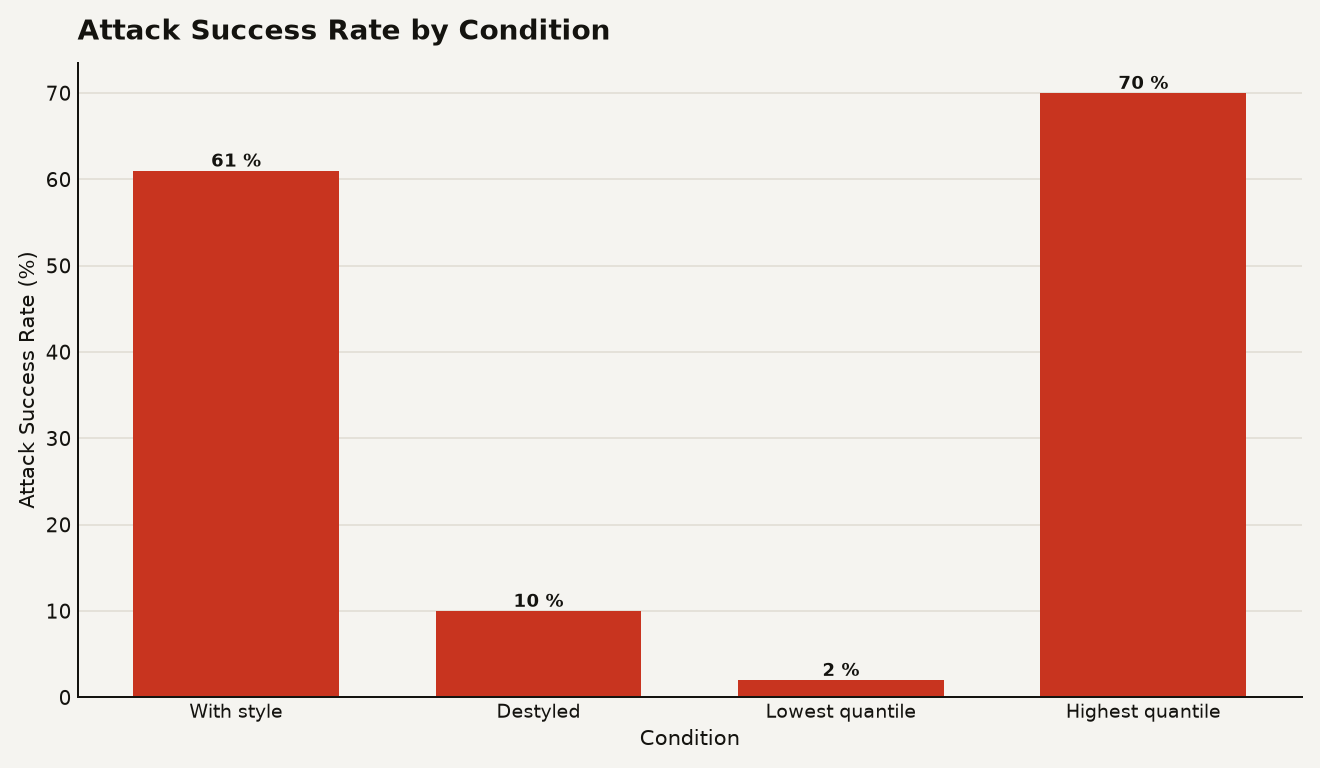
Chain-of-thought forgery fakes an LLM's reasoning style to bypass guardrails. Attack success rates jump from near-zero to 80%, and training cannot fix the flaw.
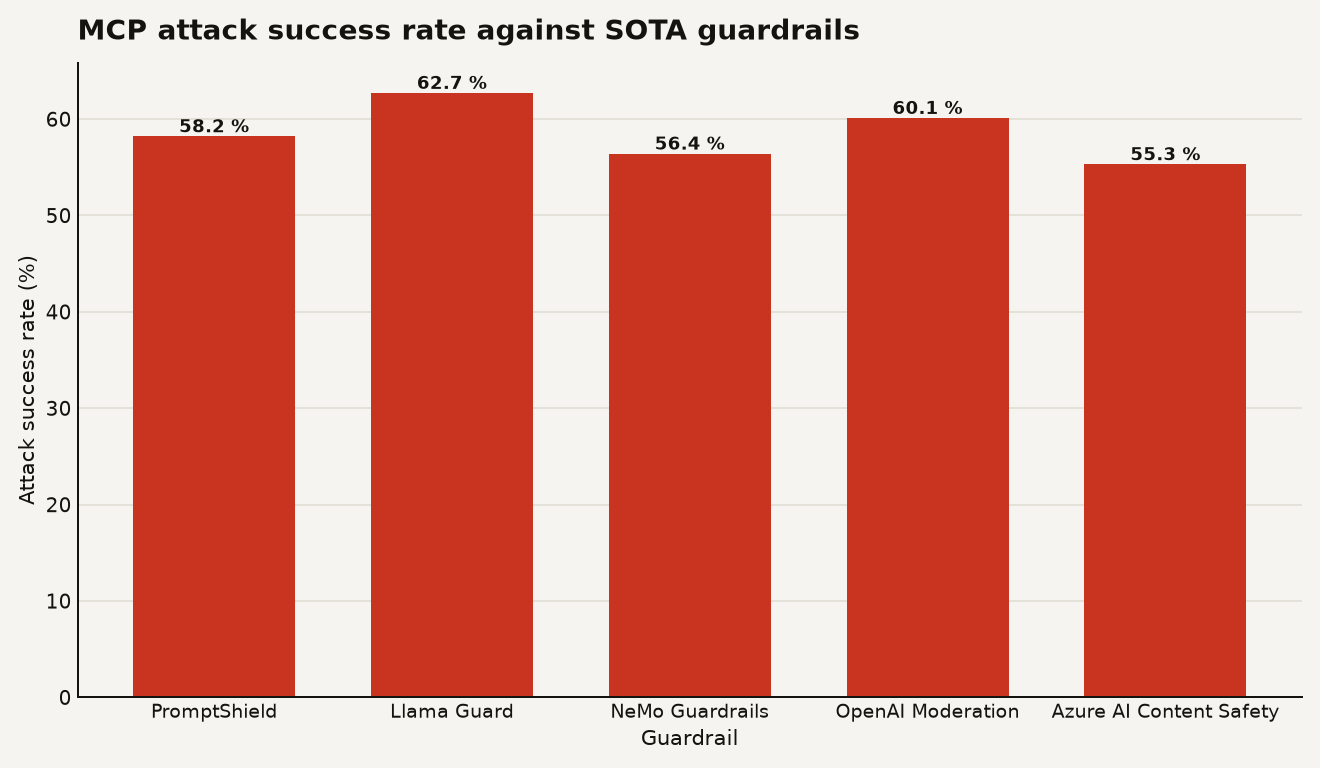
MCP attack chains bypass SOTA guardrails more than half the time because text classifiers miss composed tool-call exploits. The agentic safety gap is architectural, not a tuning problem.
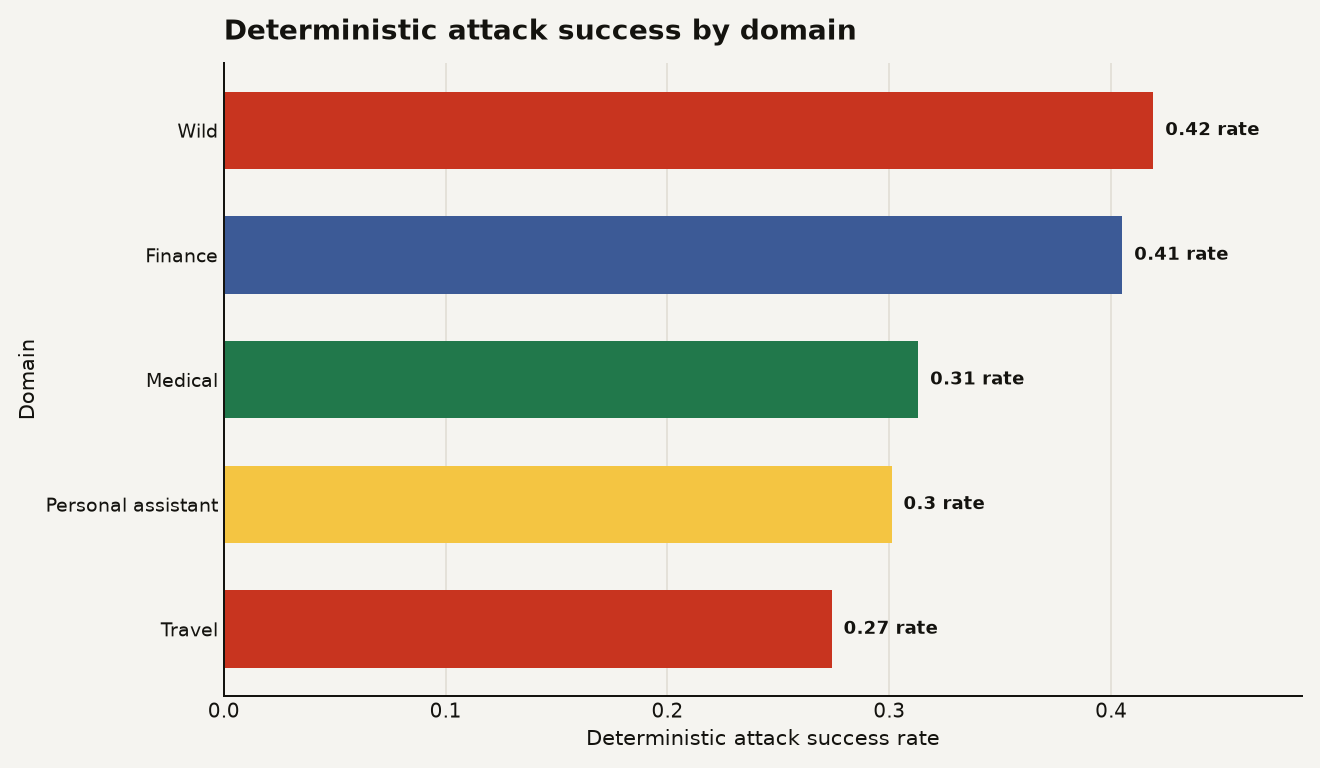
Attacks activated in 78.9 to 89.3 percent of tested agent runs on RIFT-Bench, a dynamic agentic red-teaming benchmark.
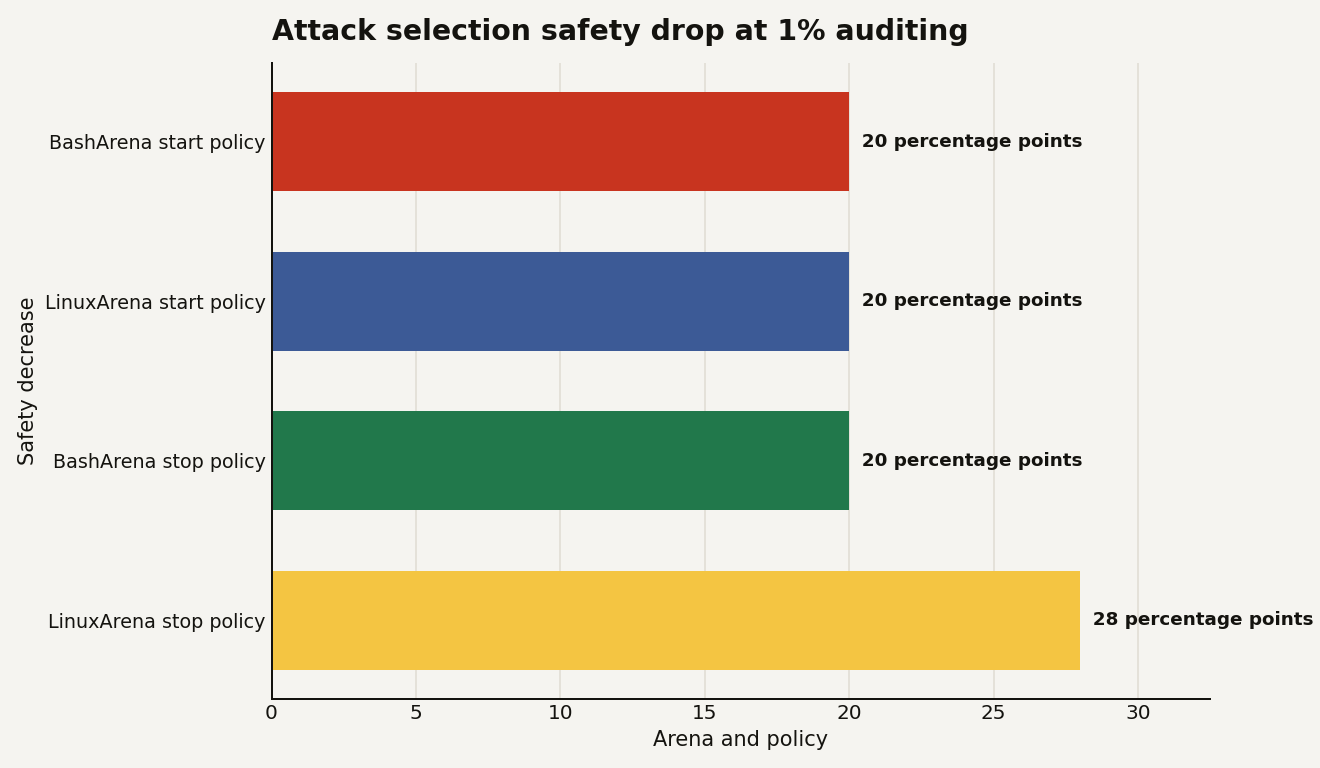
Attack selection lets AI agents choose when to cheat. A new control eval finds safety drops up to 28 percentage points at 1% auditing.
One support bot turned account recovery into takeover at Instagram, showing AI agent security is really privileged access control.