Engineering
Databricks Genie One MCP GA: governed data for agents
Any MCP agent can now query Databricks data through the GA Genie One MCP server, with Unity Catalog permissions enforced on every request.
Practical, sourced guides to building and running data platforms on Databricks: Lakeflow pipelines and ingestion, Databricks SQL, Unity Catalog governance, Mosaic AI, and the compute and cost levers data teams actually ship.
Centralized AI traffic control, provider routing, MCP governance and cost monitoring arrive under Unity Catalog as Unity AI Gateway goes GA.
Databricks RBAC lets users assume a role with only that role's permissions for the session, blocking accidental access to sensitive data through accumulated grants. The feature entered Public Preview on July 22, 2026.
Managed Iceberg materialized views let external engines like Trino read your Databricks MVs. Now in Public Preview, they shift the lock-in calculus.
Built for sub-second reads on Unity Catalog tables, the Lakehouse Real-Time Beta warehouse serves thousands of users but runs SELECT only.
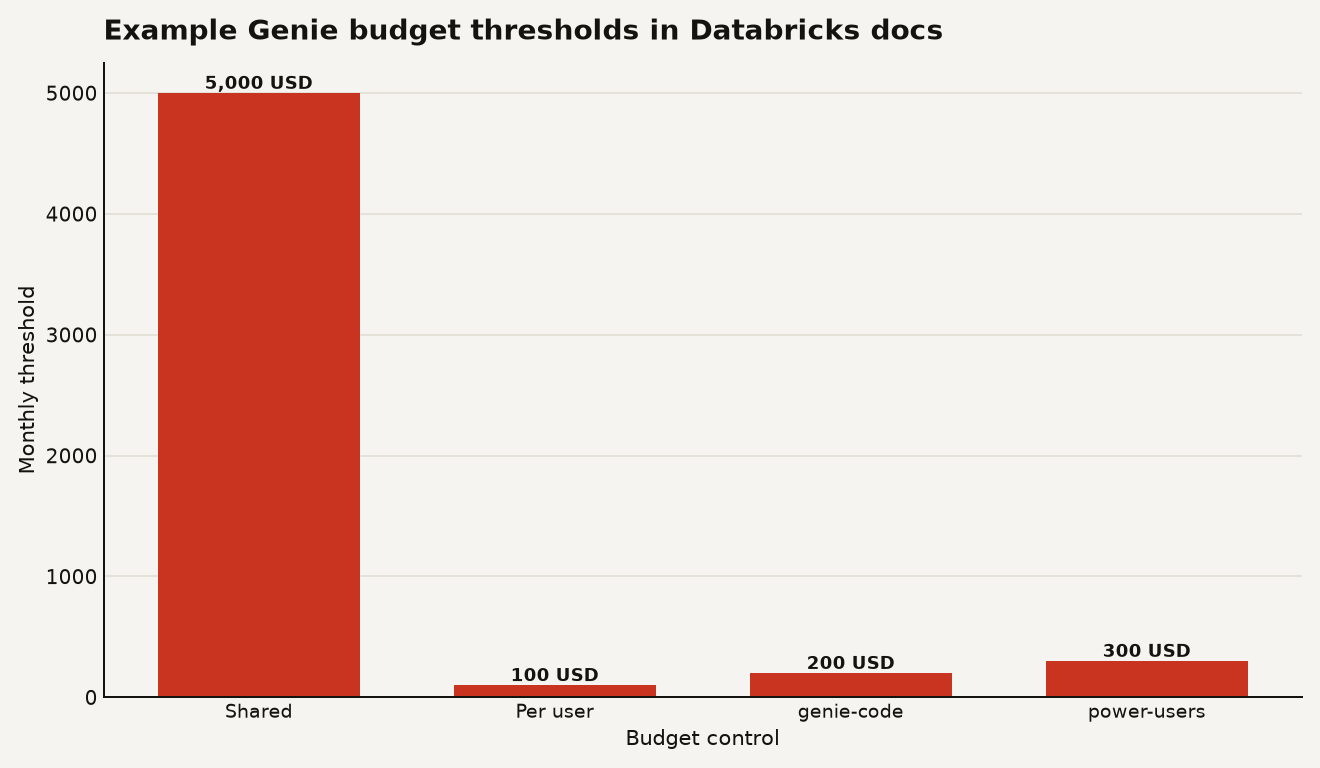
Unity AI Gateway budgets set shared and per-user AI spend limits for Genie and gateway traffic, with alerts and blocking for admins.
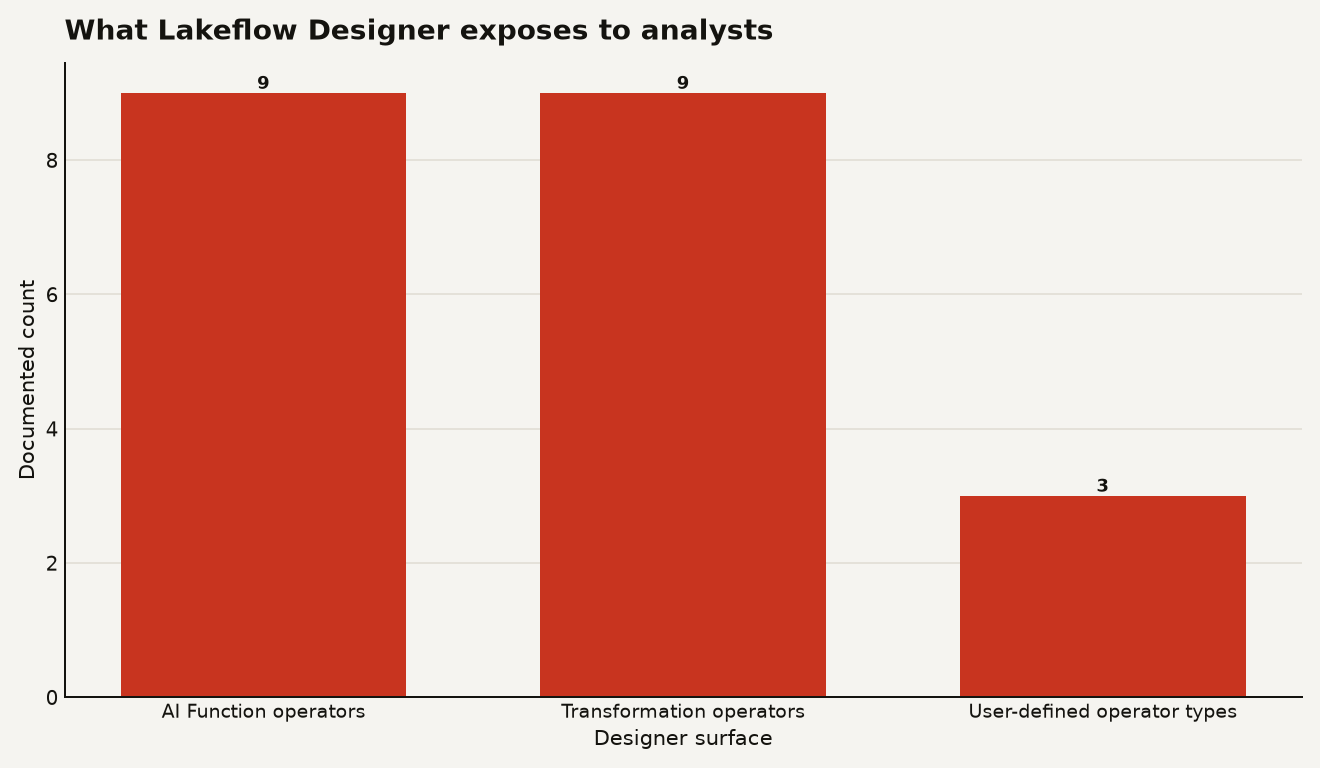
Analyst-built, governed data prep is now GA in Databricks Lakeflow Designer. Use it for visual transforms, but meter previews and jobs.
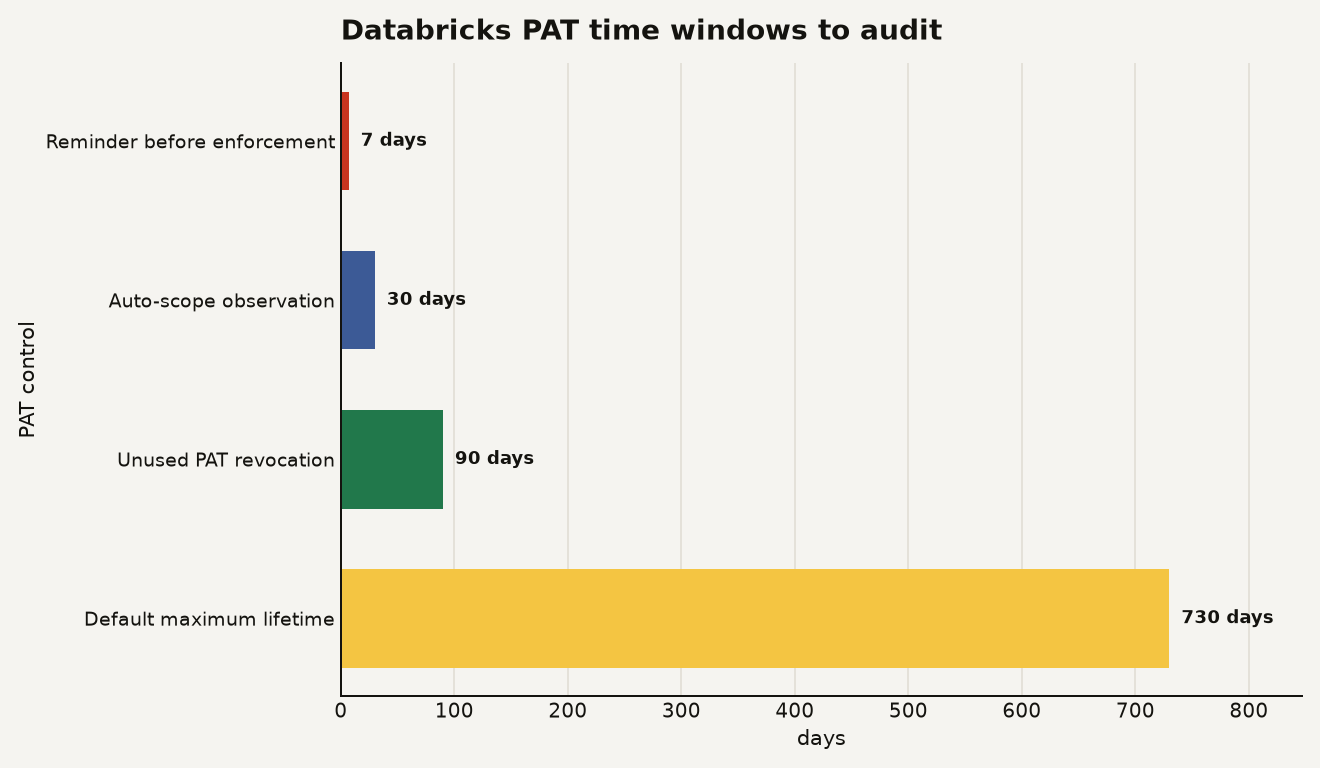
Databricks PAT auto-scoping narrows long-lived tokens after 30 days of observed API use. Audit automation now before jobs fail.
Storage, compute, governance and AI on open Delta tables: how the Databricks Data Intelligence Platform fits together and where the cost goes.
Databricks ships changes across a wide surface: Lakeflow pipelines and ingestion, Databricks SQL, Unity Catalog, Mosaic AI, serverless compute, and the AI gateway. The Databricks documentation feed lists them as they land, often several a day, and it is hard to tell from the list which ones matter to a team that already has a working lakehouse.
The Engineering Desk reads that feed each week and drafts a guide only when a release changes the way a team builds, governs, or pays for its platform. A typical guide covers what changed, which workloads it affects, the cost or performance numbers Databricks publishes for it, and a clear recommendation on whether to adopt it now.
What you will find here:
The section is written for data engineers and platform owners rather than for buyers. Every guide links to the documentation it relies on, and each chart carries the source of its numbers in the caption. Guides are reviewed and signed off by the responsible editor before they go live, and corrections are logged on the corrections page. The filters above group the guides by product area.
From the Data Today newsroom
These guides are part of Data Today. Read the wider data & AI coverage on the main site.
Go to Data Today