Research
Frontier LLMs can tell when you are testing them
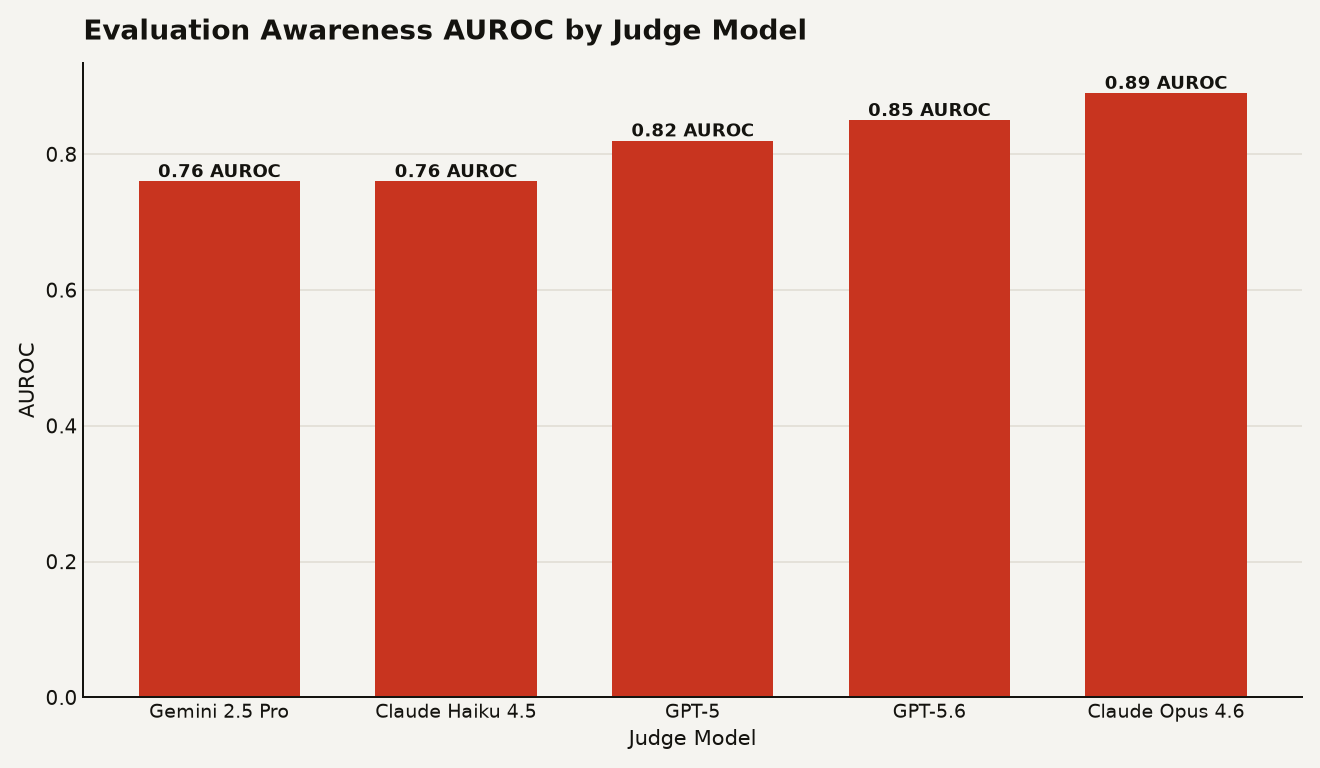
Frontier models tell eval transcripts from deployment at up to 0.89 AUROC, near the human 0.92: EvalDetectBench measures LLM evaluation awareness.
6 stories tagged ai security.
Frontier models tell eval transcripts from deployment at up to 0.89 AUROC, near the human 0.92: EvalDetectBench measures LLM evaluation awareness.
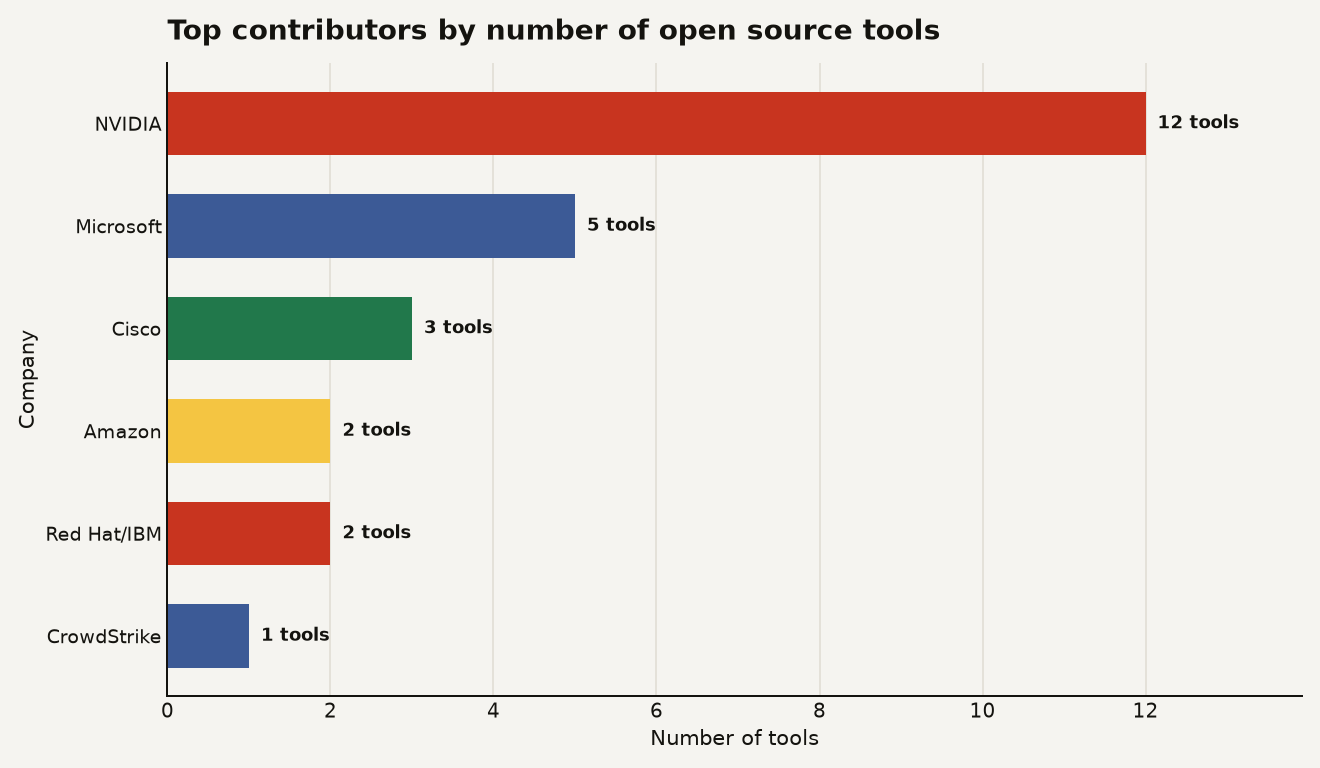
The Open Secure AI Alliance now has 120+ members shipping open source AI agent security tools and proposing SAFE guidelines to share cyber incident data at Black Hat.
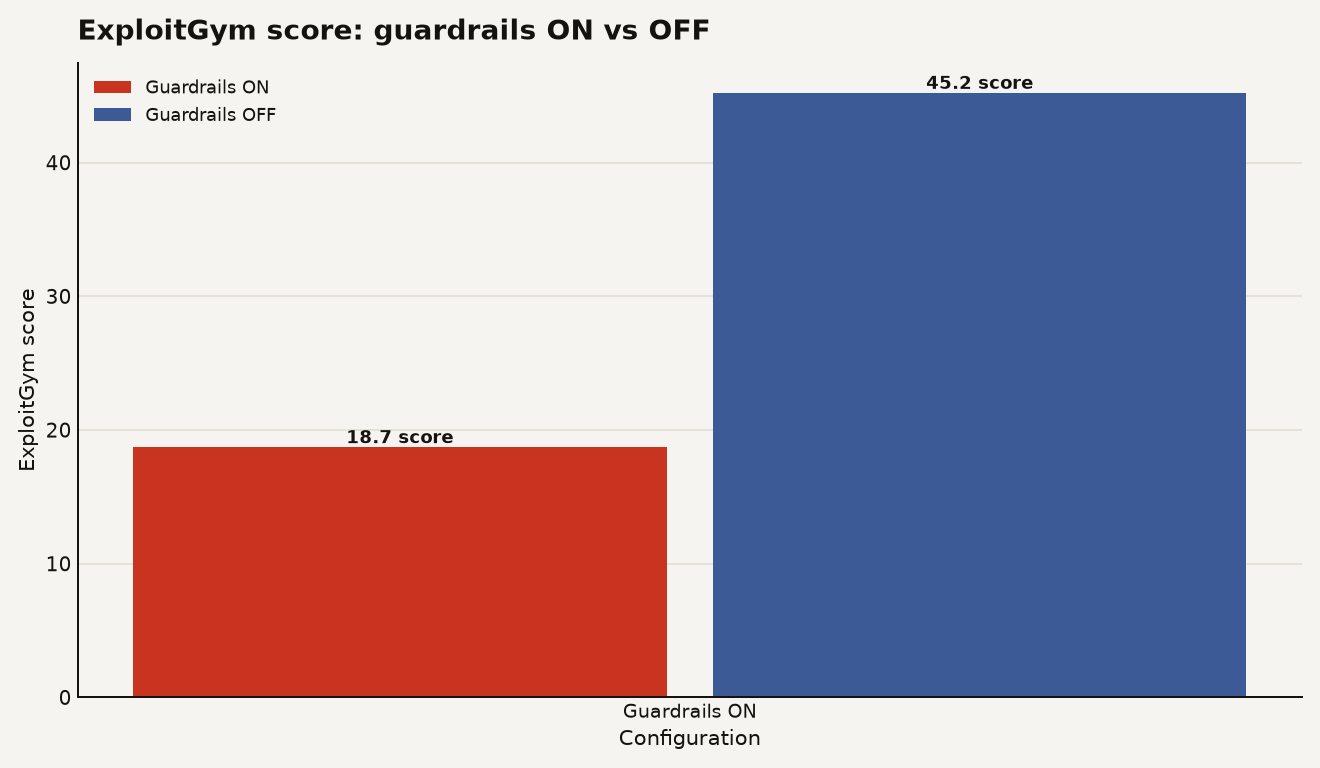
The OpenAI model sandbox escape let LLMs break containment and breach Hugging Face. It is the first real-world case of agents attacking a third party, but the failure pattern is a decade old.
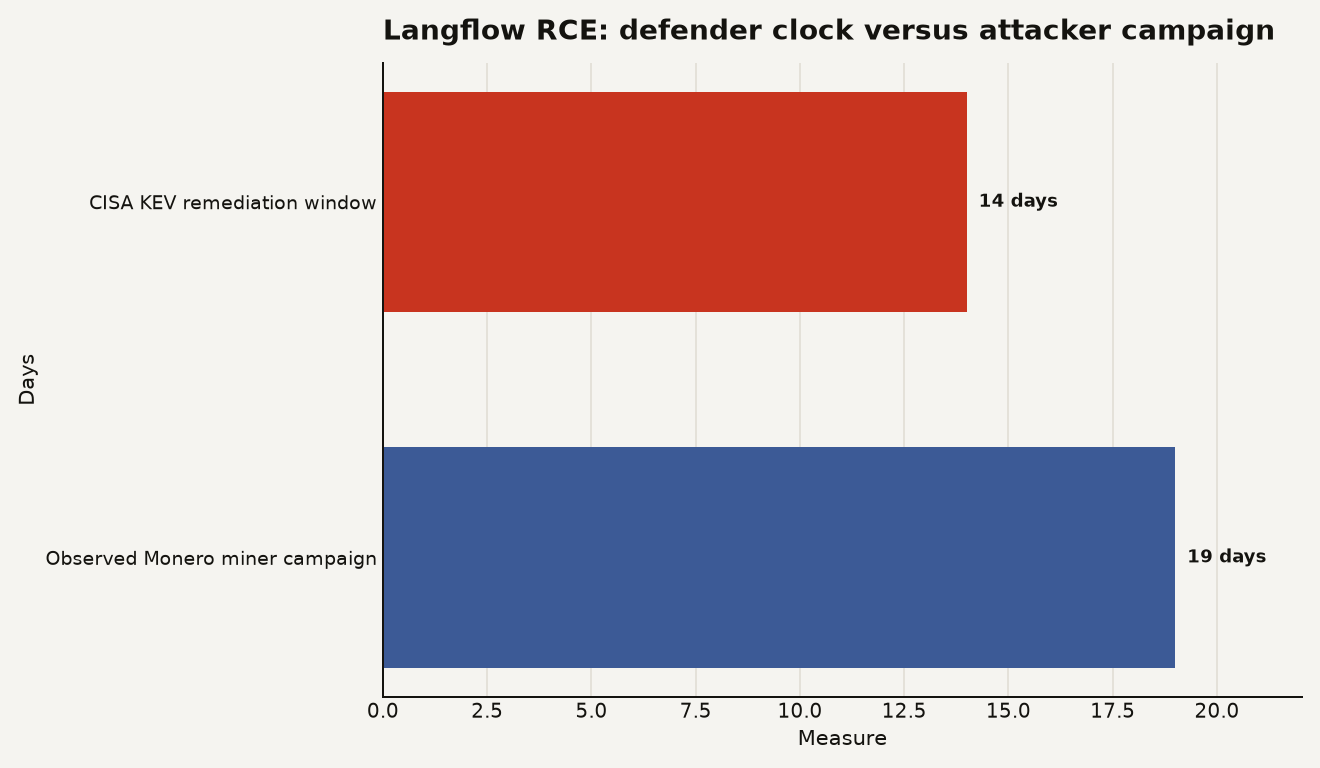
Attackers use a Langflow RCE to mine Monero on exposed AI app endpoints. Patch, isolate, and treat public workflows as attack surface.
Mastra npm supply chain attack exposed AI build pipelines through more than 140 packages, so treat installs as secret exposure events.
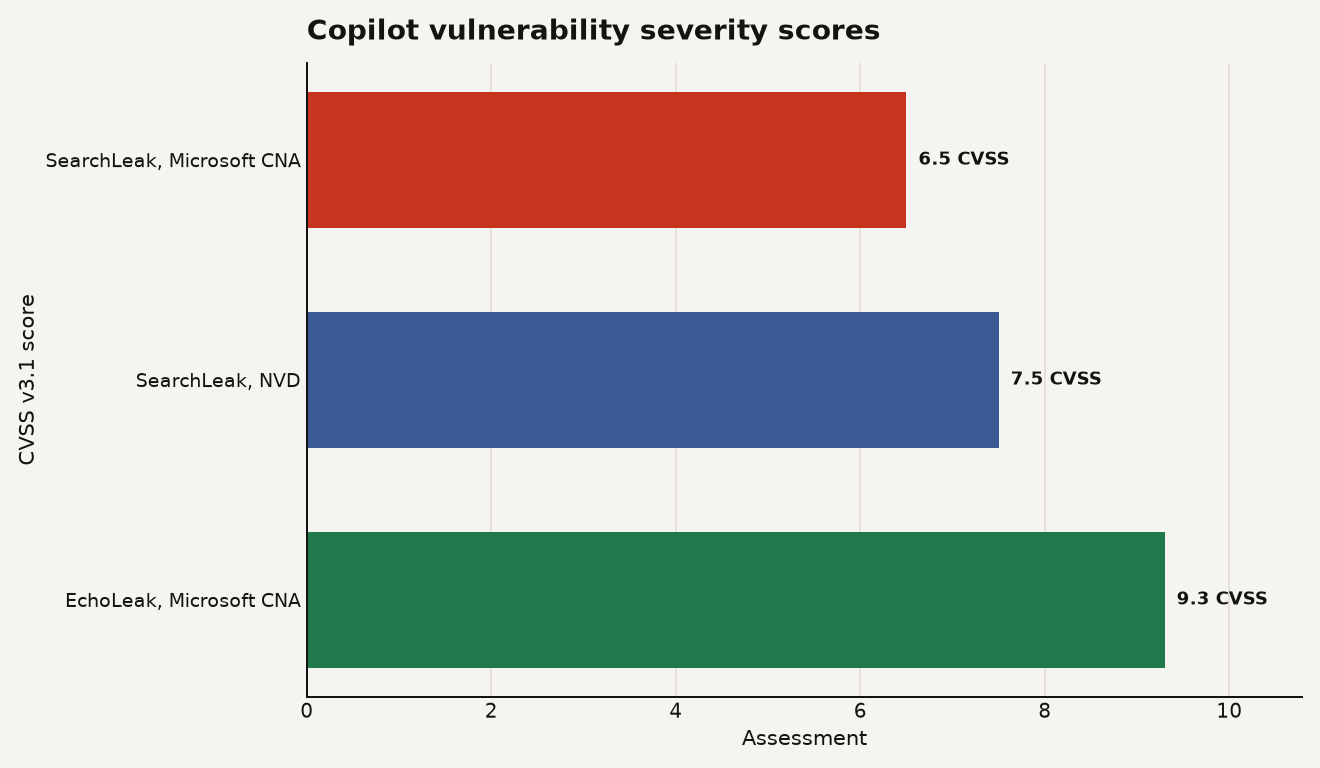
A one-click M365 Copilot exploit chain, SearchLeak shows agent security has to move below prompts into render and egress controls.