Research
Compressed 4-bit LLM outperforms full precision with QAH
Quantization-Aware Healing distills 4-bit compressed LLMs from the original teacher. The 4-bit student beats its bfloat16 source on 7 of 9 benchmarks.
4 stories tagged quantization.
Quantization-Aware Healing distills 4-bit compressed LLMs from the original teacher. The 4-bit student beats its bfloat16 source on 7 of 9 benchmarks.
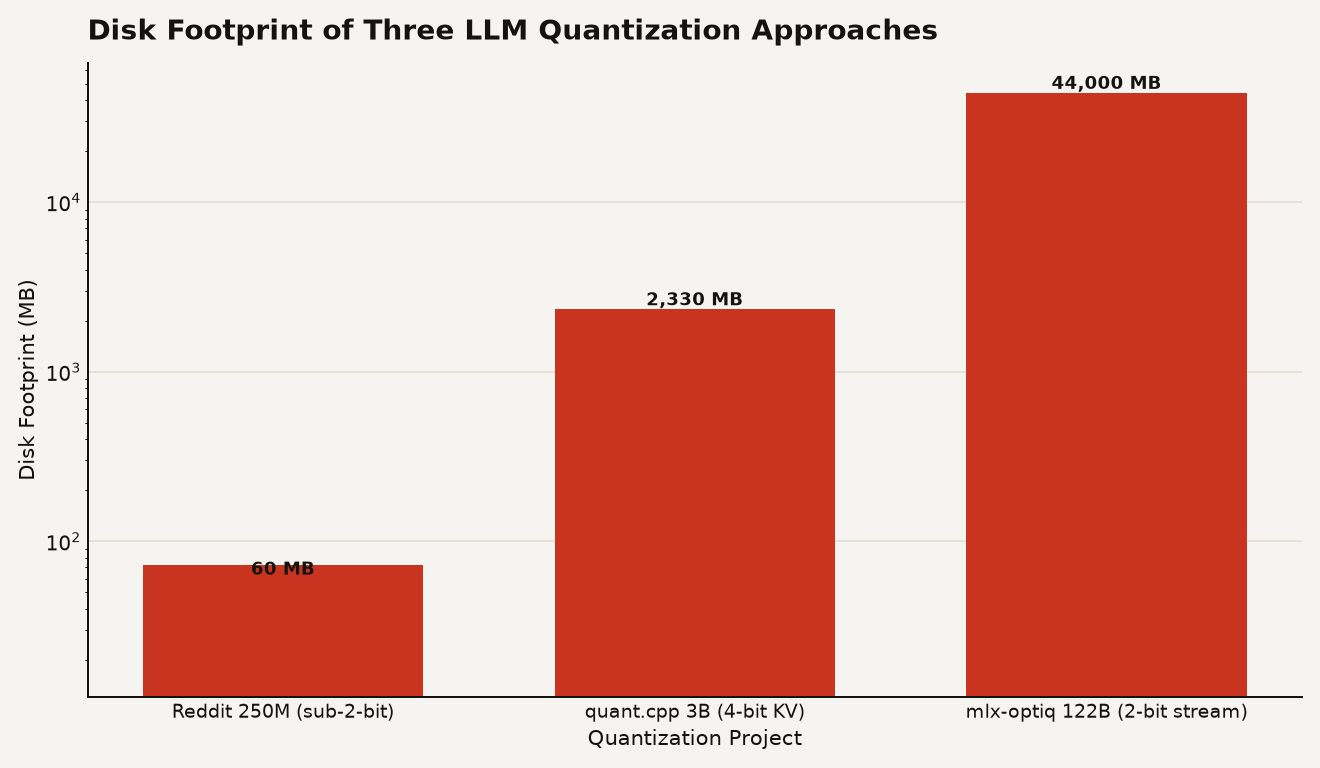
Sub-2-bit LLM quantization puts a 250M model in 60 MB of disk and 80 MB of RAM, running at 400 tok/s on a laptop CPU. The method keeps recent tokens at full precision and compresses the rest, pointing toward a new class of lightweight deployments.
Under KV-cache quantization, MoE route flips are detectable at AUC 0.772, but predicting their harm is at chance, which limits selective repair.
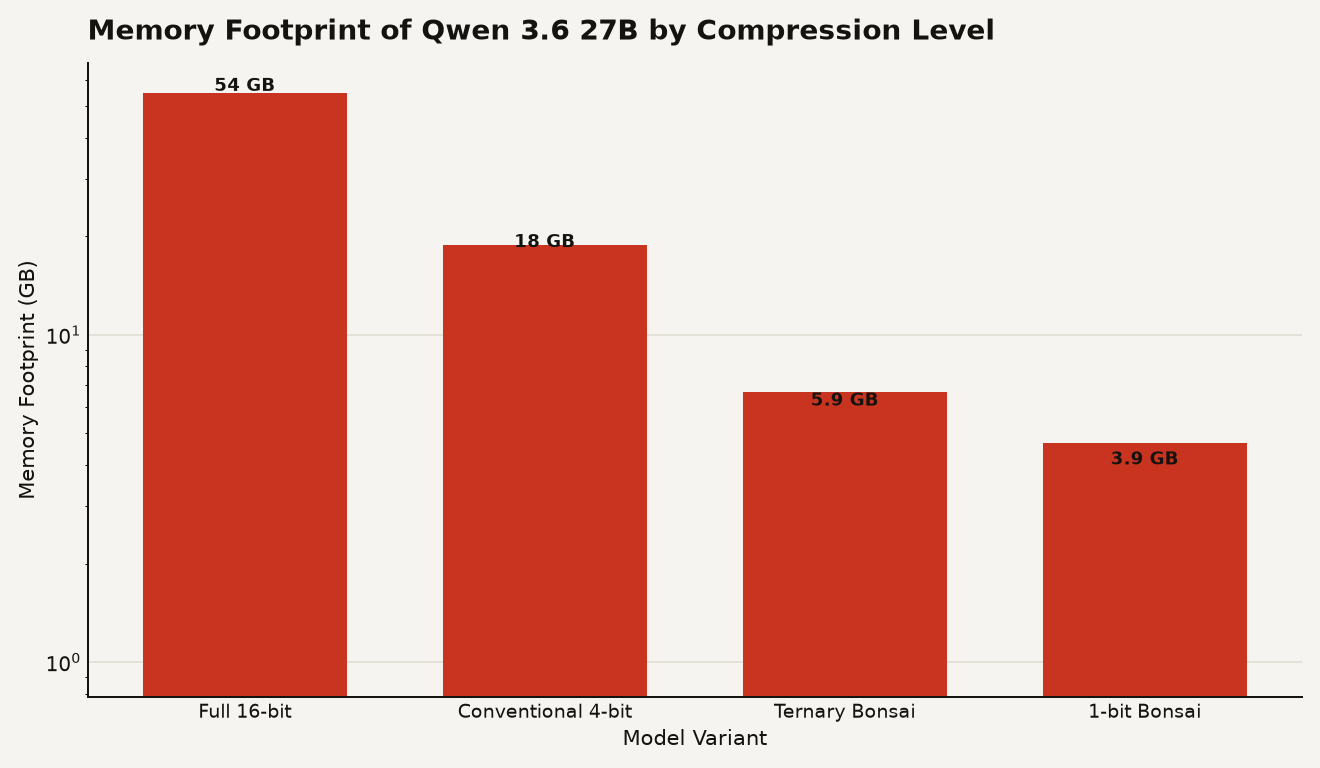
Storing each parameter as a single bit lets Bonsai 27B fit 27 billion parameters into 3.9 GB and run on an iPhone. Here is what 1-bit quantization costs.