Engineering
Why LoRA fails at multi-step procedural tasks
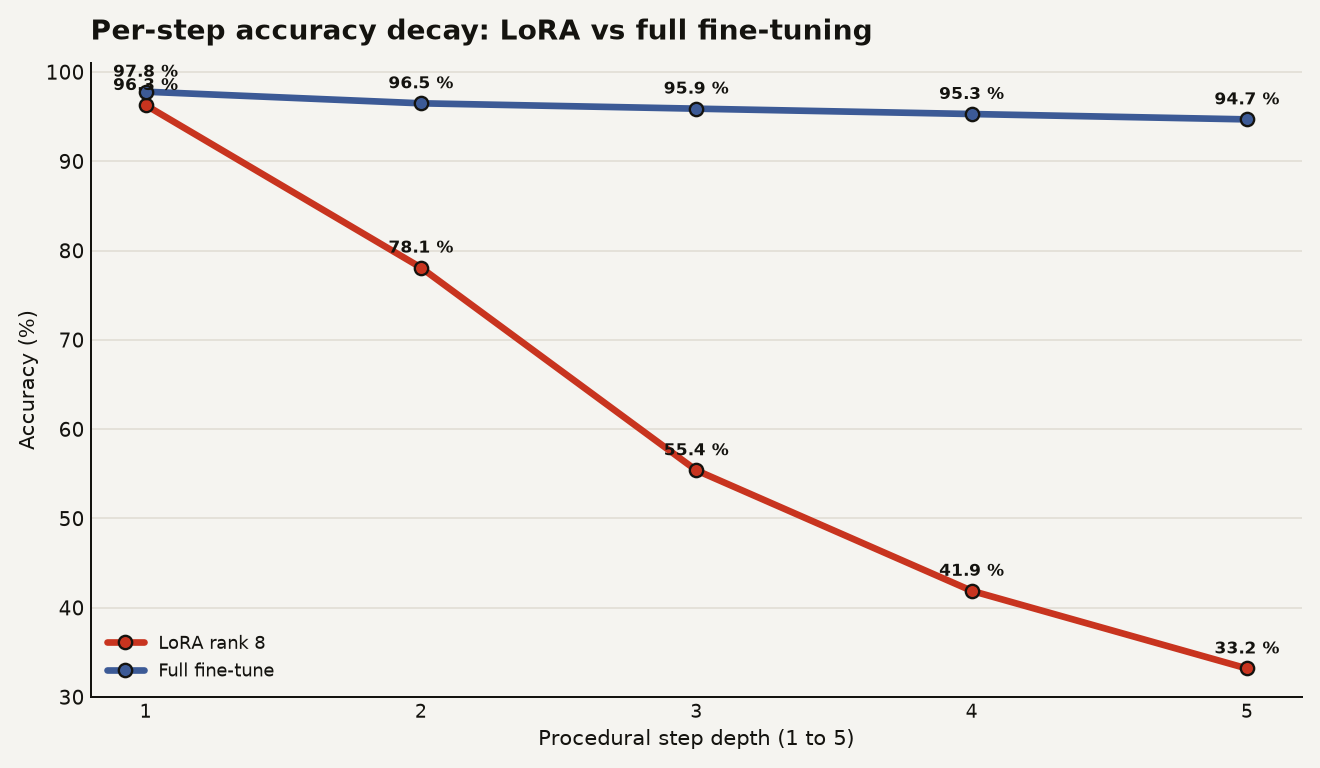
A 2026 arXiv paper shows LoRA fine-tuning fails to internalize multi-step procedures, degrading sharply once chains exceed four steps.
2 stories tagged llm training.
A 2026 arXiv paper shows LoRA fine-tuning fails to internalize multi-step procedures, degrading sharply once chains exceed four steps.
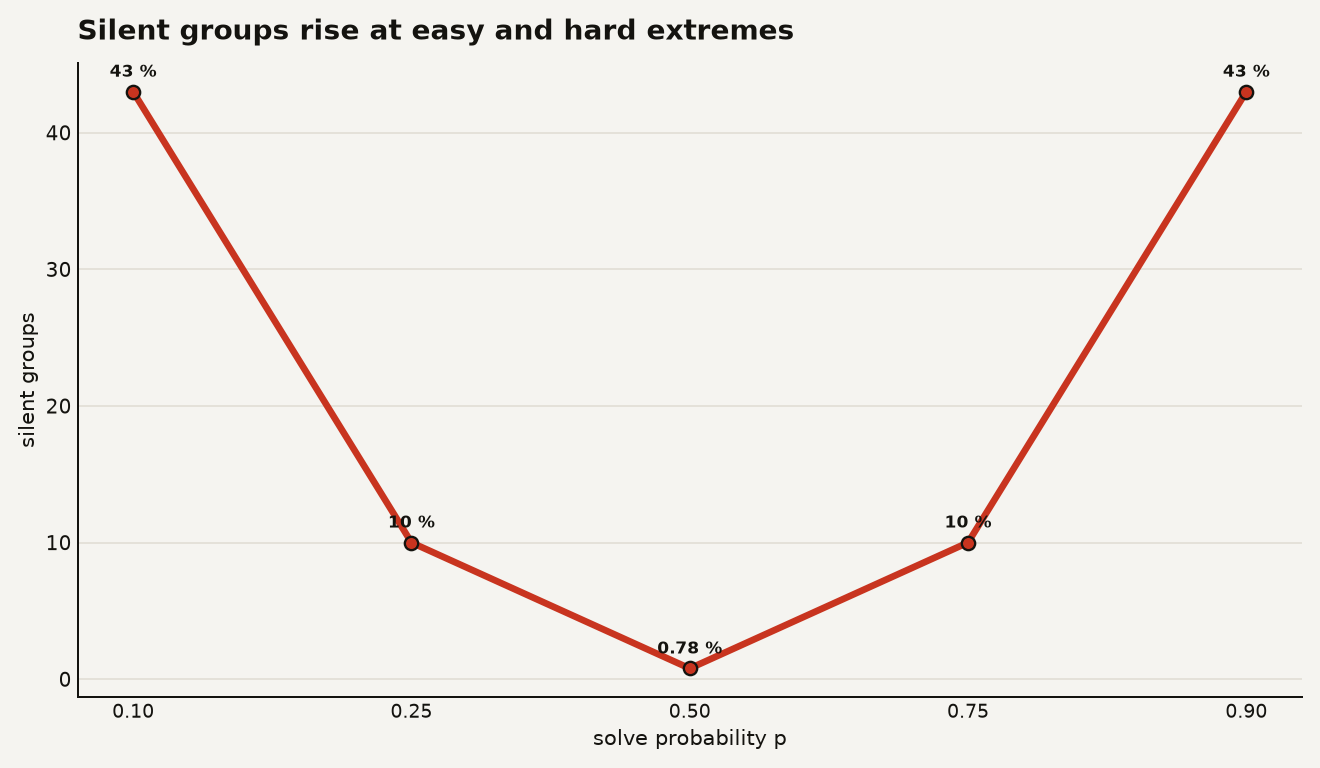
At group size 8, 44 percent of Big-Math prompts go silent, Bay and Yearick show, making GRPO standard deviation the update-size dial.